
Summary
- WAIS joined server-local indexes through a client protocol, while users first needed a source description or directory entry that pointed them to the database to search.
- Project updates counted 44 servers in July 1991 and 80 in October; the figures show rapid contribution, not a complete or independently audited global catalogue.
The difficult part of a network search could come before the query. On 31 July 1991, Brewster Kahle announced WAIS Beta 2 and described 44 servers. A user still had to know which one held the material worth searching.
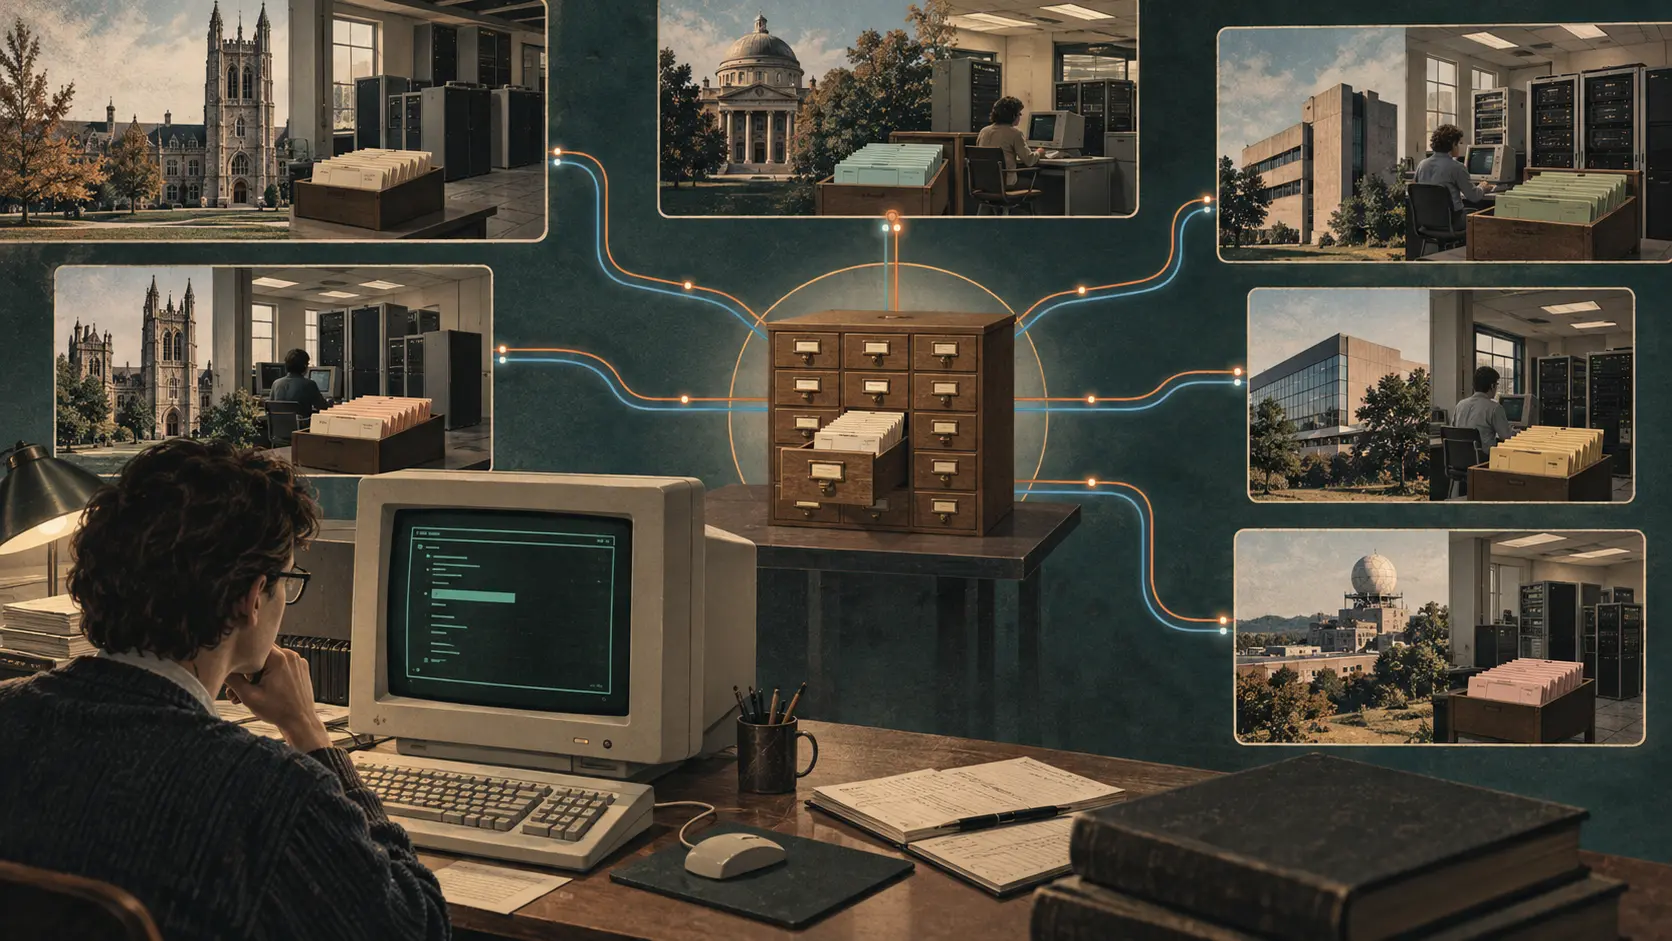
WAIS addressed that gap with a second kind of searchable object: the directory of servers. The Beta 2 announcement included the directory among the Quake servers and described software for creating indexes from local files. A source description gave a client a named destination; the server searched its own database. The arrangement let an institution publish a searchable collection without first merging every document into one network-wide index.
The directory was therefore a locator for indexes, not a substitute for them. In October, a WAIS-discussion announcement reported 80 servers across four countries on three continents and listed newly added sources: a FidoNet node list, robotics material, an Australian resource guide and FAQ collections. Those examples reveal the work behind discovery. Someone had to prepare a source, make it reachable and tell the shared directory that it existed.
A preserved W3 overview later called the directory a “master index of indexes.” It reported more than 80 indexes but also said a WAIS search could return at most 40 results. The W3 comparison with WAIS described a further usability limit: a WAIS user could search the master directory, but could not simply follow links from an overview to browse among indexes. A Web gateway could add that kind of linked overview; it was an additional view, not a property of the WAIS client itself.
By 1994, RFC 1580 described the directory-of-servers database as available at several sites and advised users to query it for databases on a subject. This later guide makes the sequence explicit: discover a source, select it, then search it. It does not establish that every source was listed or that the directory was always current.
The design made local publishing compatible with common retrieval. It also left a coordination task outside the query protocol. The project’s counts document participation as its organizers reported it; they do not measure how many databases remained invisible, how often entries went stale, or whether users could find the right source. WAIS could search a database once selected. Finding that database remained a separate layer of the system.
Sources and limits
- WAIS Beta 2 announcement, Brewster Kahle, 31 July 1991
- WAIS discussion digest 31, 17 October 1991
- W3 historical WAIS source overview and preserved source list
- W3 FAQ: WAIS, Gopher and WWW
- RFC 1580, Guide to Network Resource Tools (March 1994)
The 1991 server totals are project announcements, not an independently audited census. The W3 pages are a later preserved snapshot, not a complete inventory of WAIS deployment. The 1994 RFC describes later practice and is not evidence that every 1991 client behaved identically.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance