Summary
- Project Honey Pot assigned a unique email address to a recorded web visit, linking later incoming mail to the earlier harvesting event.
- Volunteer websites exposed the addresses; central servers kept the records and received the mail, creating material for research into harvesting and sending.
On 9 December 2009, a fake tax message arrived at an inbox that was delighted to receive it. The supposed taxpayer had no taxes to pay. The address was a trap.
Project Honey Pot's report that month called it the project's billionth email spam message. The address had been harvested from the web on 4 November 2007. A message masquerading as Internal Revenue Service business had brought back a useful piece of history: the recipient address connected it to that earlier visit.
The operation had opened to public volunteers on 14 October 2004, according to its creators' 2005 research paper. Website administrators could install a page that offered email addresses to visiting crawlers. The attractive nuisance came with a memory.
One address, one exposure
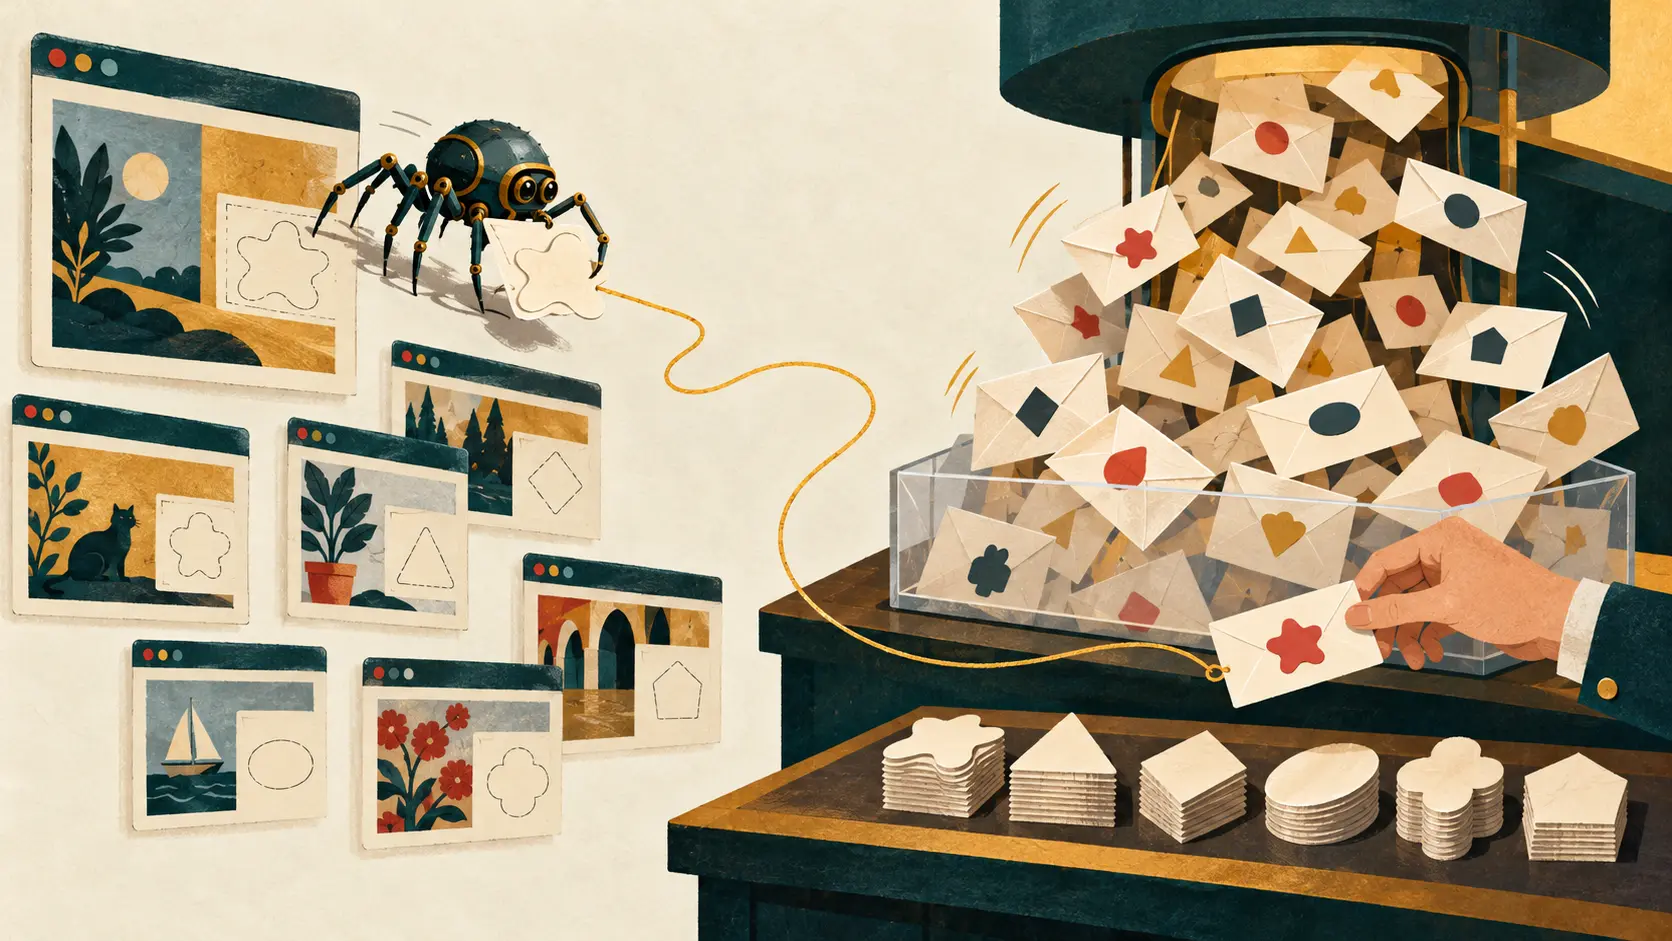
When a visitor reached the page, the local script contacted the project's central servers. It supplied the visitor's IP address, browser identification string and referring page information. The central service recorded the visit and time, then issued a unique email address.
That address appeared only once. It looked ordinary enough to collect, but the project had already attached it to a particular exposure. If mail later arrived for it, the receiving system could connect two events: somebody collected this address here; a sender subsequently used it.
An incoming message already supplied information about its delivery. The decoy recipient added a route back to acquisition. The inbox could ask a question that an ordinary recipient often asks in vain: where did they get my address?
The labour was divided. Volunteer websites put out the bait. Central machines assigned the addresses and handled the mail. Contributed domains, with mail routing pointed at the project, supplied room for more plausible recipients. The websites recruited the visitors; the central desk opened the correspondence.
An address can travel farther than its collector
The 2009 research by Kevin S. Xu and colleagues used these connections to study groups of harvesters with similar behaviour. It distinguished the machine collecting addresses from the server sending mail. One harvester could supply several spammers; one spammer could use several harvesters. The relationships under study ran through observed machines and their activity.
This made the recipient a useful research instrument. It connected stages of the trade even when different infrastructure performed them. The fake tax message in December 2009 showed why keeping old exposure records mattered: an address encountered in 2007 was still carrying a traceable history.
There was plumbing to maintain beneath the trick. The project's current FAQ describes mail going directly to its servers, including mail for donated subdomains. It also explains that withdrawing a domain donation causes the previously distributed addresses to bounce. The attractive addresses need a working destination if they are to keep reporting back.
Project Honey Pot turned a web page into the start of a correspondence experiment. The collector took an address; the project kept its receipt. Every unwanted message could then contribute something its sender had probably never intended to provide: an account of the address's travels.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance