Summary
- RIPE NCC opened an investigation into intermittent access to resource information in its LIR Portal at 15:55:39 CET on 3 November and marked the incident resolved at 16:50:45. That is a 55-minute public reporting interval, not a measured duration of failed requests.
- Its 17:17 postmortem attributes the impact to a load-balancer failover that left applications using the database with stale connections. Staff cleared those connections and promised to review connection-pool configuration and improve connection-usage monitoring.
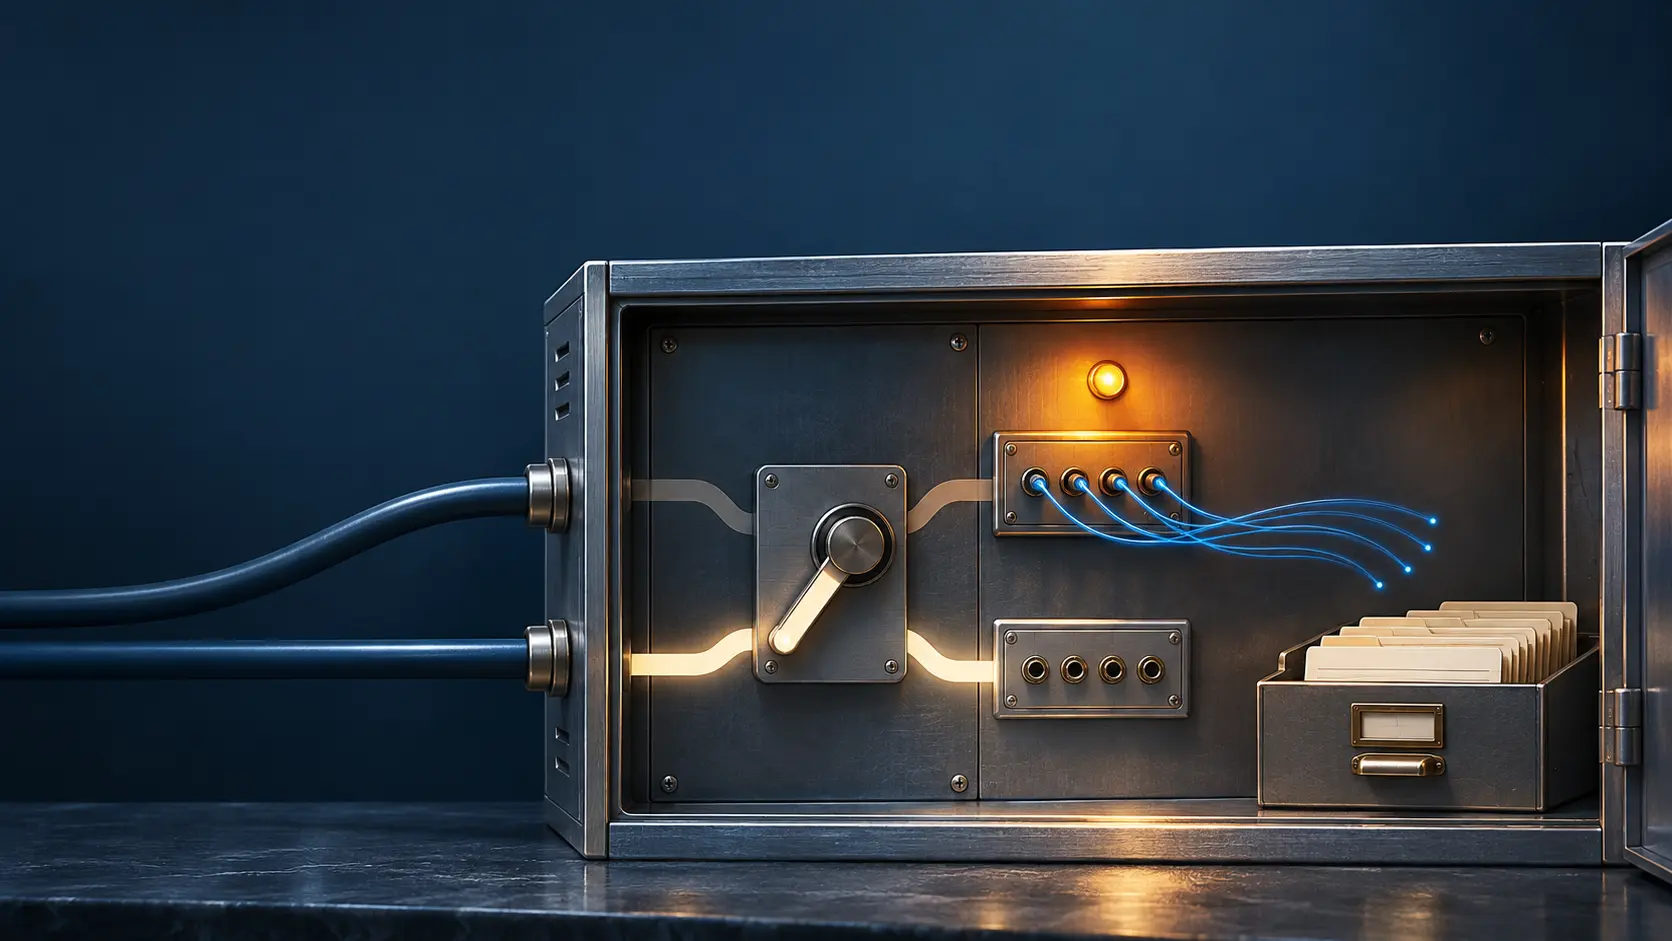
The load balancer switched. The application kept a memory of the old road. That is the picture in RIPE NCC's own incident report: database-using applications were affected by a load-balancer failover; clearing stale connections relieved the immediate problem. Nothing in the report says which component triggered the failover. The failure it does name sits at the join between a switch and the software expected to follow it.
RIPE NCC began publicly investigating intermittent access to resource information in the LIR Portal at 15:55 CET on 3 November. Its timestamped incident API records 15:55:39.649 for investigation and 16:50:45.437 for resolution. The interval between those updates is 55 minutes and almost six seconds. There is no public per-request failure series, so the incident clock describes the operator's reporting window, not a stopwatch placed on each member's screen.
That distinction matters because this was a resource-information access problem, not a generic website banner. The LIR Portal is where a RIPE NCC member looks up its IPv4 and IPv6 resources and ASNs. In an October staff account of the developing My Resources interface, RIPE NCC describes the work members do there: examining allocations and assignments, registration details, utilization, database objects and routing information. The redesign's tree, checks and side panels were still being developed and tested; the existing need to see resource information was already real.
A registry has two promises to keep in that moment. One is custody of the record. The other is a usable path through which the member can see and act on the record. A member cannot inspect a prefix merely because the database survives somewhere behind a failed session. The official report identifies the path problem precisely enough to avoid vague talk of “systems”: a load-balancer failover happened, applications retained stale database connections, and staff cleared them. A spare lane that the driver cannot enter offers a handsome diagram and a poor journey.
RIPE NCC's postmortem names two longer-term tasks. Reviewing connection-pool configuration addresses how application connections should be recycled after the underlying route changes. Better connection-usage monitoring addresses whether the operator can see when those applications keep reaching for dead sessions. These are different jobs. The first changes behavior; the second tells staff whether the behavior has changed in practice. The report gives no completion date or acceptance test for either.
The missing public facts are the failover trigger, the count of affected members and requests, and evidence that a later failover was tested from the member's resource view. Those facts would tell readers how broad the event was and whether the promised repair closes the same gap. For now, the published result is narrower and sharper: RIPE NCC restored the Portal by clearing stale connections after a load-balancer failover, then put connection pooling and monitoring on its worklist.
RIPE NCC originals
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance