Summary
- At RIPE 93, RIPE NCC CTO Sjoerd Wolthers showed a plan to replace the registry's stretched Layer-2 arrangement across two nearby data centres with two full, autonomous Western European sites. The design calls for active-active systems within each centre and active-standby operation between them.
- The proposed stack includes separate networks, Proxmox and independent Ceph clusters at each site, encrypted inter-site circuits and backups at a third location. Detailed design and procurement are under way; completion is targeted for the second half of 2028.
Two buildings can share an address, a switch fabric and a bad day. RIPE NCC's current design brings two nearby data-centre locations together through one network and a stretched Layer-2 arrangement. Its CTO, Sjoerd Wolthers, put that simplified picture on slide five of his RIPE 93 presentation. The new picture, on slide 15, gives each centre its own network, compute and storage. The line between them remains; the assumption that the two rooms can behave like one local room is what the plan intends to retire.
That is a more consequential change than a shopping list of servers. A stretched network lets equipment in separate buildings inhabit one Layer-2 domain. It is convenient when services move or share infrastructure nearby. It also makes it harder to explain, from the building count alone, which failures stay in one room. RIPE NCC's slides identify interdependencies, ageing hardware, link speeds nearing limits, storage and backup constraints, and virtualization lock-in as reasons for renewal. They do not report a failure caused by the present architecture.
The practical claim is forward-looking: separate the facilities so that the next fault has fewer places to travel.
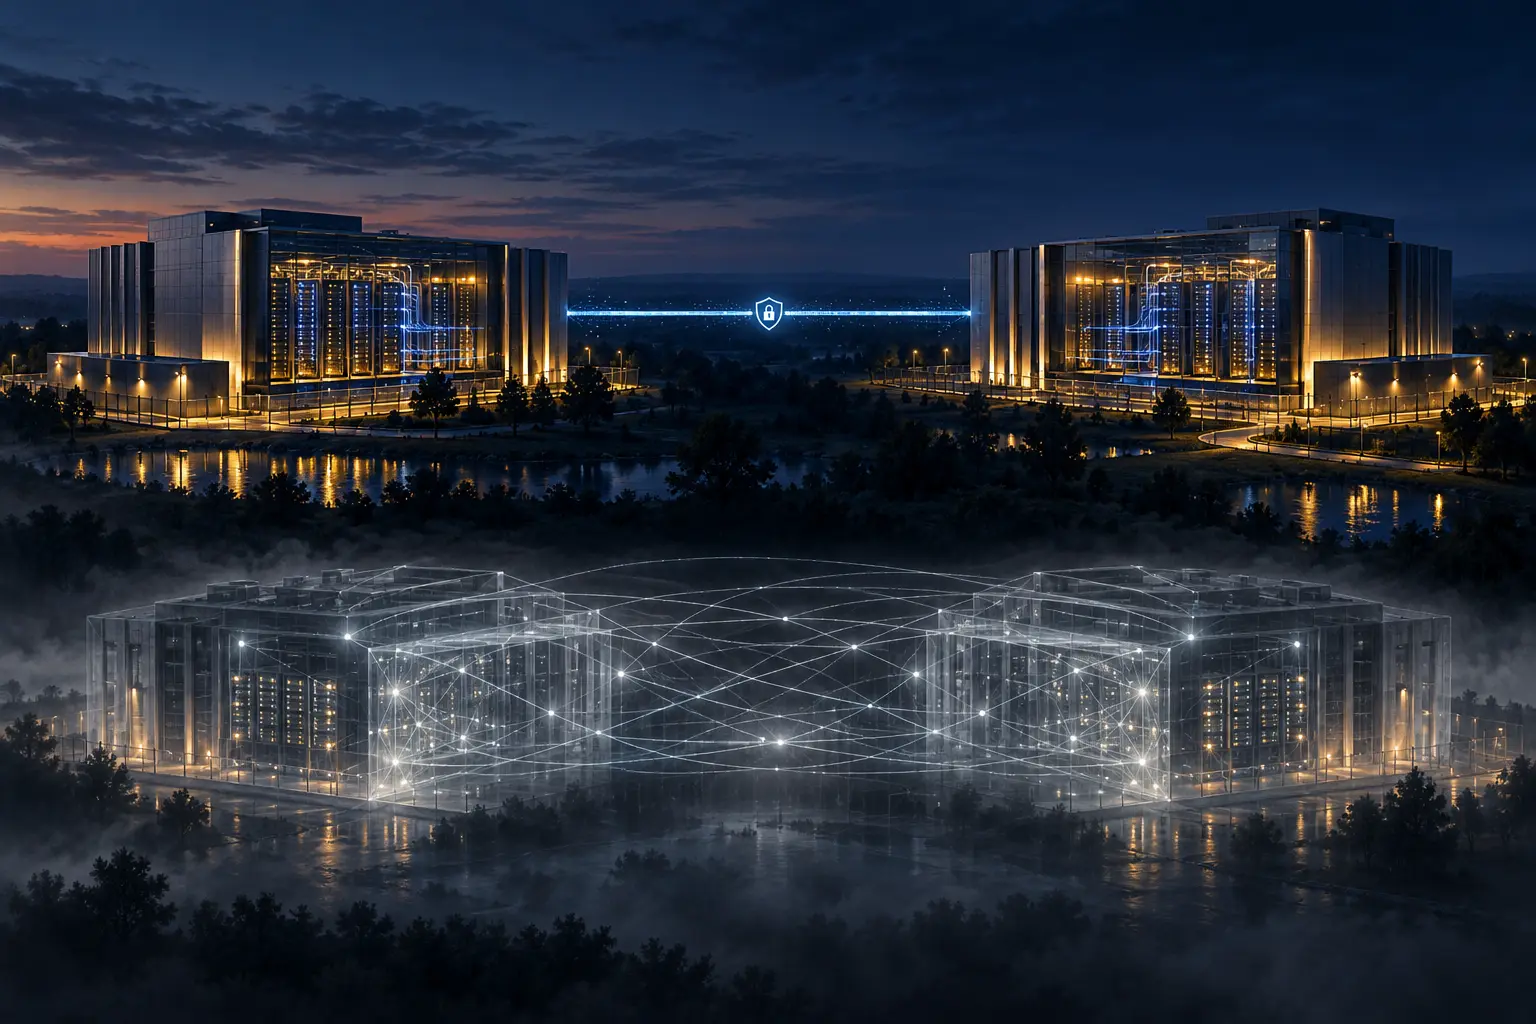
The proposed geography is precise enough to matter. The official talk describes two full data centres in Western Europe, built from a standard template that could be repeated at further sites. Each would have N+1 capacity and an active-active arrangement inside the facility. Across the two centres the design is active-standby, chosen to manage latency over distance. Rented high-speed circuits would carry encrypted traffic between them. A global service load balancer is part of the plan for regional failover.
Active-standby has an honest price: someone has to say when the standby becomes active. The data centre can be ready while an application is still holding yesterday's state. A switch can change the route to a service while an in-flight update is being committed elsewhere. Those are design questions for any stateful system, not claims that RIPE NCC has mishandled one. For a number registry, the point is especially sharp. The public service is a set of authoritative records and publication paths, not a tour of identical racks.
A transition succeeds when the right service can resume with the right state and the outside world can tell which copy is authoritative.
Wolthers' slides name the intended building blocks. Separate networks per centre replace the shared layout. The network design includes a collapsed core, redundant firewalls, routers, switches and application delivery controllers, application-tier segmentation, infrastructure-as-code configuration, IPv6 support, a default-deny firewall and an on-premise web application firewall. Compute would move toward Proxmox; Ceph would supply independent clusters in each centre, with both hyperconverged storage and a SAN role.
This is a proposed architecture, and the paper gives no claim that the named products have been installed for every registry service.
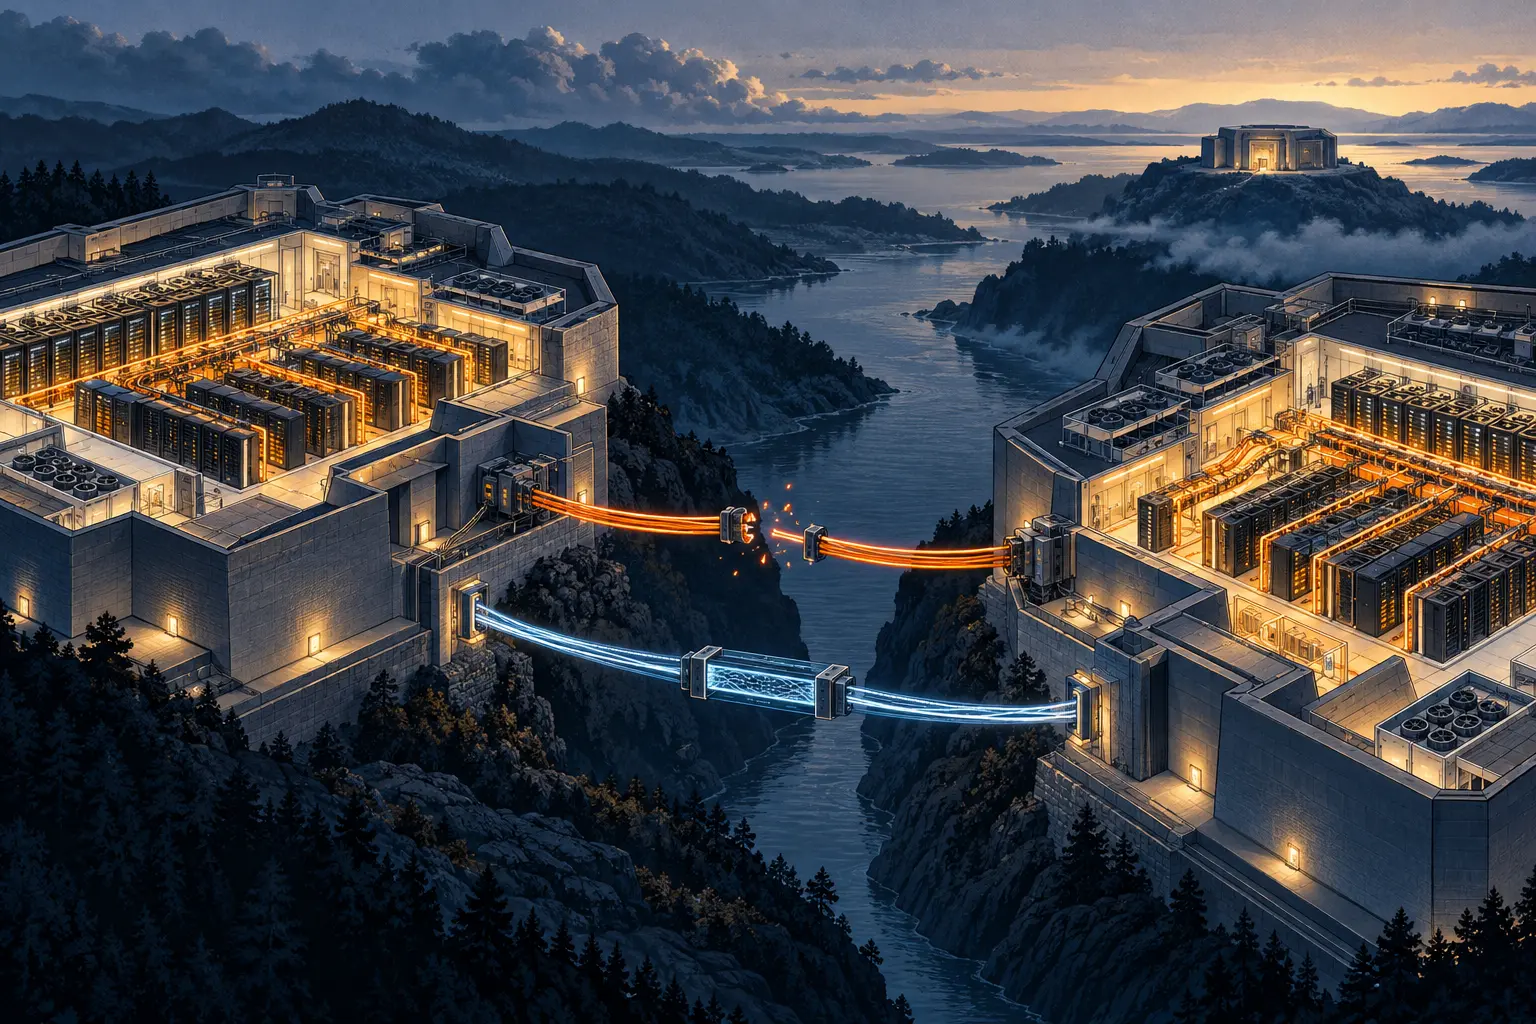
The third location is there for the event a pair of halls cannot solve by taking turns. The backup slide proposes encrypted, immutable copies under a 3-2-1-1-0 strategy, Ceph-volume replication between the two centres according to recovery-point needs, and backups sent to a third site. It also separates virtual-machine backup, short-recovery-point storage and protection for physical servers and Ceph volumes. This is more specific than saying “redundant” over a diagram.
A standby site and a recoverable copy answer different questions: one keeps a service available; the other gives an operator a point to return to after damaged state has travelled.
The schedule keeps the stakes in view. RIPE NCC says the existing architecture has been assessed and the requirements defined. Detailed designs are being developed; sites and equipment are being selected and procured. Installation comes before application teams migrate services. The target is the second half of 2028. The public slides give no per-service promotion rule, numeric recovery point, restore time or test result. A dated cutover record for each core service, showing the state source and switchover sequence, would turn the drawing into operational evidence.
RIPE NCC began this argument earlier. Its June explanation of the investment says the organisation's 2019 cloud-first push gave way to renewed concern about external-provider reliance, technical debt and the need for self-hosted capacity. The RIPE 93 presentation supplies the missing physical grammar. The move is from two close rooms linked as one to two sites expected to stand on their own. The hinge is no longer hidden in a budget row. It sits between the active hall and the standby one, waiting for a real service to cross.
Sources: RIPE 93 official presentation; RIPE 93 talk page; RIPE NCC's June infrastructure explanation.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance