
Summary
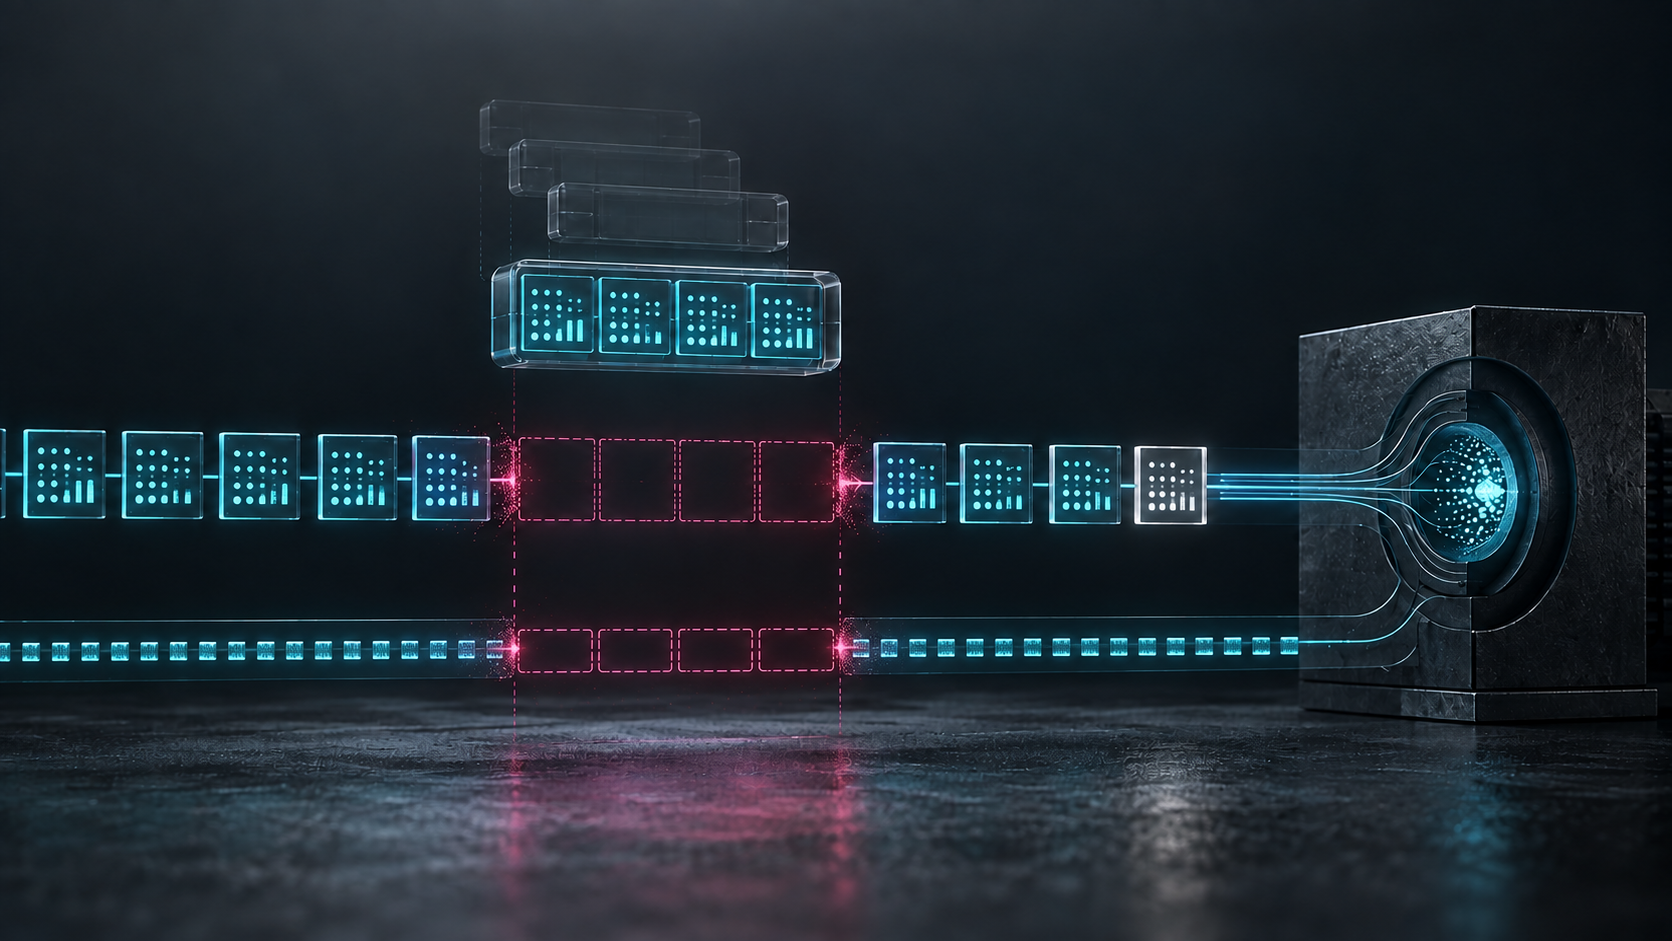
- RFC 3557 packages fixed 20 ms distributed-speech-recognition frame pairs into RTP. More pairs per packet reduce RTP/UDP/IP header overhead but increase aggregation delay and make one packet loss erase a longer consecutive feature interval.
- The 4-bit CRC of a received frame pair, a Null FP at a transmission-segment boundary and an RTP timestamp each prove a bounded protocol fact. None proves that all prior features arrived, the engine ingested them, recognition succeeded or the application acted correctly.
Network optimization often counts objects that recognizers never see. A packetizer sees headers, bytes and datagrams. A speech engine sees a time-ordered feature sequence. The same design choice can improve the first view and damage the second without either metric being false.
RFC 3557, published in July 2003 as a Proposed Standard, defines an RTP payload for the ETSI ES 201 108 distributed speech-recognition front end. It does not report an outage or benchmark. Its value for governance lies in a precise trade: the number of feature pairs placed in one datagram determines both overhead and the duration placed inside one loss event.
Twenty milliseconds is the atomic semantic unit
The front end emits a 44-bit quantized feature vector every 10 ms. Two consecutive vectors form one Frame Pair, or FP, representing 20 ms of original speech. A four-bit CRC is added, followed by four zero pad bits, making each FP exactly 96 bits or 12 octets.
That shape gives the payload a useful internal boundary. A receiver can parse an integral series of FPs and check the CRC of those it actually received. It can associate the RTP timestamp with the first represented sampling instant and advance time by 160, 220 or 320 samples per FP at 8, 11 or 16 kHz.
The boundary is also easy to overstate. The CRC is only four bits and applies to the FP. It is not source authentication, a lost-packet detector, a recovery code or a recognition receipt. A clean CRC says that the received bits satisfy that check. It cannot testify for an FP that never arrived.
Audit records should therefore name both the content unit and the transport unit. The FP has its own identity, capture interval and CRC. The RTP packet has a sequence number, timestamp and list of included FPs. Conflating them makes a one-packet gap look like one missing semantic unit even when the packet carried four.
Aggregation moves the failure boundary
Putting fewer FPs in each RTP packet reduces waiting time at the packetizer and limits the duration destroyed by one datagram loss. It also sends more RTP, UDP and IP headers for the same speech interval.
Putting more FPs together improves header efficiency. It requires the sender to wait longer before emitting the packet, increasing recognition latency. More importantly, one lost packet removes more consecutive FPs. RFC 3557 notes that most speech recognizers have difficulty with the loss of a large consecutive run.
This is not a universal claim that small packets are better. A constrained link can make excess headers expensive; frequent tiny packets can increase processing and contention. The standard's advice is conditional: minimize the number of FPs subject to the application's bandwidth-efficiency requirements and consider header compression.
The governance mistake is to let the network metric settle the decision alone. Header bytes saved are visible immediately. Recognition degradation appears later, perhaps in confidence, retries or an application error. Unless the packetization version travels with those observations, the organization cannot connect cause to outcome.
maxptime is a risk setting, not decoration
The media registration lets a session express maxptime, the maximum media duration carried in one packet. It should be a multiple of the 20 ms FP size. If absent, RFC 3557 assumes 80 ms. A user expecting a high packet-loss ratio may select a shorter value.
At 80 ms, four FPs can share the payload. Compared with one FP per packet, that can avoid three sets of transport headers. It can also turn one datagram loss into four consecutive missing pairs. Both statements describe the same configuration.
The parameter belongs in an operating record with the expected loss regime, available header compression, latency budget, engine tolerance, sender implementation and effective time. A session description showing maxptime=80 is only a declared constraint. It does not prove the packetizer complied, the network delivered packets within it, or the engine accepted the sequence.
Monitor the observed media duration per packet rather than trusting metadata. If the sender exceeds the declared maximum, the evidence should show both the policy violation and the actual enlarged interval at risk.
Header compression changes the choice set
RFC 3557 points to IP/UDP/RTP header-compression techniques such as RFC 2508 and RFC 3095. That matters because aggregation is not the only way to improve efficiency.
If compression is available and healthy, an operator may preserve shorter payload intervals while reducing header cost. If compression context is absent, stale or repeatedly repaired, the apparent alternative may not be operationally equivalent. The packetizer decision should therefore cite compression capability and observed compression state, not a theoretical feature flag.
RFC 2198 supplies neighboring redundant-audio context, but redundancy is not implicit in this DSR payload. Packing more primary FPs into one packet does not create a second copy. A lost datagram can remove the entire aggregated interval.
Null FP closes a sender-side segment, not the evidence chain
RFC 3557 also supports discontinuous transmission. The front end sends FPs only when it detects speech. An unbroken speech interval is a transmission segment, which can include speech and non-speech FPs.
The sender decides that the segment has ended after consecutive non-speech frames exceed a hangover threshold. The RFC describes 1.5 seconds as a typical value; it is not a universal optimum. After all FPs in the segment are sent, the front end should send one or more Null FPs.
A Null FP zero-fills the two feature frames, applies the normal CRC and padding, and acts as an in-band boundary indication. It can tell the receiver that the sender considers the segment complete. It cannot fill a sequence gap immediately before it.
This is the dangerous clean ending. The engine may receive a valid Null FP after losing the packet that contained the final 80 ms of actual features. If the application treats the boundary as proof of completeness, the strongest surviving signal hides the missing interval.
Keep separate receipts for speech detection, hangover state, last real FP, every Null FP attempt, RTP arrival, gap classification and the engine's close decision. A close marker may close timing; it must not close uncertainty.
Recognition begins after transport has finished speaking
The purpose of DSR is to deliver a representation tailored to a speech engine rather than send ordinary vocoded audio and ask the engine to reconstruct features. That architectural choice can improve the input available to recognition. It still leaves several downstream decisions.
The engine has to depacketize, order, identify gaps, validate received FPs, conceal or reject missing intervals and decide when a segment is complete. Only then can a particular model produce a hypothesis, confidence or error. The application must decide whether that hypothesis is sufficient for an action.
An RTP receive log cannot report those later results. An engine-ingestion event cannot prove correct recognition. A recognition result cannot authorize a financial, access or safety-sensitive action without the application's own policy and, where required, human confirmation.
The smallest defensible statement is layered: these FPs were produced; these packets carried them; these packets arrived; this gap remained; this engine ingested this sequence; this model emitted this hypothesis; this policy allowed this action; this outcome was observed.
Evidence boundary
This Article names no user, voice, language, terminal, engine, model, vendor, operator, service, incident or affected population. It asserts no deployment, packet-loss rate, recognition score, optimal aggregation level or measured benefit. The 80 ms example follows the RFC's default maxptime and fixed FP duration; it is not a report of production behavior.
RFC 3550 and RFC 3551 bound RTP behavior. RFC 2327 is the SDP context used at publication; RFC 8866 is later status context. RFC 2508 and RFC 3095 are compression alternatives named by the document. RFC 2198 is neighboring redundancy context, not evidence that RFC 3557 packets carried redundancy.
Heng Lu's Running-Code Primacy and Minimum Initial Specification essays are disclosed editorial lenses. They motivate separating a standardized payload from running packetization and observed recognition, and keeping the shared format small while local owners remain accountable for later decisions. They are not evidence of the RFC authors' intent or a network event.
The bounded conclusion is exact: larger DSR payload aggregation can save headers while exposing a longer consecutive feature interval to one packet loss. The protocol fields can identify and delimit that event; only downstream receipts can show what the engine recognized and what the application did.
Sources
- https://www.rfc-editor.org/rfc/rfc3557.html
- https://www.rfc-editor.org/info/rfc3557
- https://datatracker.ietf.org/doc/rfc3557/
- https://www.rfc-editor.org/rfc/rfc3550.html
- https://www.rfc-editor.org/rfc/rfc3551.html
- https://www.rfc-editor.org/rfc/rfc2327.html
- https://www.rfc-editor.org/rfc/rfc8866.html
- https://www.rfc-editor.org/rfc/rfc2508.html
- https://www.rfc-editor.org/rfc/rfc3095.html
- https://www.rfc-editor.org/rfc/rfc2198.html
- https://www.rfc-editor.org/rfc/rfc8174.html
- https://heng.lu/running-code-primary-the-patch-needed-to-preserve-the-internet-original-design/
- https://heng.lu/minimum-initial-specification-localized-future-decision-voluntary-adoption-internet-coordination-system/
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance