
Summary
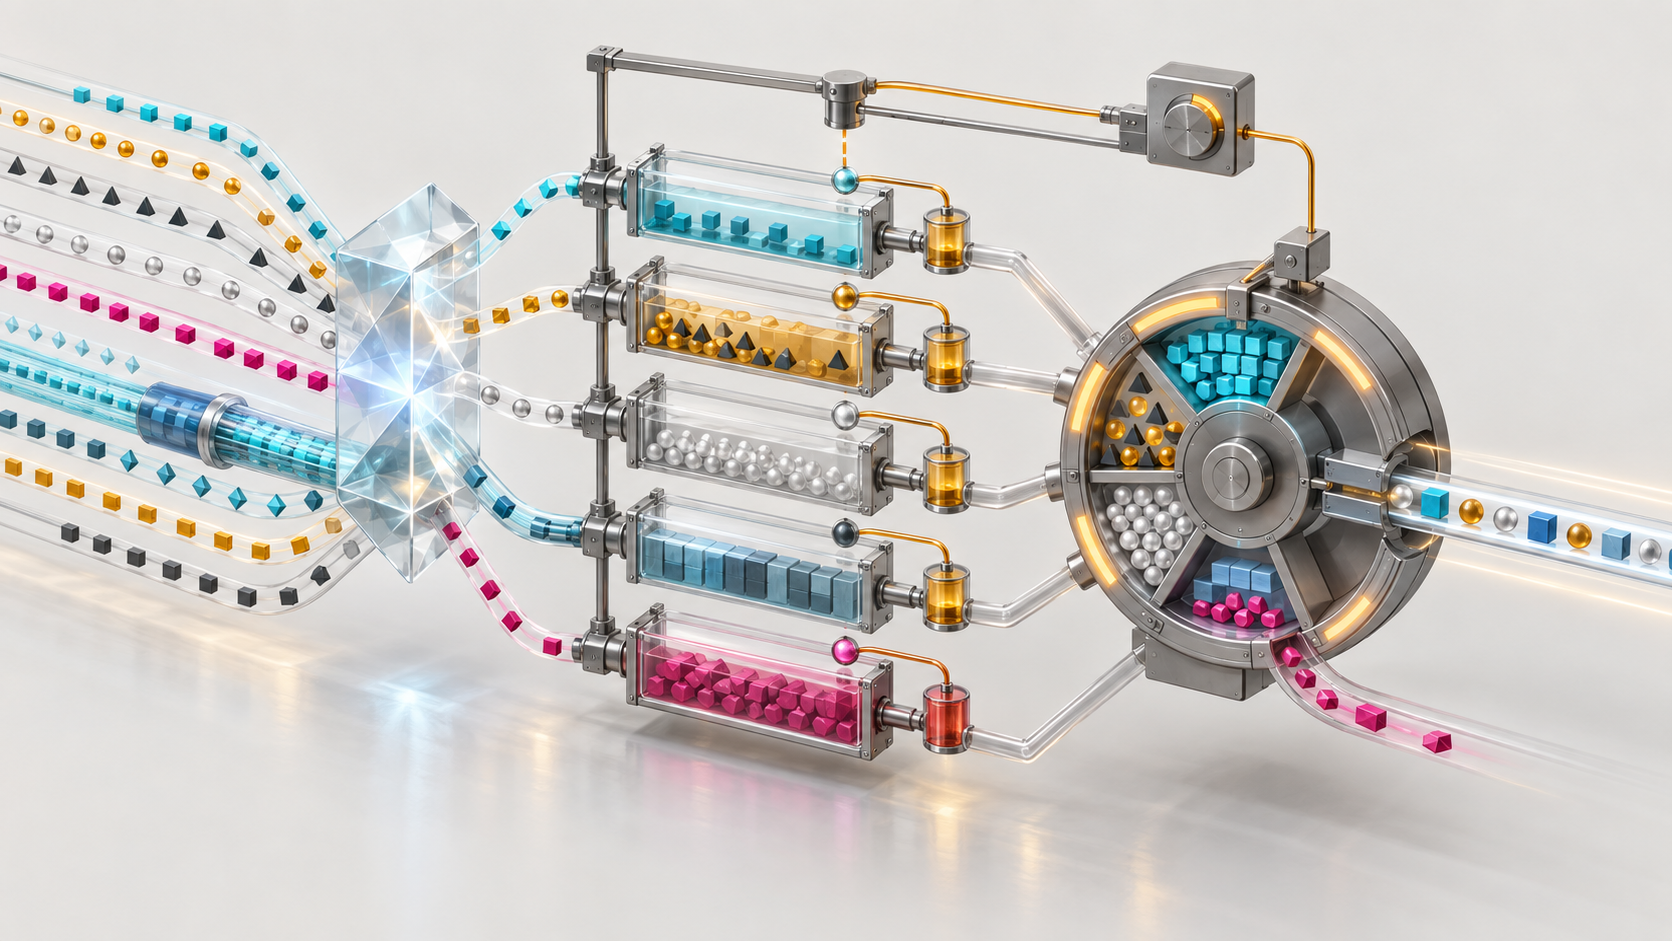
- FQ-PIE hashes packet five-tuples into finite queues, applies PIE congestion control per queue and uses a deficit-round-robin-derived scheduler to serve them.
- A queue bucket is not a customer or application identity: flows can collide, tunnels can bunch many sessions into one visible flow, and one actor can create many five-tuples.
- Operators need separate receipts for classification, controller state, scheduler service, the chosen fairness unit and the end-to-end outcome.
Eight flows and one
Two customers start transfers through the same constrained interface. The first application opens one long connection. The second opens eight. The scheduler visits every active flow queue according to its deficit and quantum. Its local accounting can be internally consistent: no queue is starved, queue delay is controlled and the output link remains busy.
Calling that result “customer fairness” would add an identity the algorithm never observed. The second customer presented eight schedulable objects and the first presented one. Flow-level isolation can be exactly what the implementation promised while aggregate service between customers remains intentionally or accidentally unequal. Neither the packet headers nor a green latency chart names the constituency management meant to protect.
Revision 02 of the IETF TSVWG draft Flow Queue PIE makes the local mechanism concrete. FQ-PIE combines flow queuing with the PIE active queue management algorithm. Incoming packets are classified by hashing the protocol number, source and destination addresses, and source and destination ports. The queues are served by a deficit-round-robin-derived scheduler. PIE manages congestion at enqueue.
Those are powerful controls. They are also narrower than a business or governance claim about fairness.
A bucket is an operational address, not an identity
The goal of flow queuing is to isolate competing flows. A practical implementation does not need an unbounded queue for every possible five-tuple; it can hash flows into a finite table. That introduces a distinction between the observed flow key, the hash result and the queue bucket.
Different five-tuples can collide in one bucket. RFC 8290, the FQ-CoDel specification whose scheduler model FQ-PIE follows, quantifies collision probability for its example table and notes that the calculation assumes a hypothetical perfect hash. A collision does not make the two flows the same. It makes them share queue state and scheduling treatment until classification changes.
The reverse problem also matters. One customer, host or application can generate many five-tuples and occupy many buckets. Counting active queues therefore cannot establish the number of customers. Treating each bucket equally cannot establish equal treatment of people, accounts, applications or autonomous systems.
Every operational record should retain the classifier inputs, the hash or perturbation epoch, the table size and the selected bucket. Without that provenance, a later analyst sees only a queue number and may mistake a transient implementation address for a durable subject.
Encryption changes the visible unit
Opaque encapsulation can bunch many inner flows into one visible outer flow. RFC 8290 warns that encrypted VPN traffic may be impossible to decapsulate for classification. The inner sessions then share one queue and one drop behavior, while a clear-text neighbor may occupy several queues.
This is not automatically wrong. At one boundary the tunnel may be the desired unit. At another, the operator may have intended per-subscriber or per-application treatment. The point is that fairness cannot be inferred until the unit is declared. “Per-flow” is not a universal moral or commercial category; it is a property of the fields visible at one observation point.
The evidence record therefore needs tunnel context and, where legitimate and privacy-preserving, a separate mapping from operational subjects to visible flow keys. That mapping is outside the FQ-PIE bucket itself. Exposing inner identity merely to improve scheduling can create its own privacy and security costs, so the control decision needs an explicit boundary rather than an assumption.
PIE controls a queue with sampled state
After classification, FQ-PIE passes the packet to PIE. The controller maintains a drop probability based on the difference between measured queue delay and a target, plus the direction in which delay is moving. RFC 8033 uses 15 milliseconds as an example target and 15 milliseconds as the default update interval.
A target is not a guarantee for every packet. PIE deliberately tolerates short bursts. Its example burst allowance lets arrivals bypass random dropping for a bounded period even when the instantaneous delay moves above target. A report that treats every above-target sample as controller failure would misunderstand the design; a report that treats the target as a delivered service-level objective would overstate it in the other direction.
The measurement method matters too. PIE can estimate delay from queue length and dequeue rate using Little's Law, or it can use packet timestamps. The FQ-PIE draft explains why a per-queue rate estimate can be unreliable: movement from a host queue into a device-driver transmission ring is not necessarily transmission on the outgoing link, and an accurate rate for each queue is difficult to obtain. It therefore says direct timestamp measurements should be used.
Even a direct timestamp needs provenance. The draft permits the probability update to use the delay of the most recently dequeued packet. That sample can be authentic and still be old relative to a sudden arrival burst or link-rate change. Queue identity, measurement points, sample time, sample age, current and previous values, and the controller update time belong together.
A mark is a local decision, not a transport result
FQ-PIE may mark an ECN-capable packet rather than drop it, following PIE guidance. The mark/drop branch depends on packet capability, configured thresholds, current probability and implementation choices. When total packet capacity is already saturated, the draft says the arriving packet is dropped without further processing.
Neither event is an end-to-end receipt. An ECN mark proves that the local node changed a field under a particular policy. It does not prove that the receiver reflected the signal, that the sender reduced its rate, that another downstream queue was clear or that an application improved. A drop proves local non-admission, not which customer caused congestion or whether a “fat flow” was punished.
FQ-PIE notably does not copy FQ-CoDel's saturated-limit procedure of finding the largest byte-count queue and bulk-dropping from it. The draft argues that bulk dropping could underutilize the link because PIE already acts at enqueue. The absence of a largest-queue attribution should remain visible. A capacity drop is not a blame certificate.
Scheduling service is not completion equality
The DRR-derived scheduler uses a quantum to decide how many bytes a queue can transmit during a round. A queue visit, positive deficit and dequeued bytes provide strong evidence that the scheduler served that bucket. They do not prove equal flow completion time. Packet sizes, round-trip times, congestion-control behavior, application demand, downstream bottlenecks and the number of flows per subject all remain relevant.
The same distinction applies to utilization. A busy output link can coexist with a colliding sparse flow, a tunnel containing many sessions and one application spread across numerous queues. Aggregate success can hide distributional failure; distributional balance at the queue can coexist with failure elsewhere in the path.
For that reason, an operations dashboard should not collapse bucket count, mean queue delay, link utilization and customer experience into a single fairness indicator. Each denominator answers a different question.
Experimental status and running code
The current draft is dated 6 July 2026 and expires 7 January 2027. Datatracker identifies it as an active TSVWG Working Group document with IESG state I-D Exists; the draft text describes intended status Experimental. It is not an RFC.
The draft reports implementations in Linux, FreeBSD and ns-3 and describes their timestamp behavior at the time of writing. That is relevant running-code evidence. It does not prove that a particular production interface selected FQ-PIE, which build or parameters it uses, whether offload moves the measurement boundary, or what users observed.
The document itself lists open experimentation: interactions with BBR, mark-to-drop thresholds, suitable PIE enhancements, short-flow isolation and latency, RFC 7928-style scenarios and alternative hashing mechanisms. These are research questions, not completed results. Leadership should preserve them as uncertainties rather than convert implementation availability into a verdict of superiority.
Sources
- https://datatracker.ietf.org/doc/draft-ietf-tsvwg-fq-pie/
- https://datatracker.ietf.org/doc/draft-ietf-tsvwg-fq-pie/history/
- https://datatracker.ietf.org/doc/draft-ietf-tsvwg-fq-pie/references/
- https://datatracker.ietf.org/doc/draft-ietf-tsvwg-fq-pie/referencedby/
- https://www.ietf.org/archive/id/draft-ietf-tsvwg-fq-pie-02.html
- https://www.ietf.org/archive/id/draft-ietf-tsvwg-fq-pie-02.txt
- https://www.ietf.org/archive/id/draft-ietf-tsvwg-fq-pie-02.xml
- https://datatracker.ietf.org/wg/tsvwg/about/
- https://www.rfc-editor.org/rfc/rfc8033.html
- https://www.rfc-editor.org/rfc/rfc8290.html
- https://www.rfc-editor.org/rfc/rfc8289.html
- https://www.rfc-editor.org/rfc/rfc7928.html
- https://www.rfc-editor.org/rfc/rfc3168.html
- https://www.rfc-editor.org/rfc/rfc7567.html
- https://www.rfc-editor.org/rfc/rfc2119.html
- https://www.rfc-editor.org/rfc/rfc8174.html
- https://datatracker.ietf.org/doc/draft-ietf-ccwg-bbr/
- https://github.com/torvalds/linux/blob/master/net/sched/sch_fq_pie.c
- https://cgit.freebsd.org/src/tree/sys/netpfil/ipfw/dn_aqm_pie.c
- https://www.nsnam.org/docs/models/html/fq-pie.html
- https://heng.lu/on-reality-layers-symbolic-power-and-why-clarity-feels-so-hostile/
- https://heng.lu/minimum-initial-specification-localized-future-decision-voluntary-adoption-internet-coordination-system/
- https://heng.lu/running-code-primary-the-patch-needed-to-preserve-the-internet-original-design/
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance