Summary
- An RRDP failure can make validators reuse a prior cache, request a much larger snapshot or fall back to rsync; the choice is controlled by implementation and operator policy, not by a universal recovery timer.
- Repository delta retention, manifest freshness and validator thresholds distribute cost among publication services, network operators and the resource holders whose routing intentions are waiting to propagate.
- Operators need per-repository recovery receipts and independent validated-payload comparisons, not just a green endpoint monitor.
At 09:00 a validator asks an RPKI repository for the next small delta. The reference is present, but the file is not. One validator reuses yesterday’s successful cache. Another asks for the full snapshot. A third starts a delayed fallback to rsync. All three can claim to be following a defensible recovery policy; none has discovered a new ROA by staring harder at the unavailable file.
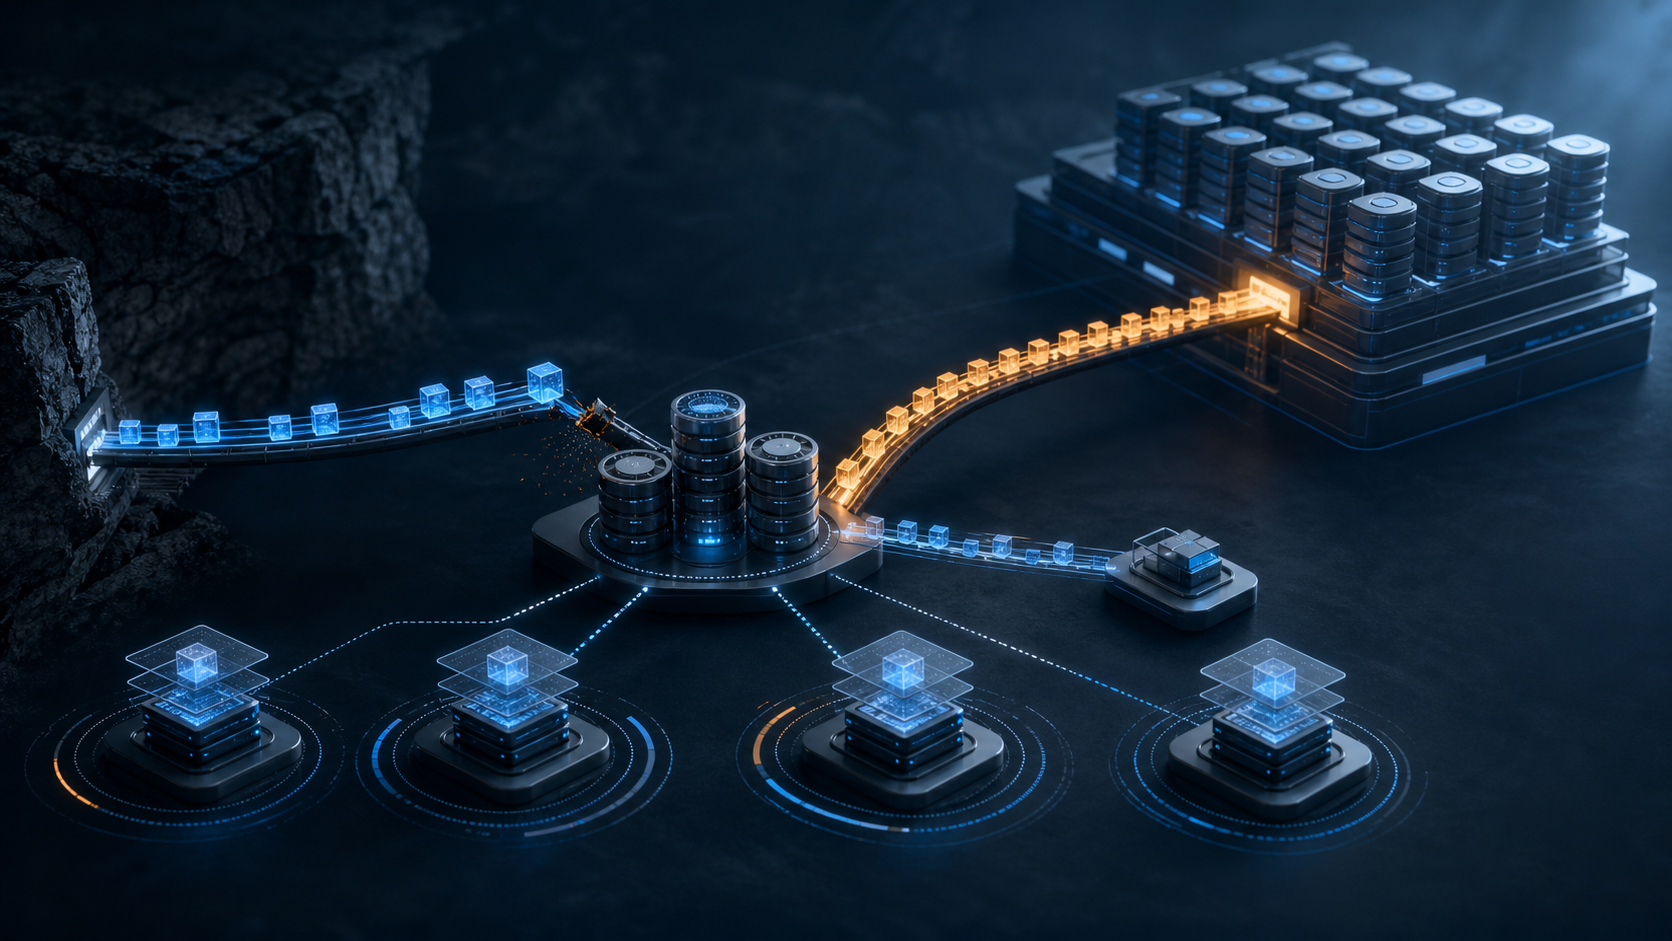
That sequence is why RPKI repository recovery is becoming a routing control surface. The Resource Public Key Infrastructure is usually explained from the signed object outward: a holder authorises an origin, a relying party validates it, and a router applies origin validation policy. The operational chain begins earlier. Signed intent has to leave a certification authority, survive publication, arrive through a repository transport, pass manifest and certificate checks, and become a validated payload. A transport incident changes the evidence available to the later steps even when every signature remains mathematically sound.
Delta, snapshot, fallback
RFC 8182 gives RRDP three useful pieces. A notification file identifies a repository session and serial. Delta files carry incremental changes. A snapshot carries a complete current view. If a validator has a contiguous delta chain, the cheap path is to apply it. If deltas are unavailable or rejected, the protocol directs the relying party towards the snapshot.
The asymmetry matters. An incremental update might be small; a snapshot can be tens or hundreds of megabytes. The latest SIDROPS publication-service draft describes the failure ladder plainly: a validator fails on one or more deltas, tries the larger snapshot, then may fall back to rsync. On the next RRDP run it will typically start with the snapshot again. A congested service can therefore respond to failure by generating more demand. The recovery object is larger precisely when the system is least able to serve it. Distributed systems do enjoy irony.
The draft is still work in progress, not an RFC. Its operational evidence is nevertheless specific. For one large repository in January 2024, a notification containing 144 deltas over 14 hours accounted for 251 GB of 55.5 TB of traffic—less than 0.5 percent. Retaining more deltas lets a lagging validator recover incrementally, but makes every notification larger.
Retaining fewer saves routine notification bytes and pushes more lagging clients to snapshots. The draft recommends at least four hours of deltas because some validators were observed synchronising only every one to two hours in 2024. There is no free retention setting, only a decision about when and where to spend bandwidth.
The validator adds another policy layer. Current Routinator documentation exposes never, stale and new policies for rsync fallback after RRDP failure. Its documented default is stale: use the local RRDP copy while it is considered current, then try rsync after a per-repository interval randomly selected between the refresh period and a maximum fallback time. The documented maximum defaults to 3,600 seconds. The randomisation spreads rsync load instead of inviting every validator to arrive at the side door together.
Routinator also documents thresholds that can alter the recovery path: use a snapshot when more than 100 deltas would be needed; treat a list longer than 500 deltas as empty; allow 600 seconds for an RRDP resource retrieval, 10 seconds for a read operation and 300 seconds for an rsync command. These are product defaults, not constants of nature. Change them and the same repository failure can become a different sequence of network requests and cache decisions.
The cache is part of the evidence
RFC 9286 explains what a validator should do after a failed fetch: use data from a previous successful fetch until a later fetch succeeds. That protects against turning an incomplete repository view into a false routing judgement. It also means repository uptime is not a binary proxy for the age of the evidence a router may eventually receive.
Manifests bound that continuity. They enumerate the objects an issuer intends to publish and help a relying party detect deletion, substitution and suppression. A manifest can reveal an incomplete or stale view; it cannot repair one. Its update times, together with CRL and object validity, make cache reuse a finite operating window.
The 2026 publication-service draft states the trade-off without pretending it can be optimised away. Longer manifest and CRL validity gives operators more time to restore service, but increases replay exposure. Shorter validity reduces that exposure and raises reissuance churn.
In one large repository, moving reissuance from every 24 hours to every 48 hours cut data usage by about half because routine manifest and CRL reissuance made up most changes. That is one repository’s observation, not a global conversion factor. It is still enough to show who owns the lever: the CA chooses the validity rhythm; the publication service and every relying party process the resulting churn.
The standards continue to clarify the recovery boundary. RFC 9981, published in May 2026, addresses the exceptional case in which a manifest number reaches its maximum. It records that implementations previously could respond differently—some accepting a replacement only after expiry, others rejecting new manifests indefinitely—and specifies a filename-based reset rule. The arithmetic makes accidental exhaustion more plausible than normal counting. The broader point is not that the event is common. It is that an underspecified recovery edge can produce different usable evidence even among conforming implementations.
Capacity and security do not fail in the same direction
Falling back to rsync can improve reachability and worsen the transport boundary. RRDP uses HTTPS and makes immutable snapshots and deltas cacheable. Rsync requires more server work per connection and lacks its own channel confidentiality and integrity. Routinator’s threat model says an on-path adversary can force a downgrade, with signed-object and manifest checks then carrying more of the defence.
NLnet Labs illustrated the capacity problem in 2020 with a deliberately prospective model: 150,000 validators polling every ten minutes would mean roughly 250 requests per second, compared with an rsync service then accustomed to about three. Those are not 2026 traffic figures. They explain why immediate universal fallback was a bad default and why today’s randomised boundary exists.
A simple sensitivity calculation shows the leverage without pretending to measure the Internet. Suppose 10,000 validators ordinarily need a 1 MB incremental transfer, while a full compressed snapshot is 100 MB. One update cycle is 10 GB if all remain incremental. If 20 percent are pushed to snapshots, it becomes roughly 208 GB: 8,000 MB of deltas plus 200,000 MB of snapshots. Retries and rsync server work sit on top. The key variable is not merely how many validators exist, but how tightly their recovery attempts are packed in time.
This is also why a repository can be “up” and still offer a defective recovery product. A load balancer can expose a notification from one backend before the referenced snapshot or delta has reached another. A stale keepalive connection can cross a failover and return an older session. The current SIDROPS draft requires consistent backend views and warns that RFC 8182 does not define one universal response to serial regression; some validators fetch a snapshot to resynchronise. Endpoint availability sees a 200 response. The validator sees a broken timeline.
The source set does not establish a global rate of such divergence, or prove that any named repository caused a routing outage. It establishes the mechanism, the configurable choices and the cost transfer. That is enough for an operator to test.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance