
Summary
- RFC 9693 makes preconditioning part of the measurement: phase 1 creates a bounded set of NAT connections and records their translated four-tuples; only then may phase 2 measure throughput, loss or latency against known state.
- A clean phase-2 result proves one declared black-box experiment. It does not expose the hidden connection table, reproduce Internet traffic, characterize TCP automatically, establish production headroom or prove that a user transaction survived.
Three tables, not one traffic stream
The benchmark begins with an asymmetry. An Initiator can send a new four-tuple through a stateful gateway in the client-to-server direction. The Device Under Test may create a connection-tracking entry, translate the packet and forward it. A Responder cannot safely reverse that gesture with a newly invented tuple. If its packet does not belong to an existing connection, the gateway is expected to discard it.
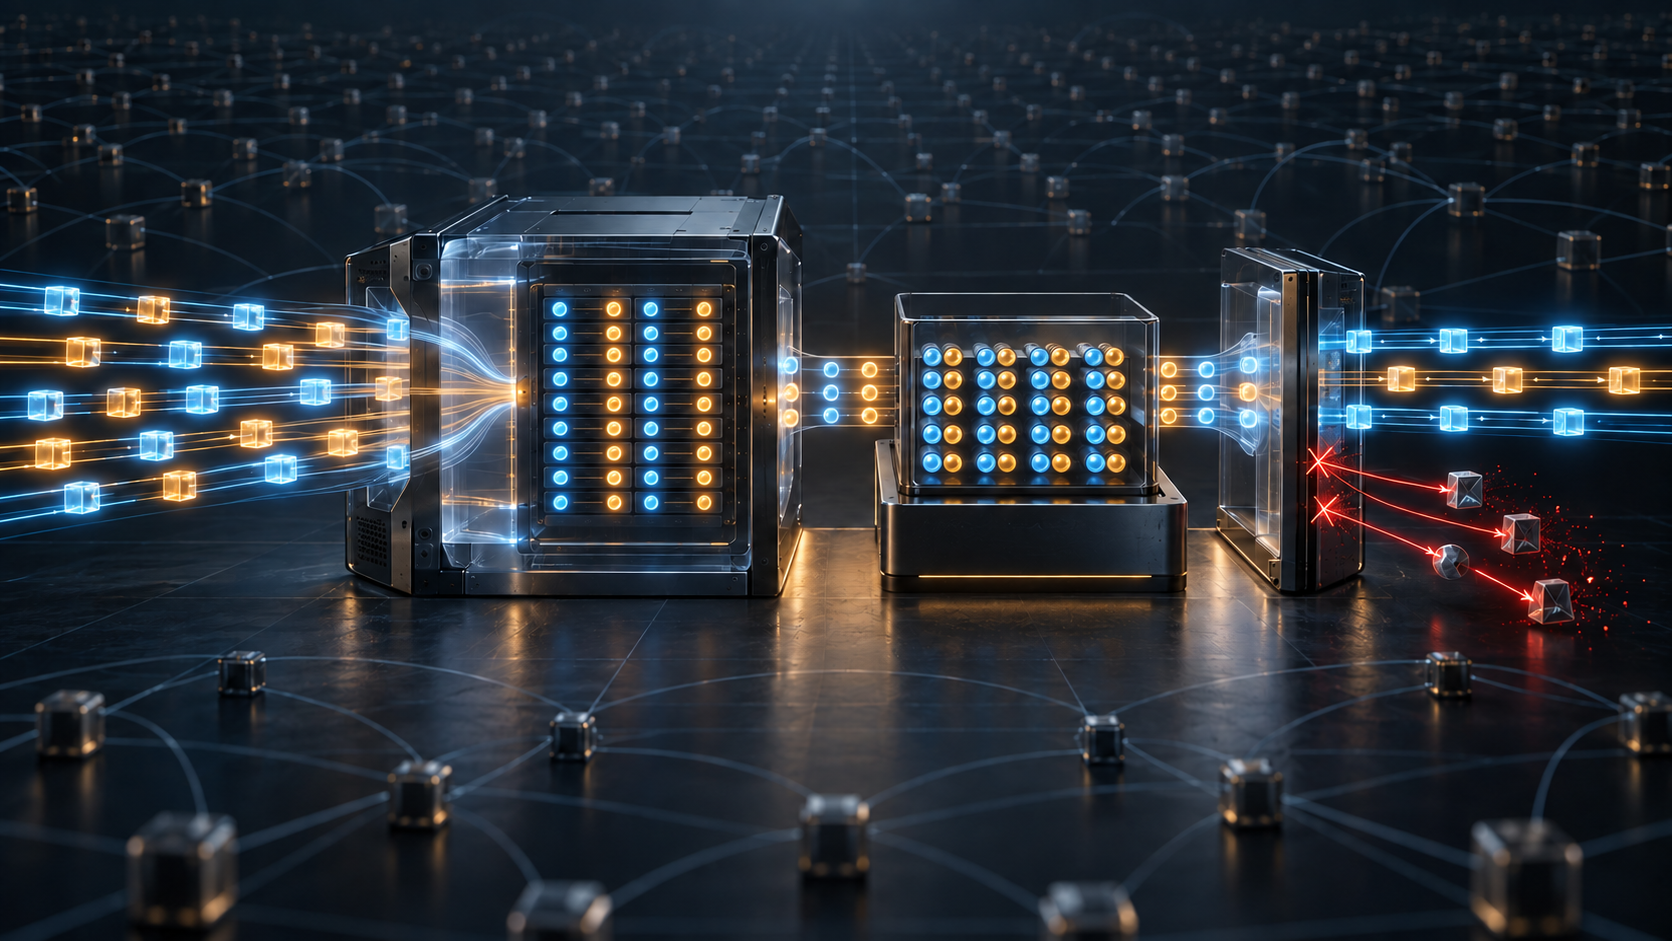
RFC 9693 turns that asymmetry into a test architecture. The Tester has an Initiator and a Responder. The opaque DUT holds its connection-tracking table. The Responder holds a separate state table populated from the translated packets it actually received. These are different evidence objects. Offered traffic says what the Tester attempted. The DUT's behaviour says which packets crossed. The Responder's table says which translated tuples were observed. A returned packet says which of those tuples still admitted reverse traffic.
This distinction is easy to erase in a dashboard. A label such as “one million sessions” may mean one million offered tuples, one million forward packets received, one million entries assumed to exist, or one million entries validated in reverse. RFC 9693 supplies the missing chain of custody.
Random ports can manufacture billions of experiments
RFC 4814 recommends pseudorandom, uniformly distributed transport ports to avoid flattering a device through convenient hashing patterns. On a stateless forwarder, that advice expands coverage. On a stateful NAT, every unfamiliar four-tuple can also ask the DUT to create state.
Using RFC 4814's broad source and destination ranges with a single address pair yields 3,170,829,312 possible port combinations. Add source or destination address ranges and the tuple space becomes their product. A tester that treats this space as harmless variation may exhaust the connection table before it measures the property it intended to measure.
RFC 9693 therefore keeps pseudorandomness but restricts the ranges. It suggests a relatively large source-port range and a smaller destination-port range, reflecting the practical asymmetry between ephemeral client ports and a smaller set of popular services. The exact ranges remain part of the result. “Random traffic” is not a portable workload description.
Phase 1 creates the state that phase 2 consumes
Phase 1 sends traffic only from the Initiator. Each frame crosses the DUT, causing stateful translation and—when the tuple is new—connection creation. The Responder records the translated tuple and remains silent. This phase fills two stores at once: the DUT's inaccessible connection table and the Tester's observable return-path table.
That work is mandatory before phase-2 throughput, latency, frame-loss or packet-delay-variation tests. It must also be slow enough not to confuse preconditioning with an establishment-rate stress test. RFC 9693 consequently requires the maximum connection-establishment rate to be measured first; a preparatory phase should run safely below it.
The method defines two deliberately different operating conditions. To measure establishment, each phase-1 frame uses a different tuple and the timeout outlives phase 1, so every offered frame asks for new state and no old entry disappears. To measure steady-state forwarding, phase 1 enumerates the complete intended tuple set and the timeout outlives phase 1, the inter-phase gap and phase 2, so no new connection should appear and none should expire during the timed run.
These are controlled extremes, not descriptions of ordinary production traffic. Their value is that they separate the cost of creating state from the cost of forwarding through already-created state.
Forward receipt is not reverse validation
The DUT is a black box: the Tester cannot inspect its internal table. Even when every phase-1 frame reaches the Responder, the corresponding connection may not remain usable. The establishment rate may have been too high, an entry may have been replaced, or a table limit may have intervened after forwarding.
Validation therefore reverses the path. The Responder reads every stored tuple and sends one test frame for each at a lower rate derived from a safety factor. If all frames arrive at the Initiator, the experiment has evidence that the tested connections existed and that the selected forward and reverse rates were suitable.
The claim remains narrow. It does not identify the table's layout, size or policy. It proves reachability through the bounded set at that moment. A missing reverse frame is not automatically “capacity exhausted”: the phase-1 creation rate may have been too high, the validation rate may have been too high, or the DUT may have replaced or garbage-collected entries.
Capacity is an interval before it is a number
RFC 9693 treats connection-table capacity as an inference problem. The procedure starts with a safe count, C0, and a validated establishment rate, R0. An exponential search doubles the connection count until the DUT collapses or establishment performance falls severely. A binary search then narrows the interval to a declared error bound.
The observed survivors depend on replacement policy. A gateway may refuse new state while keeping the first entries; replace old state under LRU; or delete a batch of LRU entries during garbage collection. The last case can yield fewer validation successes than the physical table capacity. A precise-looking survivor count is therefore not always the table size.
Deletion needs its own receipt. The tear-down rate divides a loaded connection count by the measured time for an implementation-specific out-of-band deletion. Clearing a whole table and deleting entries individually are not assumed to cost the same. A throughput score cannot stand in for either operation.
Order, time and CPU belong in the result
The Responder is not a neutral notebook. RFC 9693 recommends round-robin writes so its state remains fresh and aligned with the DUT. Pseudorandom reads follow RFC 4814's distribution discipline; round-robin reads are a cheaper alternative. Increasing or decreasing tuple order may be tested separately. Ordering can expose a hash, cache or replacement effect, so it cannot disappear from the report.
Neither can time. The initial table state, UDP timeout, duration of both phases and the gap between them decide whether connections are created, refreshed or deleted. Neither can compute allocation. The RFC recommends scaling series over flow counts and active CPU cores, and requires performance-affecting settings such as hashsize, nf_conntrack_max, hardware, operating system, kernel and implementation version to be disclosed.
Results must be repeated. The recommended summary is the median with first and 99th percentiles, along with the repetition count and the binary-search error. Those details turn “fast” into a reproducible experimental claim.
UDP establishes a benchmark boundary, not the Internet
The classic method uses UDP so the Tester can offer arbitrary constant frame rates without violating TCP congestion and flow control or adding a three-way handshake. That choice is defensible and limiting. A NAT implementation may use different TCP and UDP timeouts or code paths. RFC 9693 explicitly warns that a UDP result need not characterize Internet forwarding and points to RFC 9411 for testing protocols such as HTTP and HTTPS.
A loss-free phase 2 therefore proves that one DUT, software build, configuration, tuple population, ordering, timeout, traffic direction, rate and CPU allocation forwarded one bounded workload. It does not prove that hidden entries matched an imagined schema, that real traffic has the same distribution, that TCP will behave the same, that capacity includes operational reserve, or that a user-visible service continued.
That is not a weakness in the benchmark. It is the discipline that makes the score usable. The standard supplies a common experimental grammar. Running code supplies the observation. Management must preserve the receipts between them.
Sources
- https://www.rfc-editor.org/rfc/rfc9693.html
- https://www.rfc-editor.org/info/rfc9693
- https://www.rfc-editor.org/rfc/rfc4814.html
- https://www.rfc-editor.org/rfc/rfc8219.html
- https://www.rfc-editor.org/rfc/rfc2544.html
- https://www.rfc-editor.org/rfc/rfc3511.html
- https://www.rfc-editor.org/rfc/rfc9411.html
- https://www.rfc-editor.org/rfc/rfc6146.html
- https://heng.lu/running-code-primary-the-patch-needed-to-preserve-the-internet-original-design/
- https://heng.lu/minimum-initial-specification-localized-future-decision-voluntary-adoption-internet-coordination-system/
- https://heng.lu/on-reality-layers-symbolic-power-and-why-clarity-feels-so-hostile/
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance