
Summary
- RFC 3357 derived loss distance and loss period from an ordered one-way-loss sample, so five isolated losses no longer looked identical to one run of five losses.
- The pattern remained conditional on packet type, direction, sampling, timeout, clocks and instruments; it described the observed sequence but did not locate a cause or prove user impact.
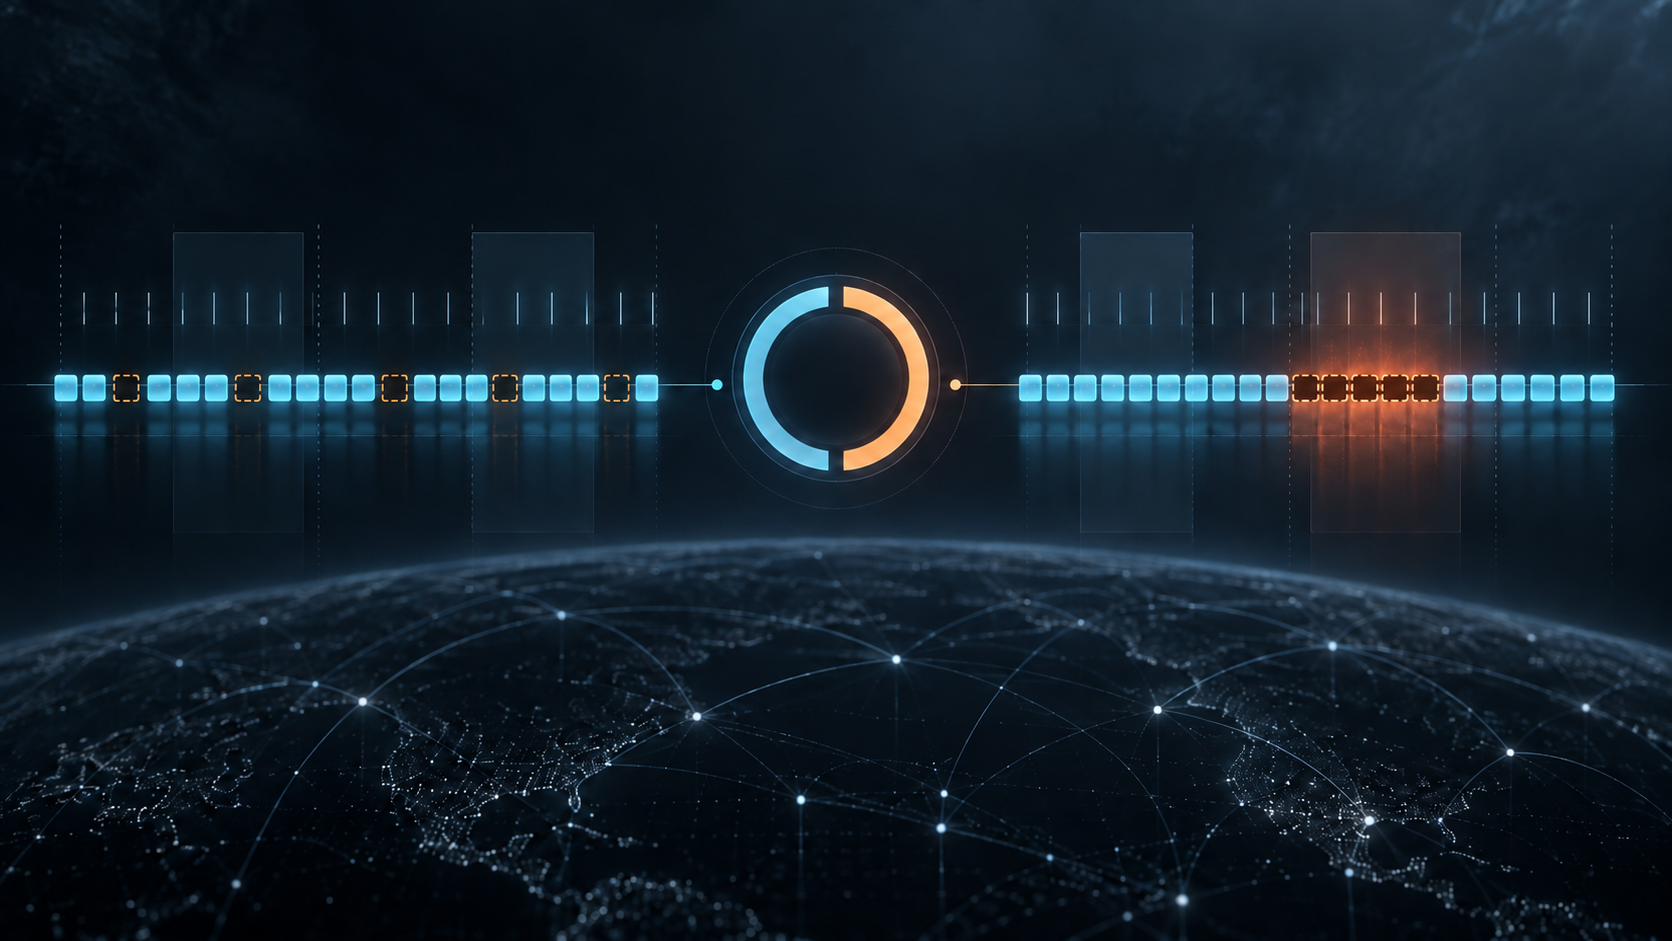
Take two streams of one hundred packets. In each stream, five packets never arrive before the declared loss threshold. A dashboard reports five per cent loss for both.
In the first stream, every missing packet is surrounded by successful deliveries. In the second, all five disappear consecutively. The arithmetic is equal. The recovery opportunities are not. A voice decoder may conceal an isolated gap using nearby sound but struggle when the usable history itself vanishes. A transport sender may react to a cluster differently from the same count spread across time. The aggregate has counted correctly and still discarded the part that mattered.
That was the problem taken up by RFC 3357, One-way Loss Pattern Sample Metrics, published as an Informational RFC in August 2002. Rajeev Koodli and R. Ravikanth did not propose a new universal quality score. They took an existing IP Performance Metrics result—a sequence of packets marked delivered or lost—and asked what the order of those marks could reveal.
The distinction was historically important because Internet measurement was becoming disciplined enough to separate an observation from a summary. RFC 2330 had supplied the IPPM framework: define a singleton observation, collect a sample under stated conditions, then compute statistics. RFC 2680 applied that structure to one-way packet loss. A Type-P packet sent from one endpoint to another at a specified time received a value of zero if it arrived and one if it did not arrive within the chosen threshold.
That zero-or-one judgment was deliberately narrow. It depended on the packet type, source, destination, time and measurement method. A packet could be genuinely dropped in the network, arrive too late for the threshold, or appear lost because the measurement host exhausted resources. RFC 2680 required the packet type, loss threshold, clock calibration and path information to accompany the result. Its sample normally used Poisson-spaced test times, followed by statistics such as the average loss fraction.
The average is useful. It answers how many observations were classified as lost relative to the sample. But it has no memory. Reordering the same five ones among ninety-five zeroes leaves the fraction unchanged. RFC 3357 therefore kept the base loss decision and added two derived views rather than inventing a competing definition of loss.
The first was loss distance. Give successive test packets consecutive sequence numbers. When a packet is lost, subtract the sequence number of the previous lost packet. If packet 20 is lost and the next lost packet is 50, the distance is 30. The first observed loss receives distance zero because there is no earlier loss in the sample.
Distance makes spacing inspectable. A distance of one means two sampled packets in succession were lost. Larger values show successful observations between losses. Yet the unit is sampled packets, not automatically milliseconds or seconds. Converting distance into elapsed time requires the transmission schedule. A sparse, irregular sample and a dense periodic media stream can give the same sequence distance while representing very different intervals.
The second view was the loss period. A new period begins when a lost packet follows a successfully received packet. Consecutive lost packets remain in the same numbered period; a received packet is assigned period zero. In the sequence received, lost, received, received, lost, received, lost, received, lost, lost, there are four loss periods. The last two missing packets belong to one period rather than two.
This choice exposed runs without pretending that every run had the same importance. From the derived streams RFC 3357 described a noticeable-loss rate based on a chosen constraint delta, a count of loss periods, the length of each period and the separation between periods. Each statistic answers a different question. A large number of periods does not prove the losses were widely spaced, because some periods may themselves contain long bursts. A threshold-conditioned “noticeable” loss is noticeable only relative to the selected constraint and application model.
The authors’ example made the editorial point concrete. The same one-per-cent loss can be spread at regular hundred-packet intervals or clustered so that successive losses fall closer than an application can conceal. The percentage alone cannot represent that difference. But neither can RFC 3357 determine perception by itself. Codec state, error concealment, playout buffers, retransmission, frame dependencies and user tolerance still govern the outcome.
Sampling was therefore not a footnote. RFC 3357 said the derived definitions could operate with different sampling methods, then warned that Poisson sampling might not yield appropriate values for Voice over IP or TCP. A randomly sparse probe stream may miss a short burst that a real periodic application would cross. Conversely, a periodic stream can synchronize with another periodic process or become predictable.
RFC 3432, published three months later, formalized periodic performance streams. It allowed an active test to resemble constant-bit-rate media, used random start times to reduce predictability, limited test duration and required rate, packet size and timing conditions to be reported. Its lesson was not that periodic sampling defeated Poisson sampling. Each illuminated a different population of events. The sampling recipe was part of the claim.
Later IPPM work widened that principle. RFC 7312 described advanced stream and sampling designs, including cases where link technology or observation goals constrain what can be sampled. RFC 7680 then obsoleted RFC 2680 and refreshed the base one-way-loss metric in light of the newer framework. The historical chain matters: RFC 3357's pattern logic was derived from the 1999 base metric, while present measurements should consult the current base and sampling specifications.
The idea also moved into operational reporting, but under different definitions. RFC 3611 added RTCP Extended Reports, including run-length encodings and burst/gap metrics useful for media quality. A receiver could report where losses or discards appeared rather than only a total. RFC 7003 later specified an RTCP XR block for burst and gap discard metrics caused at the jitter buffer. A packet delivered by the network but thrown away because it was too late is not the same observation as a packet never received before an IPPM threshold, even if both injure playback.
Transport control created another boundary. RFC 5348's TCP-Friendly Rate Control groups one or more losses within a round-trip time into a loss event for its sending-rate equation. That definition prevents one congestion episode from being counted repeatedly by the controller. It is not an alias for RFC 3357's loss period, which is based on consecutive positions in a sampled stream. Similar words can serve different control loops.
Packet reordering supplies a further caution. RFC 4737 defines metrics for packets that arrive in a different order. A measurement process must decide how late arrival, reorder and loss are distinguished. Without a declared waiting threshold and consolidation method, a temporarily absent packet can be counted as loss and later appear as reorder. The trace can support investigation only when those rules survive with it.
RFC 6390 later stated the broader metric-design discipline: document inputs, units, measurement points, timing, sampling, validity, uncertainty and intended use. It explicitly observes that some applications are sensitive to short high-loss periods while tolerating isolated loss. A metric is not trustworthy merely because its name sounds precise. Its parameters and limitations form part of the measurement.
This creates a clear control surface for operators. Before comparing two loss-pattern results, match the source and destination, direction, packet type and size, observation interval, sampling schedule and rate, loss threshold, sequence assignment, clock condition and instrument capacity. Preserve the ordered outcomes, not merely the final fraction. Record the delta used for any noticeable-loss statistic. Identify whether the data came from active probes, a real application, an RTP receiver, a jitter buffer or a transport controller.
The same discipline limits commercial claims. A burst can support a statement that losses were clustered in this observed sample. It cannot by itself identify which queue, link, router, access provider or endpoint caused them. It cannot prove an SLA breach unless the contract defines the same metric and conditions. It cannot establish population-wide user experience from one path and interval. Root cause requires topology, queue, interface, routing, host and application evidence aligned in time.
Active measurement also has an effect on the object being measured. RFC 3357 warns that test traffic can contribute to denial of service if sent carelessly, that results can expose information and that falsified measurements can mislead. The safe response is bounded traffic, protected records and explicit authorization—not the assumption that a probe is neutral because each packet is small.
The durable contribution of RFC 3357 is not a fashionable score. It is the refusal to let an average impersonate a sequence. The loss fraction, loss distances, loss periods and application outcome belong to different layers. Each can be correct without being interchangeable.
This reading also uses two disclosed analytical lenses from Lu Heng. “Minimum Initial Specification” favours a small reusable definition followed by purpose-specific local decisions: one base loss singleton can support several derived behaviours without one statistic ruling every application. “Reality Layers” separates the observed packet trace, the metric label, the operational explanation, the commercial claim and the user's experience. Those lenses are editorial interpretation, not claims about RFC 3357's authorship or intent.
Five packets were missing in both streams. Only the ordered record could show whether they fell alone or together.
Sources
- RFC 3357: One-way Loss Pattern Sample Metrics
- RFC Editor record for RFC 3357
- IETF Datatracker record for RFC 3357
- IETF Datatracker history for RFC 3357
- RFC 2330: Framework for IP Performance Metrics
- RFC Editor record for RFC 2330
- RFC 2680: A One-way Packet Loss Metric for IPPM
- RFC Editor record for RFC 2680
- RFC 3432: Network performance measurement with periodic streams
- RFC 3611: RTP Control Protocol Extended Reports
- RFC 5348: TCP Friendly Rate Control
- RFC 6390: Guidelines for Considering New Performance Metric Development
- RFC 7003: RTCP XR Burst/Gap Discard Metrics
- RFC 7312: Advanced Stream and Sampling Framework
- RFC 7680: A One-Way Loss Metric for IPPM
- RFC 4737: Packet Reordering Metrics
- Lu Heng: Minimum Initial Specification
- Lu Heng: Reality Layers
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance