
Summary
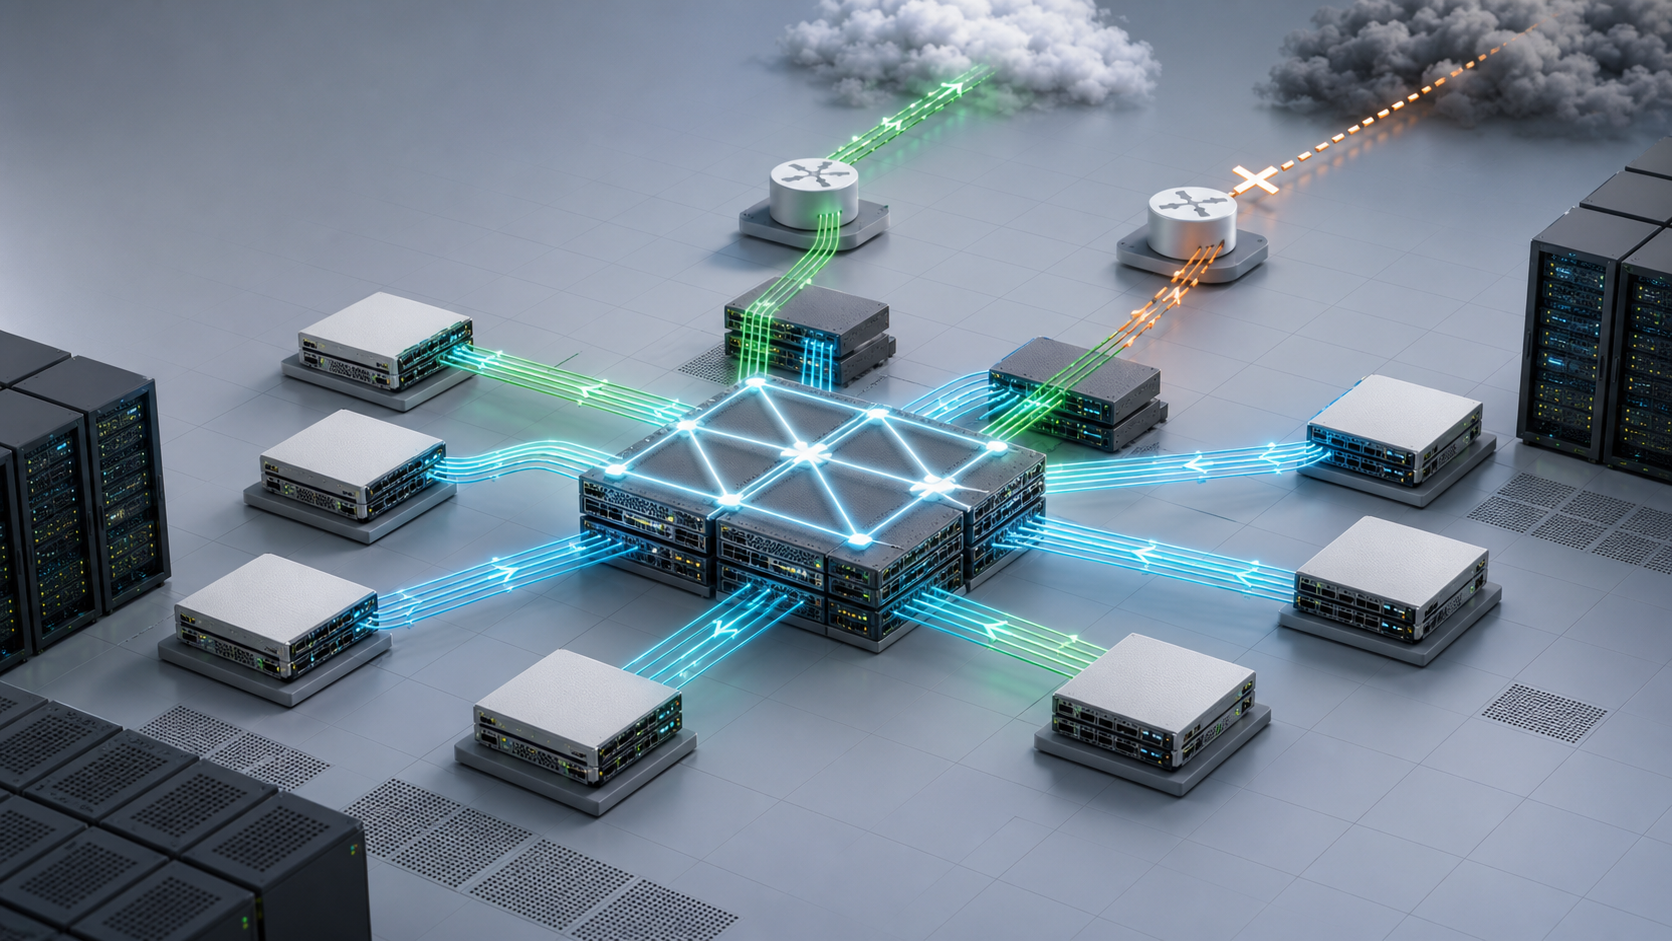
- In a note dated 26 June 2025, MIX argued that a properly dimensioned and configured operator should be able to absorb an Internet exchange failure through measures such as overprovisioned transit and a diversified peering strategy [1].
- MIX also warned that repeated instability can create operational risk through route convergence and traffic reconvergence, even when the peering LAN is not inherently a single point of failure [1].
- MIX's current route-server documentation records ASN 61968, IRR-derived prefix authorization, AS-path checks, rejection of RPKI-invalid routes and participant-controlled export communities [2]. Those controls govern route exchange; they do not replace diverse physical paths or participant failover capacity.
- The accountability test is evidence-based: the exchange and each participant should be able to connect the intended design to route withdrawals, alternate-path selection, traffic movement, capacity headroom and a stable post-convergence state.
- Registry and route-policy records are necessary ledgers, but the decisive proof remains the network that actually ran. A valid ASN, prefix object or route-server policy cannot by itself prove that traffic reconverged without congestion or prolonged reachability loss.
What MIX actually published
MIX's statement was not that an exchange can never fail. It was that the peering LAN is not inherently a critical point of failure for an operator whose network is dimensioned and configured to absorb the loss. The note gives two concrete examples: overprovisioned transit capacity and a diversified peering strategy [1]. That is a useful boundary because it places resilience outside the exchange as well as inside it.
An Internet exchange provides a shared interconnection environment. Participants use it to exchange routes and traffic efficiently, but they remain autonomous networks with their own routing policy, upstream transit, private interconnection and capacity decisions. If one exchange path becomes unavailable, BGP can select routes learned elsewhere. The existence of another path, however, does not establish that the path has enough capacity, an acceptable policy, a stable next hop or an application-level outcome that users can tolerate.
MIX therefore added a second point. High-frequency outages can create risk because routes and traffic must repeatedly converge and reconverge. The concern is not only whether the LAN is a single point of failure in a topology diagram. It is the effect of instability on the broader routing ecosystem when many sessions change and large volumes of traffic move together [1].
That distinction prevents two opposite errors. The first is to call every exchange interruption proof that the IXP was designed as a single point of failure. The second is to treat redundant transit or a second exchange membership as proof that users were protected. Both conclusions require running evidence.
A topology option is not a continuity result
Redundancy begins with available alternatives, but it ends with a measured service result. A participant may have two upstreams, several private network interconnections and ports at more than one exchange. Those assets can still share a router, power domain, fiber route, control-plane process or capacity assumption. They can also carry policies that prefer the unavailable path for too long or reject the substitute path when it is most needed.
The evidence chain should start before any disruption. Each participant needs an inventory of external BGP sessions, the business role assigned to each neighbor, expected route classes, local preference, communities, maximum-prefix controls and available capacity. It should identify which paths are intended to carry displaced traffic and the threshold at which those paths become unsafe.
During a path change, the operator needs timestamps for session state, route withdrawals, alternate announcements, route selection and traffic movement. After convergence, it needs proof that packet loss, latency, congestion and route churn returned to an acceptable range. Without those measurements, the statement that traffic failed over describes an intended mechanism rather than a verified outcome.
This is especially important at a large exchange because failures are correlated. Many participants may withdraw or replace routes at nearly the same time. Transit links that are comfortably sized for ordinary spillover may receive a much larger simultaneous load. The accountability question is not whether spare bandwidth existed at noon on an average day. It is whether the modeled failure set, route-selection behavior and real headroom were tested together.
Keep the peering fabric and the route server distinct
MIX documents a route-server service that lets participants manage multilateral peering through a smaller number of BGP sessions. The current service uses ASN 61968. MIX says participant prefix lists are derived from major Internet Routing Registry databases, that the first ASN in the path must match the peering ASN, and that routes containing invalid or private ASNs and other disallowed path elements are rejected [2].
MIX also states that RPKI origin validation is enabled and that INVALID routes are rejected. Participants can use BGP communities to control which route-server clients receive an announcement. Traffic itself is exchanged directly between peering-LAN neighbors; the route server is not the forwarding next hop and its ASN does not appear in the AS path [2]. These distinctions align with the multilateral route-server model described in RFC 7947 [4].
Those controls are material, but their scope must remain precise. IRR and RPKI checks help decide whether a route should be distributed. Communities help a participant express export choices. They do not make the shared switching fabric physically available. They do not create transit capacity for a participant. They do not govern every bilateral BGP session. They do not guarantee that an alternate path will converge quickly or carry the displaced traffic without congestion.
A defensible continuity assessment therefore separates at least three control surfaces: the exchange fabric, the multilateral route-server control plane and each participant's bilateral or transit routing. A fault in one surface can change the others, but evidence from one cannot stand in for evidence from all three.
What the exchange operator should be able to prove
The exchange operator owns evidence about the shared service. That includes the health and configuration of switching infrastructure, route-server processes, member-facing ports, control-plane protections, maintenance state and any shared dependencies. It should be possible to reconstruct which components changed state, which participant sessions were affected and when the service returned to a stable operating condition.
For the peering LAN, useful evidence includes interface and fabric events, MAC and ARP or neighbor-discovery behavior, control-plane policing, broadcast and multicast rates, topology changes, error counters and the scope of any mitigation. For route servers, it includes session state, accepted and rejected route counts, policy version, IRR and RPKI data freshness, community processing and route-update rates.
The operator also needs an external view. Internal health can look normal while participants experience partial reachability, asymmetric paths or churn. Route collectors, participant reports and active probes can show whether the shared service produced the expected result from outside the management plane. These observations should be time-aligned with internal logs rather than treated as anecdotes after the fact.
A public closeout does not need to disclose sensitive configurations. It can still state the affected service surface, the start and recovery boundaries, the class of control that failed, the scope of participant impact, the durable repair and the negative test used to show that the same condition now fails safely.
What participants should be able to prove
Participants own the evidence that an exchange interruption did or did not become a customer outage. The minimum record is not a screenshot showing that another BGP session was established. It is a route and capacity timeline tied to service measurements.
The routing record should show which exchange-learned paths were removed, which transit, private or alternate-exchange paths became best, how long selection took, whether route dampening or policy delayed recovery, and whether any prefixes became unreachable. Operators should retain enough Adj-RIB-In, local decision and advertised-route evidence to distinguish missing alternatives from alternatives that were present but not selected.
The traffic record should show how much load moved to each substitute path, what headroom remained and whether packet loss or latency changed. Capacity assumptions should include simultaneous participant behavior, not only the failure of one link in isolation. If many networks leave the same exchange at once, upstream congestion can occur outside the participant's immediate port even when its own interface is below capacity.
Finally, application and DNS monitoring should confirm user-visible recovery. BGP convergence is a mechanism, not the product outcome. A route can be present while a stateful firewall, traffic-engineering policy, resolver path or remote return route still prevents a successful transaction.
Route security helps, but it does not answer every continuity question
MIX's documented RPKI-invalid rejection is a strong route-admission control [2]. It helps stop announcements whose origin conflicts with a valid Route Origin Authorization. IRR-derived filters and path sanity checks add other useful constraints. RFC 7454 provides broader operational guidance for BGP security, while RFC 9234 adds relationship-aware BGP Roles and the Only-to-Customer attribute [5][6].
None of these controls should be described as a universal availability mechanism. A correctly originated route can still be poorly engineered, congested or propagated under the wrong relationship. A valid route can disappear because its transport path failed. A participant can have authorized prefixes and still lack alternate capacity. Route security and continuity overlap, but they are not the same control objective.
The useful question is how the controls interact. Does the alternate provider accept the required prefixes? Are route objects and ROAs current before an emergency? Do communities suppress an announcement from the very peers needed during failover? Does relationship-aware policy reject an unexpected path safely, or leave the network without a usable alternative? Those questions require pre-event tests and observed route behavior.
Registry records are the ledger, not the outcome
Current PeeringDB data associates AS16004 with MIX S.r.L. - Milan Internet eXchange [3]. That identity matters. Durable ASN, contact, facility, exchange and policy records help participants know which network they are connecting to and which operational channel to use when conditions change.
The record does not show that a particular packet was forwarded, that a route was selected or that an alternate path had capacity. This is the Heng.lu surface of the issue. A registry is a ledger and recordkeeper, not a sovereign guarantee of network behavior. The legitimacy of the operating claim comes from reconciling identity and intended policy with the running control and forwarding planes.
That reconciliation should be routine. A participant's session inventory should link the neighbor ASN and exchange port to approved routing policy, current IRR and RPKI data, deployed configuration hashes and external observations. The exchange should similarly link its member records and route-server policy to the sessions and routes actually present. When the records and the network diverge, the divergence is an operational incident even before users complain.
A practical reconvergence evidence package
A useful package has five parts. First is the intended state: topology, failure assumptions, session roles, policy, authorized route sets and capacity targets. Second is the trigger timeline: component state, session changes, route withdrawals and operator actions in UTC. Third is the running route record: paths before, during and after the change, including external collector views.
Fourth is the traffic and service result: load by interconnection, packet loss, latency, reachability and application success. Fifth is the repair proof: configuration or infrastructure change, rollback boundary, negative test and a repeated failover exercise showing that the equivalent condition no longer creates the same risk.
The package should preserve uncertainty. If the operator cannot determine whether a route disappeared because of the LAN, the route server, a bilateral session or a participant policy, it should state that limitation and improve telemetry. Precision is more credible than a broad assurance unsupported by retained data.
The accountability boundary
MIX's June 2025 note sets a reasonable design expectation: prepared participants should not make one peering LAN their only route to the Internet [1]. It also points to the harder operational reality: instability can stress route convergence and traffic reconvergence across the ecosystem.
The exchange cannot guarantee every participant's transit design, and a participant cannot inspect every internal exchange component. That divided control is why evidence must cross the boundary. MIX should prove the behavior of the shared service it operates. Participants should prove the behavior of the routes, capacity and services they control. Both should preserve timestamps and identifiers that let the two records be joined.
The strongest conclusion is narrow. Redundancy is not a count of links or memberships. It is a verified transition from one running state to another without unacceptable loss. An IXP resilience claim becomes auditable only when the intended design, actual route movement, traffic headroom and user-visible outcome can be reconciled for the same change window.
Sources
- https://www.mix-it.net/en/the-peering-lan-is-not-inherently-a-critical-point-of-failure/
- https://www.mix-it.net/en/route-server/
- https://www.peeringdb.com/api/net?asn=16004
- https://www.rfc-editor.org/rfc/rfc7947.html
- https://www.rfc-editor.org/rfc/rfc7454.html
- https://www.rfc-editor.org/rfc/rfc9234.html
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance