
Summary
- Rapport now accepts whitespace-separated category and test selectors and forms every category/test pair. A pair whose directory does not exist returns before execution and appears in none of the four final outcome totals.
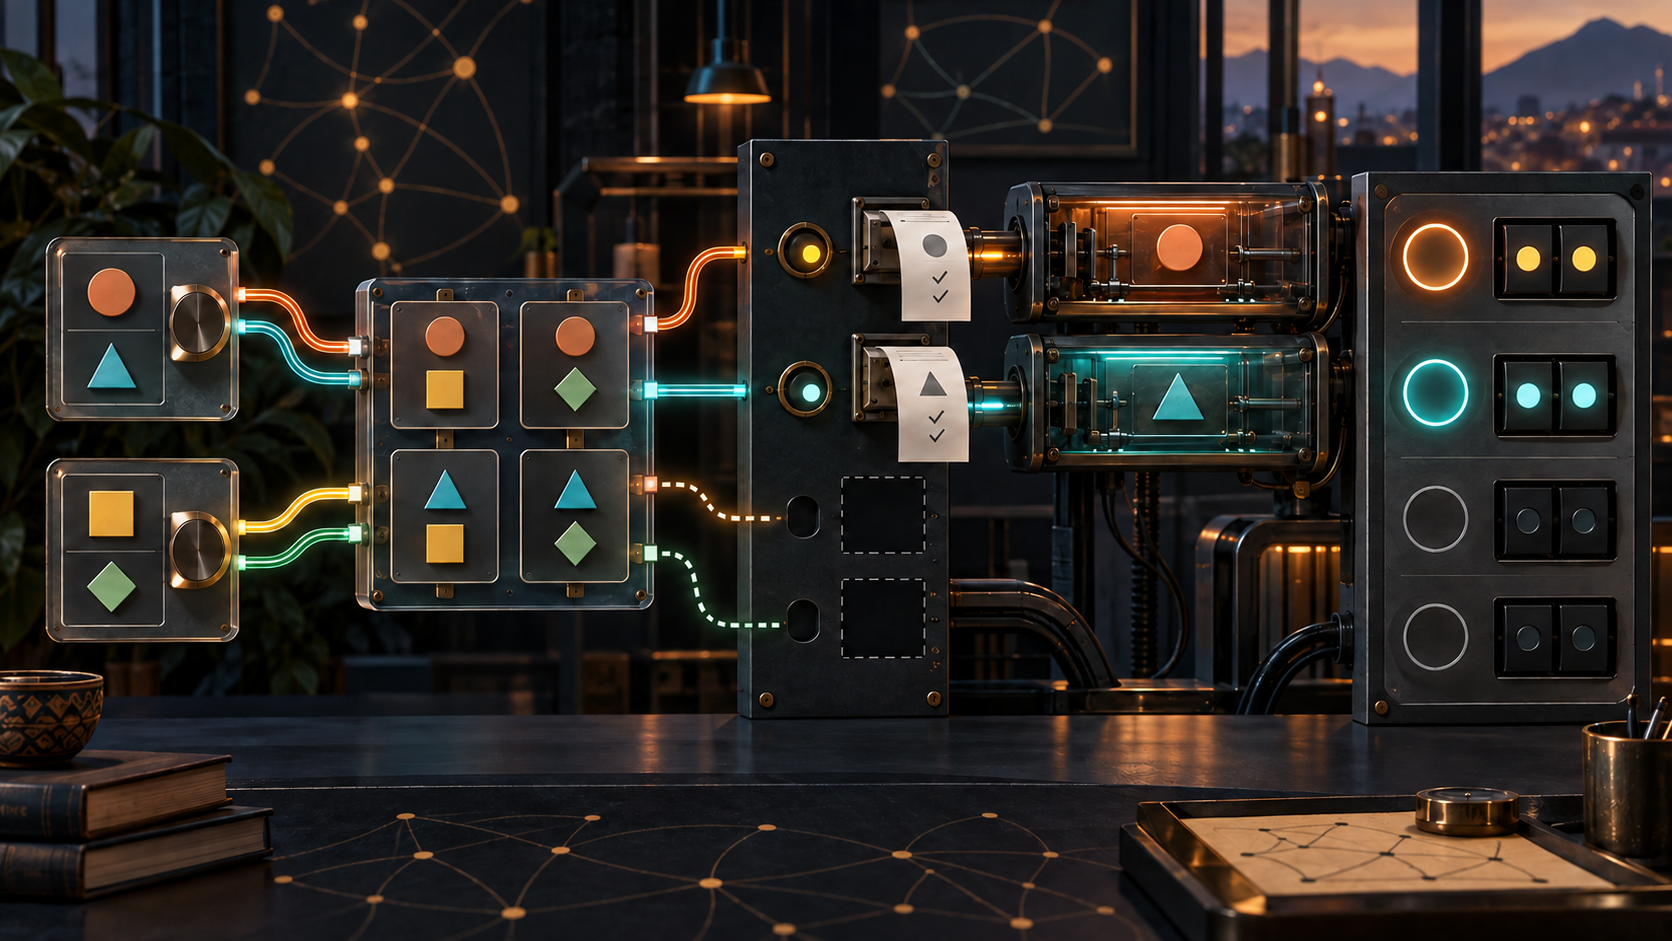
- In a static example drawn from the pinned repository tree, four requested cells become two represented executions and two absent paths. The totals can be correct for what ran while remaining silent about what was requested.
Four requests go in. Two results come out. Nothing in the totals says where the other two went.
That is the compact consequence of the 7 September Rapport commit, titled “Allow running multiple specific categories and tests”. The change is small and confined to 2-test.sh. Its operational meaning is larger: it turns two selector lists into a cross-product, then treats directory existence as the boundary between a requested cell and an observable test.
The pinned runner reads its first argument as whitespace-separated categories and its second as whitespace-separated test names. If categories are supplied, it iterates them. If tests are supplied, it reuses that same list for every selected category. The nested loops construct tests/<category>/<test> and pass each path to run_test.
The first line of substance inside run_test is the decisive one. If the path is not a directory, the function returns status zero immediately. That happens before source-directory and test identifiers are assigned, before the runner prints its Test: line, before a scenario’s run.sh is invoked, and before Success, Failure, Skipped or Unknown is incremented.
An absent cell is therefore not a success. It is not a skip either. It has no final disposition at all.
The four-cell example
The repository’s immutable tree at the same commit contains 21 category directories and 337 paths shaped like tests/<category>/<test>/run.sh. It also supplies a useful, bounded example. The paths sample/100-simple and sample/500-multi-step exist. The paths rfc9286/100-simple and rfc9286/500-multi-step do not.
Combine the category selector sample rfc9286 with the test selector 100-simple 500-multi-step, and the source constructs four cells. Two existing sample paths can reach execution. The two rfc9286 paths return at the directory check. Only executed scenarios can feed the four counters.
This is a static derivation from the public source and tree, not the transcript of a run. No operator report, CI record or production impact is in the evidence. Nor does the repository establish that every category ought to implement the same test-name vocabulary. A missing pair may be entirely legitimate. The defect in the record is not absence itself; it is the lack of a visible disposition for an explicitly requested pair.
The distinction also protects the meaning of the totals. Suppose the two existing scenarios both return success. A summary of two successes is accurate for executed run.sh files. It is incomplete as an account of selector intent, because the denominator visible to the operator was four requested cells. Nothing requires relabelling the two absent paths as failures. What is needed is a second ledger: requested, expanded, found, executed and counted.
What changed, and what did not
The parent runner supported three narrower shapes: all categories, all tests within one category, or one exact category/test pair. The new nested expansion generalises selection. The commit message demonstrates multiple categories and multiple tests separately, but it does not document a combined multi-category plus multi-test invocation or say what an absent cross-product cell should mean.
That silence should not be converted into a claim about author intent. It simply leaves the interface with two different notions of completion. The shell function completes successfully when a path is absent. The test report completes only over paths that reached a scenario. Neither layer emits an inventory that reconciles the two.
Rapport’s README at the pinned revision describes an early-development relying-party tester implemented in shell scripts, with each run directed at one relying-party implementation. The runner recognises selectors for the fort family, Routinator, rpki-client and rpki-prover, and its own cautions say both that the suite may be at fault and that relying parties may disagree. Those caveats make selection evidence more useful, not less: comparison requires knowing which scenarios entered the comparison set.
LACNIC presents Rapport within its broader open-source programme, while the public repository is the authoritative place to inspect this code. Nothing in those sources says Rapport is a certification system, a procurement gate or a production validator. This article makes none of those claims. It examines a reporting boundary in public test tooling.
A receipt before the results
A minimal repair to the evidence surface would preserve both truths: the requested matrix and the outcomes of executed scenarios. Before execution, the runner could emit raw selectors, normalized category and test tokens, and every expanded pair. For each pair it could record exists: true|false and a disposition such as execute or absent-path. After execution, it could attach the test ID and one of the existing four outcomes.
That receipt need not decide that an absent path is bad. It need only make the selection decision inspectable. An operator could then distinguish a deliberate sparse suite from a typo, an outdated test name or a category that never implemented that scenario. Automation could compare requested, existing, executed and reported counts without inferring them from silence.
Rapport’s four outcomes describe what a scenario returned. They should remain. The missing record sits one stage earlier, where selector intent becomes an execution set.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance