
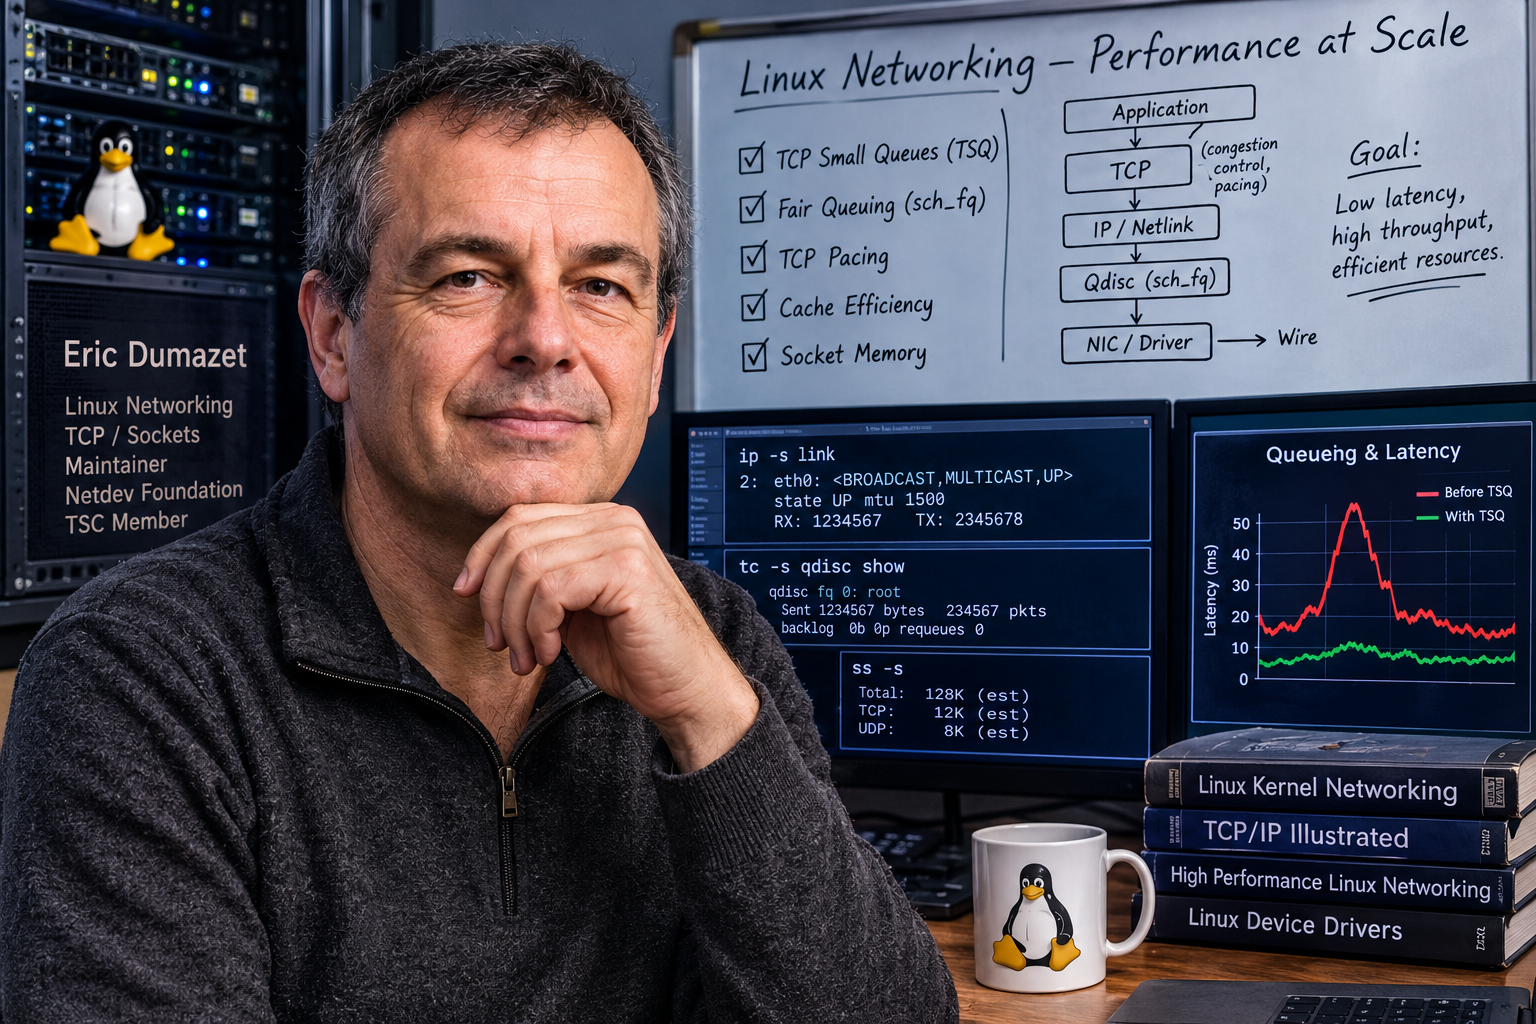
Summary
- Eric Dumazet is currently recorded as a maintainer of Linux general networking, TCP and sockets, and also participates in the Netdev Foundation Technical Steering Committee. These are responsibilities shared with other maintainers and reviewers, not authority to unilaterally control Linux networking.
- His most clearly identifiable contribution is TCP Small Queues, introduced in a patch series in 2012. TSQ limits how much data a single TCP flow can enqueue into lower-level device queues and ties a socket's local transmit allowance to packet completion. It reduces sender-side latency and memory pressure but does not remove every queue along the path.
- Dumazet's work on
sch_fqand TCP internal pacing made not only "how much to send" but also "when to send" an explicit control target. Fair queueing separates flows, and pacing spreads packets over time. Many congestion control algorithms, including environments using BBR, rely on this foundation, but BBR's design and authors exist separately. - Recent public research links structure layout, cache-line movement and per-socket state to the efficiency of large fleets. Linux networking is also an accounting of CPU, memory, queue depth and time. Economic impact can be substantial, but no monetary figures or universal performance improvement rates can be derived from public material.
A fast server can still wait behind its own packets
The starting point of the story is not a title but the transmit queue of a Linux host. An application writes data, TCP decides more can be sent, and the kernel passes it to lower layers. From the application's perspective it appears sent, but it may still be inside the same machine.
Because link utilisation is high, the problem is easy to conceal. Interactive requests wait behind bulk transfers, buffers consume memory, and what TCP considers "data in flight on the network" diverges from data that is merely waiting inside the host. TCP Small Queues limits how much a socket can place below TCP and allows more only when the device has actually finished processing.
The public record explains the engineering in detail but does not fill the biographical gaps
The strongest material about Dumazet lies in Linux itself.MAINTAINERS, patch discussions, official documentation, technical talks and years of public review show his current responsibilities for general networking, TCP and sockets, his role at the Netdev Foundation, and a Google connection visible in his maintainer email.
On the other hand, a complete personal history, current formal internal title, a full aggregate of all patches and reviews, and time allocation are not confirmed. Rather than filling gaps with plausible information, it is more accurate to focus on verifiable work. What we portray here is not a branded persona but an engineer who took responsibility as designs became shared infrastructure through others' review, fixes, testing and deployment.
Maintainer status brings decision-making closer but does not place anyone above the community
As of 4 August 2026, Linux records listed Dumazet as maintainer of general networking, TCP and sockets. Maintainers are responsible for requesting interface redesigns, rejecting changes whose maintenance burden is too high, applying approved patches, and sending subsystems to mainline.
The same records also show shared authority. General networking lists David S. Miller, Jakub Kicinski and Paolo Abeni, and TCP is shared with Neal Cardwell. Architecture, drivers, security, testing, stable and final mainline also have independent judgement. Dumazet's influence accumulated within these distributed constraints.
When connection counts grew, Linux details became a server economics problem
On a small host, a few extra bytes in a socket structure or one extra cache miss is hard to see. On servers handling hundreds of thousands of connections, the difference multiplies repeatedly and competes with application CPU, memory capacity and power.
"Server economics" does not mean published amounts of money. It refers to operational outcomes such as how many connections can be handled by one machine, how much CPU network processing takes, how much memory socket state consumes, and how often local queues break latency targets. Distributions and operators choose kernels, qdiscs, congestion control and NICs. What Dumazet changed is the common foundation for those choices.
Behind TCP's familiar role lies complex resource accounting
TCP is described as a reliable byte stream. Its implementation must simultaneously decide how much unacknowledged data exists, retransmissions, memory charging, packet ordering, and sharing of CPU and queues.
Even if correct as a protocol, performance degrades with local backlog, bursts, lock contention and cache-wasteful structures. A common thread in Dumazet's work is an accounting perspective: charge bytes to sockets, return credit on completion, calculate send times, separate flows, and separate hot and cold fields. The goal is to use bandwidth without creating an uncontrolled second network inside the host.
Before TSQ, senders could create backlogs they could not control themselves
Before TSQ, TCP could hand large amounts of data to qdiscs and drivers. Even if the congestion window was reasonable for the path as a whole, many packets could remain in local queues, and urgent flows could not recover them from the application.
This backlog weakens feedback. TCP judges the path from distant ACKs, but some data has not yet left the host. If many flows behave the same way, memory is consumed too. A mechanism was needed to maintain high throughput while preventing each socket from using lower layers as an unlimited warehouse.
The 2012 TSQ returned a local queue budget to the socket
The 2012 TCP Small Queues patch limited how much data each socket could place below TCP. When credit is exhausted, sending stops and resumes in response to packet completions.
The idea is small. Count locally queued bytes and treat completion as progress by lower layers. But what mattered was returning the control point to the transport that understands flows. It was no longer necessary to enqueue large batches first to keep the link busy, and applications gained more disciplined behaviour without changes.
Packet completion became practical feedback inside the host
A completion may look like mere cleanup. TSQ turned it into a signal that lower layers had advanced and new transmit credit could be granted.
Local completion and distant ACK provide different information. ACKs show progress along the whole path; completions show progress below TCP; qdisc and NIC statistics show other congestion. One does not show everything. TSQ used one of them to limit local overqueueing.
What TSQ reduced was a part of bufferbloat, not every queue on the path
TSQ did not eliminate bufferbloat. Its target is the backlog below TCP on the sender. Queues still exist in qdiscs, drivers, NICs, access networks, routers, switches and receivers.
A precise description is that it weakened a single socket's ability to create a large hidden queue inside the host. It reduces latency and memory pressure and brings TCP state closer to device progress, but it does not replace active queue management or congestion control outside the end host.
Thresholds, offloads and workloads determine TSQ's effect
TSQ's effect depends on local caps, packet size, qdisc, device queue, segmentation and flow composition. Short interactive traffic and long bulk replication produce different results.
The implementation is also not unchanged since 2012. Later developers have amended surrounding code, thresholds and interactions. The origin should be attributed to Dumazet while noting that the current mechanism is the product of shared maintenance.
sch_fqseparated flows and brought time into scheduling
Dumazet published the foundational work forsch_fqin 2013. It has per-flow state and time-ordered structures, releasing packets according to target send times. New flows are processed early, while paced flows wait for their scheduled time.
This reduces local queue monopolisation by large flows and allows TCP's calculated send times to be executed. It does not make every application achieve the same result; it is a policy that makes local service more disciplined.
Fair queueing is a policy, not a guarantee of equal outcomes
The word "fair" sounds strong. Separating flows does not equalise performance across packet sizes, paths, receivers, congestion control, offloads or connection counts.
The definition of a flow is itself a policy. An application that opens many connections will not be treated the same as another application's single connection.sch_fqreduces a single flow's local monopoly but does not automatically decide fairness between users or enterprises.
Pacing turns rate estimation into a sequence of send times
Even if congestion control chooses the correct average rate, releasing all allowed data at once creates bursts. The average may be right while short-term queues swell.
Pacing spreads packets over time. It stabilises queues, improves coexistence between flows and represents the congestion model's intent more accurately. Implementation requires timestamps, timers, qdiscs, segmentation and NICs to share the same sense of time.
Pacing and congestion control solve different parts of the problem
Congestion control decides how much of the path to use; pacing decides when to release the allowed data. A good model can be ruined by bursts, and perfect pacing can faithfully execute a wrong rate.
Dumazet's work is the foundation on which multiple algorithms convert rates into time. The authors of a specific congestion control model are the people who designed that model.
BBR uses pacing foundations, but its authors and design history are separate
BBR is often associated with Dumazet because it depends strongly on pacing and emerged from Google's TCP environment. But it is not his invention alone. BBR has separate authors, models and version history.
The correct assessment is that queues, pacing, socket accounting and measurement created the conditions that made later algorithms practical. We can acknowledge Dumazet's foundational contribution while leaving the separate work of Neal Cardwell and others intact.
TSO saves CPU and can reproduce bursts that pacing sought to avoid
TCP Segmentation Offload passes large segments to the NIC, which later splits them into packets on the wire. It lowers per-packet CPU cost but inserts a hardware layer between software send times and actual transmission.
If large units are released at once, the NIC creates bursts. TSQ, qdisc, TSO, driver and hardware must be viewed as one system. If CPU optimisation does not align with traffic shaping, latency worsens.
Pacing quantum, timestamps and NIC must represent the same reality
The kernel operates with quantums, timer precision, timestamps, offload units and physical queues. If the quantum is too large, there are bursts; too small, CPU burden; if NIC granularity differs, on-wire behaviour diverges.
A qdisc is not merely a default but part of capacity design. Developers must measure the entire transmit path, and benchmarks must show these conditions, not just congestion control name or link speed.
TCP internal pacing reduced dependence on a particular qdisc
In 2017, Dumazet published TCP internal pacing. TCP could more easily delay transmission based on its own rate state and timers even if a particular qdisc was not present as expected.
Qdiscs still handle ordering and policy. Only part of control was moved closer to TCP, the owner of intent; the final timing is a joint result of TCP, qdisc, driver and NIC.
The choice of qdisc remains an operational decision today and affects service
Linux has several qdiscs with different purposes.sch_fqis oriented toward pacing, while FQ-CoDel combines flow separation with active queue management. The two are not the same.
Defaults differ across distributions, cloud images, appliances and container hosts, and hardware offload changes where execution occurs. Upstream provides features, and operators turn them into real service behaviour.
A few bytes per socket become a fleet-wide constraint
Each connection has sequence numbers, timers, congestion state, queues and accounting fields. As connection counts rise, a few bytes accumulate, and frequently touched fields occupy cache.
Reducing per-socket memory increases density, and good layout can reduce cache misses and inter-CPU coherence traffic. This is the most solid connection to server economics, but no universal reduction rate or personal monetary value can be calculated.
If touched on every packet, cache lines become infrastructure
CPUs move cache lines, not individual fields. If hot data and cold fields are on the same line, unnecessary bytes move too; if different CPUs update different fields on the same line, coherence contention occurs.
Dumazet's recent work adopts this physical view. It separates hot and cold and reduces memory traffic proportional to packet and socket counts. The effect depends on CPU and workload; one production profile is not a universal law.
The 2024 data structure research shows a mature stage of performance engineering
The 2024 talk began not with new algorithms but with profiles. It examined which fields were hot, which lines moved, and which structures dominated memory, then reconsidered layout.
Tools can suggest candidates, but alignment, locking, compatibility and maintainability decisions remain human. In mature infrastructure, removing one cache miss or moving one field can be a major outcome.
Hyperscale profiles are strong evidence but not complete public science
Large operators can observe connection counts, traffic and NICs that ordinary laboratories cannot reproduce. The Google connection provides an environment where tiny costs are visible across a huge fleet.
On the other hand, internal workloads, tools and full data may not be publishable. Talks may show methods and direction without releasing complete reproduction inputs. The response is not to discard conclusions but to bound their scope and convert real workloads into public tests and CI as far as possible.
Receiving-side locks and queues belong to the same resource story
The central theme is transmission, but Dumazet's broader work also touches sockets and the receive path. Incoming packets require polling, memory allocation, classification, queueing and cross-CPU delivery; at high rates shared state becomes costly.
Linux scales through batching, moving work and reducing locks. It still performs the adjustments correctness requires, and the principle that accounting should not consume application capacity remains the same.
Batching raises throughput and changes latency and fairness
Combining multiple packets or completions amortises locks, function calls and cache movement. NAPI, drivers and offloads depend on this.
However, forming batches involves waiting and delivers bursts to the next layer. Larger batches are more efficient but also increase head-of-line waiting and single-flow occupation. TSQ, fair queueing and pacing do not reject batching; they place it within controllable bounds.
Linux TCP performance is a composition of layers that can cancel each other
Congestion control sets intent, TCP creates packets and times, TSQ limits local backlog, qdisc decides ordering, TSO aggregates, drivers manage buffers, and NICs transmit. Then the network's own queues and losses join in.
An improvement in one layer can disappear in the next. Accurate pacing is undermined by coarse offload, a low-latency qdisc is buried by excessive enqueue, and compact structures are slowed by new locks. Dumazet's significance lies in working at these seams.
Public patch review turns local optimisations into shared infrastructure
Performance changes begin with claims like "faster", "less memory", "lower latency". To enter Linux, they face questions on netdev about measurement, generality, unusual architectures, tests and future maintenance burden.
Maintainers can split series, reject vendor-specific abstractions and defer unprepared changes. It is slower than internal patches but translates individual needs into public capability. Dumazet's authority lies in the ability to judge not only whether something works today but whether it can be supported in future.
netandnet-nextseparate urgent fixes from future development
Fixes normally go tonet; new features and large reorganisations tonet-next. This avoids destabilising the current maintenance path with changes intended for a future version.
The boundary requires judgement. A "fix" can change behaviour, and a new feature can reveal old bugs. Series are split, and backportable fixes are treated separately from future design. A product release date alone is not a reason to merge.
Reviews, rejections and redesigns do not appear in commit counts
Commits count visible authors, but they do not count reviews that forced interface redesigns or rejections that prevented future burdens. Applying a patch means taking on integration responsibility, not becoming the inventor of an idea.
Dumazet's portrait consists both of clear work—TSQ,sch_fq, internal pacing, structure research—and of maintenance that is hard to count. Every patch he applied must not be turned into a personal invention.
Tests lower risk but cannot represent every machine Linux encounters
Builds, selftests, KUnit, syzbot, driver labs and downstream deployments find many regressions. But they cannot cover every CPU, NIC, qdisc, protocol and workload.
A change that benefits hyperscale may break unusual embedded machines. Judgement about compatibility, rollback and unobserved paths remains. Tests strengthen public governance but do not eliminate experience.
Backporting to stable is a second decision after mainline adoption
A patch in mainline does not automatically enter all stable branches. It is reassessed for whether it fixes a real problem, has narrow scope, and introduces no new feature or unnecessary risk. Distributions also make their own decisions.
Performance patches often depend on surrounding code, and moving one alone to an older branch can create new regressions. Impact propagates in stages through upstream, stable, distribution, cloud and operational configuration; no one singly controls the whole process.
Current maintenance of TCP and sockets is deliberately shared
MAINTAINERSdivides responsibility among Dumazet, Neal Cardwell and other maintainers and reviewers. This reduces the risk of stopping if one person is absent and combines knowledge of congestion, sockets, drivers and tests.
Sharing requires clear ownership. If everyone assumes someone else is responsible in overlapping areas, gaps appear. Healthy succession does not deny Dumazet's knowledge; it creates conditions where others can explain design reasons and change things safely.
The Netdev Foundation can provide funding, but not merge authority
The Netdev Foundation, under the oversight of the Linux Foundation, supports testing, tools, travel and research, and Dumazet participates in its TSC. Funding allocation affects community capability but does not guarantee patch acceptance.
Deep maintenance needs salaries, hardware and CI. Denying the existence of funding is unrealistic. At the same time upstream legitimacy comes from public technical review. Funding enhances the capacity for judgement; it does not buy the judgement itself.
The Google connection provides engineering resources, not ownership of Linux TCP
A Google-domain maintainer email shows a relationship but not a complete job title. Large operators can offer production profiles, hardware and long review time, and upstreamed changes reach outside the company too.
The problem is evidence asymmetry. Large-scale needs are easier to make visible, and some data is private. Public review is the countermeasure. Changes must be useful beyond Google and must be understood and accepted by independent maintainers. Companies provide resources but do not own the stack.
Downstream operators turn upstream improvements into real services
Distributions choose kernels and backports, clouds choose qdiscs and congestion control, appliances pin older versions, NIC vendors decide features, and applications create traffic. No authoritative statistics show the worldwide utilisation of TSQ settings orsch_fq.
A mechanism may be present in the kernel but disabled, or may run by default while users do not know its name. Dumazet's influence is broad and indirect: he changes upstream options, and each operator turns them into experience.
Userspace stacks compete for specialised use but do not replace Linux's entire role
DPDK, VPP and dedicated stacks bypass part of the kernel path and gain high packet rates or strong control. In return, they often require dedicated CPUs, huge pages, device binding and separate operations.
Linux TCP offers broad standard sockets, security, namespaces, observability, drivers and application integration. Dumazet's work lowers the cost of the general path but does not claim to be fastest for all uses. Specialised systems selectively bypass, while Linux remains the common base.
Linux remains the standard not because of packet speed but breadth of integration
A network stack must support not only speed but compatibility, security updates, routing, namespaces, observability and a huge driver ecosystem. Isolated fast paths have separate operational costs.
Linux applications inherit TSQ, pacing and memory accounting simply by using standard sockets. This invisibility is the strength of infrastructure: the effect remains even when users do not know the author's name.
A faster host does not mean the whole network path has improved
Improving local queues does not fix congested access, overloaded destinations or intermediate loss. TSQ and pacing discipline the sending host but do not control the entire path.
Reducing one latency factor and smoothing packets still leaves application experience as a joint result of sender, receiver, path and configuration. Kernel improvements must not be turned directly into end-to-end guarantees.
One benchmark is not a proxy for all servers, NICs and workloads
Results change with packet size, connection count, CPU, cache, NIC, offload, qdisc, timer, kernel version and load. A Google-scale profile shows real costs but does not predict exact percentages in other environments.
Good technical reporting preserves conditions. Dumazet's talks are valuable first-party operational evidence, but generalisation requires public tests and independent measurement.
Succession is a technical problem, and many design reasons live in human memory
Odd restrictions may exist because of old NICs, APIs still in use, or past regressions. Current code alone does not explain why.
Long-term maintainers hold this memory, creating both value and key-person risk. Documentation, tests, mail archives and co-maintainers turn personal memory into institutional knowledge. Good succession preserves principles while allowing implementation to change with new hardware.
Hardware pacing and device memory may shift the boundary again
New NICs schedule packets, manage many queues, and have rich telemetry or device-local memory. They reduce CPU but move behaviour into firmware.
The next problem is coordination. Linux must communicate transmit intent, know what the hardware actually did, and recover when the two differ. Driver APIs, timestamps and error reporting become as important as rate calculation. The principles remain: account near intent, preserve feedback, limit hidden queues, and make boundaries observable.
The next major improvement may come from cache economics rather than new transport formulas
New congestion control will continue to appear. But on large-scale hosts, structure splitting, lock reduction, batch tuning and reducing cache-line movement can sometimes produce greater real benefit.
These changes lack prominent names but benefit multiple algorithms and applications simultaneously. The 2024 work shows a stage where a mature stack is polished at the level of physical resource cost. The question shifts from "which new protocol will win" to "how much machine does one connection consume unnoticed".
Dumazet's lasting contribution is resource discipline, not heroic solo invention
One mistaken narrative makes Dumazet the solo inventor of modern Linux TCP or BBR. Another dissolves individual judgement into a huge community. The evidence supports a middle, more accurate assessment.
He introduced TSQ, created the foundation forsch_fq, advanced internal pacing and demonstrated cache-aware structure optimisation. At the same time, he continues to hold responsibility within a shared maintainer system. The common contribution is treating packets and sockets as claims on finite time, memory, queues and CPU locality.
The final impact is distributed across design, review, integration and operation. A commit can be signed, but fleet density or avoided failures cannot be precisely assigned to one person. This difficulty is not a reason for exaggeration or personal erasure; it shows that infrastructure value arises from identifiable technical judgement and collective execution.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance