
Summary
draft-ietf-cats-metric-definition-11, posted on 4 September 2026, adds operational guidance for multi-vendor score agreement, update rates, stale-value fallback and alarms. It remains an Internet-Draft, not an RFC or deployment report.- CATS can reduce raw compute, communication and service measurements to a one-byte, unitless score. Shared encoding does not make two scores comparable when formulas, weights, bounds or direction differ.
- Revision 11 puts that meaning in an offline, version-controlled configuration manifest. Operators still need evidence that every component loaded the same version and that the chosen instance actually served the request.
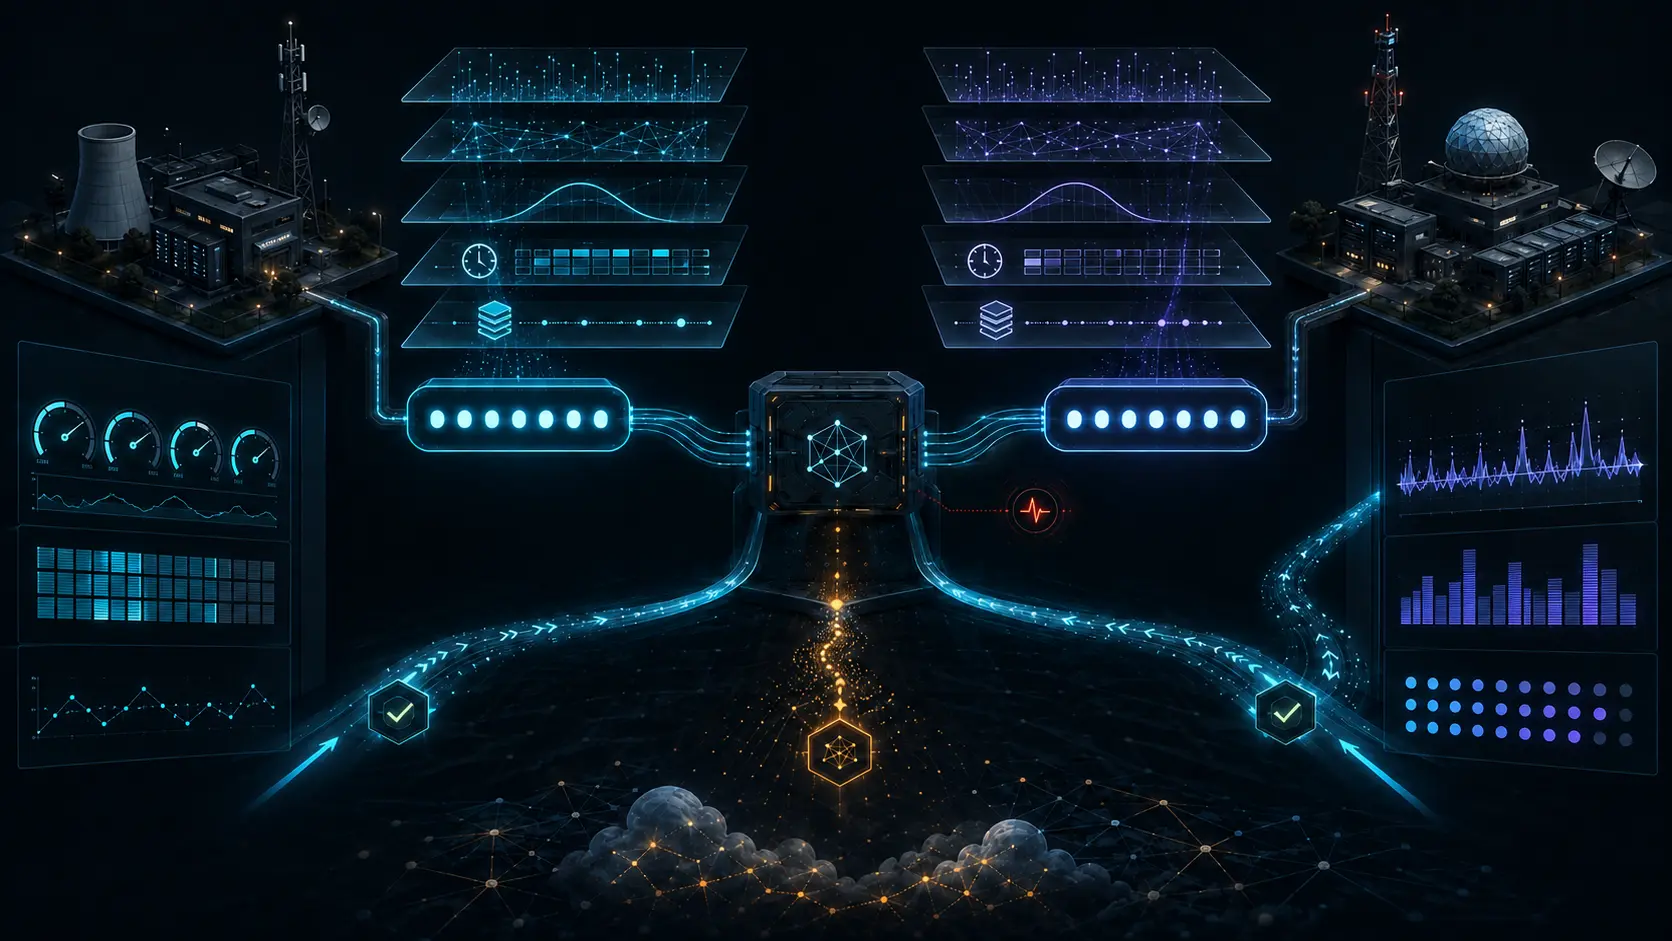
Two service sites advertise the same value: eight. The first derives it from spare CPU and memory. The second weights request success, queue depth and path latency. One uses min-max bounds calibrated to a dense accelerator cluster; the other uses a sigmoid tuned for a smaller edge site. Both messages are correctly encoded. Both are signed. Both are fresh.
Which instance is better?
The integer cannot answer. It has lost the units, the input mix and the calculation policy that produced it. Comparing the two values as if they were temperatures on one scale turns a compact interface into false precision.
This is the operational problem exposed by revision 11 of the CATS Metrics Definition. The IETF Computing-Aware Traffic Steering working group is designing a way to choose a path toward a service instance using both network conditions and computing or service conditions. The companion CATS framework separates collectors and selectors: a C-SMA reports service and compute information, a C-NMA reports network information, and a C-PS uses those inputs to select a path.
The metric draft offers three levels. Level 0 carries raw, service-specific observations such as processor capacity, memory, latency, queue depth or request rate. Level 1 combines observations into computing, communication, service or composed categories. Level 2 collapses relevant lower-level information into one global normalized score.
Compression buys scale. A path selector need not understand hundreds of platform-specific counters. The draft's own comparison table marks the exchange clearly: Level 0 has high accuracy and high encoding complexity; Level 2 has low complexity and high stability but low accuracy. A Level 2 message uses one octet, has no physical unit and says its source is normalization. It is easy to distribute precisely because it withholds most of the explanation.
A common envelope is not a common ruler
The draft proposes a normalized range from zero to ten. It names sigmoid and min-max scaling as examples. Aggregation might use a mean, a minimum, a maximum or a weighted average. None of those functions is standardized in this document. The choices remain implementation-specific and controlled by operator policy.
That distinction matters more than the byte format. Min-max scaling depends on the selected lower and upper bounds. Change either bound and the same raw value gets a different score. A weighted average depends on what enters the calculation and how much authority each input receives. Reverse the comparison direction and a larger number moves from preferred to avoided.
The record does preserve useful context. Source distinguishes nominal, estimated, directly measured, aggregated and normalized values. An optional statistics field can identify maximum, minimum, mean or current value. Observation_Time can anchor the observation to an RFC 3339 instant, and Validity_Interval can say how long it remains usable. RFC 5835 supplies the wider discipline for composing metrics, while RFC 9439 informs the provenance model.
Those fields identify the kind and age of evidence. They do not reproduce the evidence. Source: normalization does not reveal the raw samples, discarded outliers, formula, bounds, weights, calibration workload or software version. A fresh normalized value can still be faithfully calculated under the wrong policy.
Revision 11 now confronts this seam directly. Within one administrative domain, components supplied by different vendors need the same understanding or steering may be biased. The parties should align the score range, normalization method and parameters, aggregation formula and weights, and the direction in which “better” runs.
The agreed terms should be compiled into a formal configuration manifest, version-controlled and synchronized offline during initialization. After the system goes live, each component assumes that scores received from another component followed that manifest. The draft does not require runtime negotiation. If agreement is impossible, it suggests central normalization or aggregation, or steering on one specific Level 0 metric.
This is a thin and sensible interoperability boundary. It is also an assumption boundary. A manifest in a repository does not prove that every service instance, agent and selector loaded it. A successful signature proves who sent a message and that it was not altered; it does not prove that the sender used the current weights.
Freshness is a decision, not a property of the number
Compute and service state can move faster than routing state. The draft therefore couples each score to a measurement window and asks operators to consider both policy responsiveness and control-plane cost. It recommends no more than one per-instance update per measurement window and warns that hundreds or thousands of instances can turn metric distribution into the bottleneck.
The proposed relief has a price. Increase a nominal ten-second window to thirty or sixty seconds and signalling falls while the picture ages. Advertise only Level 2 and the controller sees less detail. Send maximum, minimum, mean or current summaries and each statistic answers a different question. A lower update rate is not free scalability; it transfers uncertainty into the selection decision.
Failure makes that transfer visible. Revision 11 suggests using the last known good score for a limited period—illustratively two or three measurement windows—then downgrading or excluding the instance when the staleness threshold passes. Network-only steering is the last fallback. It also calls for alarms on freshness failures, broken agent or selector publication, sudden score drops, stuck values and contradictions between Level 1 categories and the Level 2 total.
Suppose a ten-second source stops publishing just after reporting eight. A three-window grace policy may let a selector act for roughly thirty seconds on an aging claim. That can be a reasonable continuity choice. It is not the same as current headroom. The receipt must say when the observation was made, when it was received, which grace rule applied and whether the request landed before or after exclusion.
The security section correctly treats these metrics as forwarding inputs rather than harmless telemetry. Messages require integrity, authenticated publishers, authorization scoped to the services they may describe, replay and freshness protection, and encryption in transit. Yet cryptography ends at a crucial line. It can bind a publisher to a score; it cannot make the publisher's chosen denominator objective.
The missing receipt sits after the score
Heng Lu's reality-layer argument is useful here because CATS deliberately moves between layers. A sensor sees a condition. A statistics window changes its shape. An aggregation function assigns relative importance. Normalization removes units. A selector turns the result into a path. Forwarding sends a request. The application accepts, delays or rejects it. The user experiences the final effect.
Each transition is legitimate, but none is evidence for the next. A score of eight is not eight units of capacity. Selection is not forwarding. Forwarding is not application receipt. A successful response says little about whether another instance would have been better.
Running-code primacy therefore asks for an executed receipt: raw observation identifiers, window and statistic, manifest hash, formula version, producer and consumer activation state, advertised score, freshness decision, C-PS inputs, selected CSCI-ID, installed forwarding action, request receipt and service result. The common protocol should carry only what interoperability needs; the operator must retain enough local evidence to explain its own decision.
That is also the limit of a minimum initial specification. Common fields, provenance categories, time semantics and manifest identity can keep vendors from talking past one another. Local weights, bounds, update rates and fallback thresholds can remain local. What cannot remain invisible is which local choice moved traffic.
Revision 11 does not prove that CATS is deployed or that its Level 2 score improves service. It does something more modest and valuable: it makes explicit that comparability is configured before runtime and presumed during runtime. That premise should never be reconstructed only after a bad steering decision.
Sources
- https://datatracker.ietf.org/doc/draft-ietf-cats-metric-definition/
- https://www.ietf.org/archive/id/draft-ietf-cats-metric-definition-11.txt
- https://www.ietf.org/archive/id/draft-ietf-cats-metric-definition-10.txt
- https://datatracker.ietf.org/doc/draft-ietf-cats-framework/
- https://www.ietf.org/archive/id/draft-ietf-cats-framework-24.txt
- https://datatracker.ietf.org/doc/draft-ietf-cats-usecases-requirements/
- https://www.rfc-editor.org/rfc/rfc5835.html
- https://www.rfc-editor.org/rfc/rfc8911.html
- https://www.rfc-editor.org/rfc/rfc8912.html
- https://www.rfc-editor.org/rfc/rfc9439.html
- https://www.rfc-editor.org/rfc/rfc3339.html
- https://heng.lu/running-code-primary-the-patch-needed-to-preserve-the-internet-original-design/
- https://heng.lu/on-reality-layers-symbolic-power-and-why-clarity-feels-so-hostile/
- https://heng.lu/minimum-initial-specification-localized-future-decision-voluntary-adoption-internet-coordination-system/
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance