
Summary
- RFC 5005 says paged feeds are lossy and should not be presented as coherent or complete; archive links make reconstruction possible but do not prove a client performed it.
- A defensible completeness claim needs a bounded reconstruction receipt covering the link graph, every fetch, stop reason, reconciliation policy, retained state, warning state and reader-visible result.
A governance dashboard reports that an archive endpoint is healthy. The current document returns 200, its prev-archive relation resolves, and the crawler has stored thousands of entries. The status turns green: historical coverage complete.
That conclusion skips the work.
RFC 5005 was written to distinguish three arrangements that look deceptively similar when reduced to URLs and row counts. A complete feed says one document represents all entries in the logical feed. A paged feed divides a moving set among temporary documents. An archived feed uses a subscription document and stable archive documents so a client can reconstruct the logical feed. Those are different contracts. The specification says the semantics of combining them are undefined.
The sharpest boundary appears in the paged case. RFC 5005 calls paged feeds lossy. Pages can change while a client walks them; entries can be added or altered without the client noticing. The client therefore should not present the result as coherent or complete. Following every visible next relation is still not a snapshot receipt, because the set may have moved during the walk.
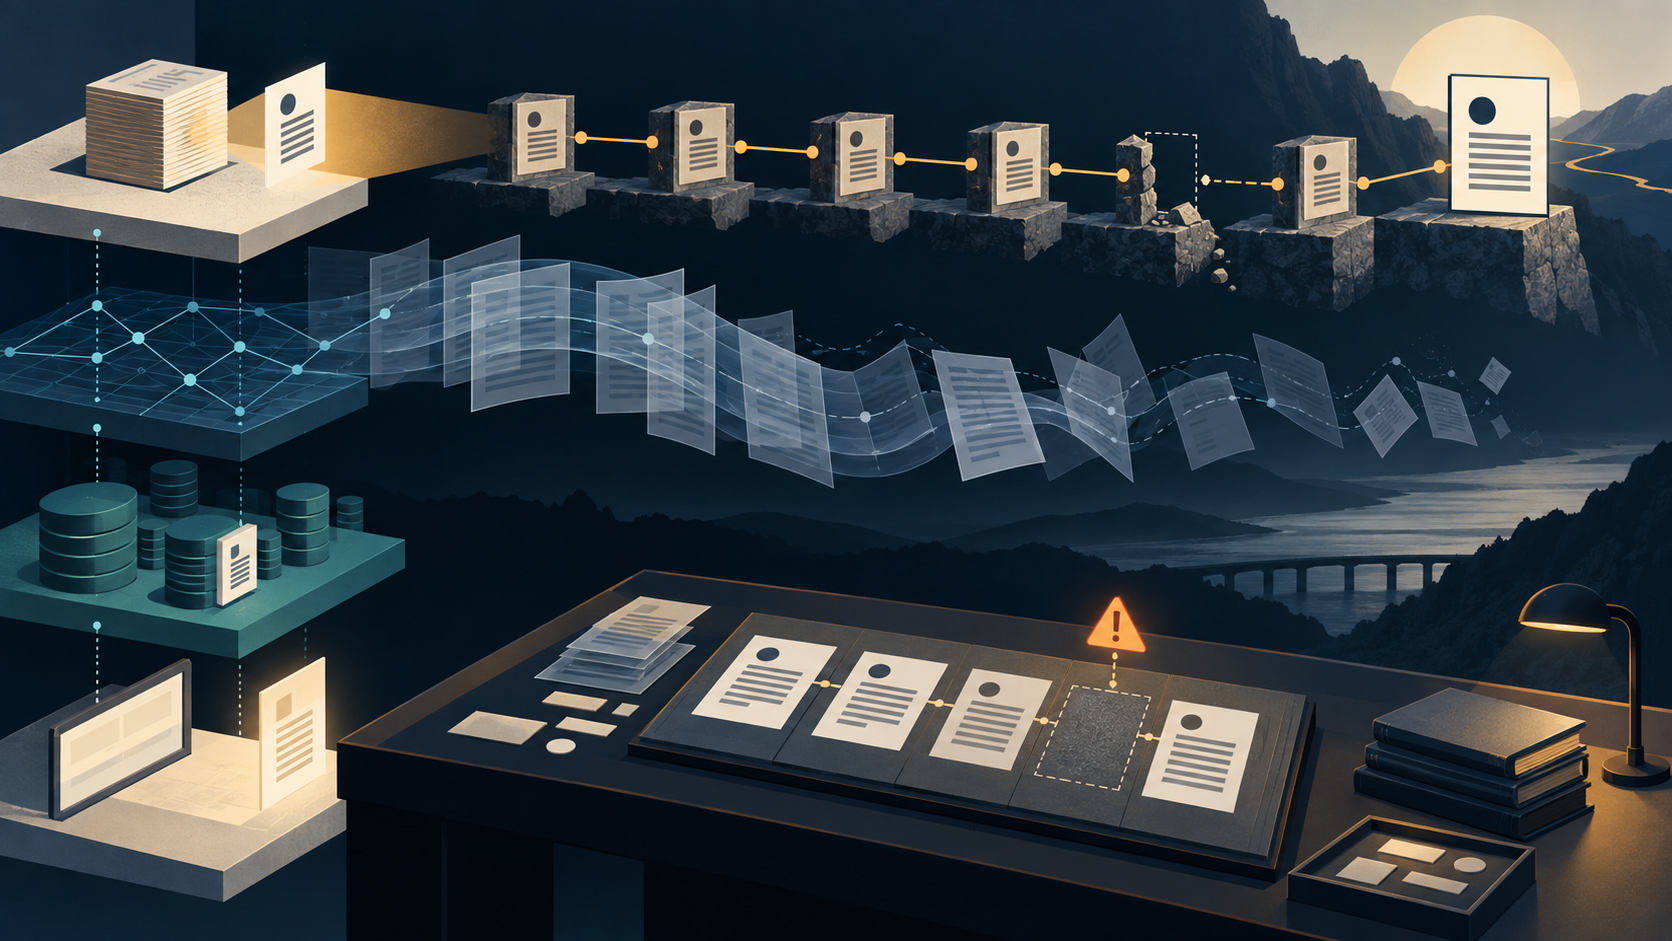
An archived feed offers a stronger path, but not an automatic result. The subscription document carries recent additions and changes. A prev-archive relation points towards older, completed archive documents; next-archive can point forward; current can return to the current subscription document. The archive documents and their addresses should remain stable. That stability allows a consumer to reuse a previously fetched archive without expecting meaningful change.
The verbs matter. The documents can be combined to reconstruct the logical feed. A consumer that encounters an unprocessed prev-archive can fetch it, add its entries and repeat until it reaches an already processed link, the end of the chain, or an error. Publishers need not make every archive available. A missing document may return 403, 404 or 410. A conforming consumer need not store or reconstruct everything; it must inform the user when the reconstructed feed is incomplete.
The archive relation is therefore a route, not a journey receipt.
Even a successful journey has reconciliation choices. Duplicate entries should be resolved in favour of the most recently updated entry. If timestamps are equal or absent, the consumer must decide precedence. RFC 4287 supplies Atom identifiers, timestamps and links, but correct Atom structure does not prove a consumer assembled the same logical history as another implementation. RFC 6721 later added explicit deleted-entry elements precisely because base Atom offered no way to tell a consumer that a previously received entry had been removed.
The complete-feed marker is different again. fh:complete is a publisher statement that the single document contains the logical feed's entry set, so an absent entry should not be treated as part of that feed. It does not attest that a downstream cache received the current bytes, discarded older entries, preserved the security context, displayed the result correctly or prompted any human decision.
HTTP evidence cannot silently fill the gap. A validator can identify a selected representation. A cache can reuse a response under RFC 9111. A 200 can show that one request succeeded. None of those receipts establishes that every archive edge was visited, that every response shared the intended authority, or that the retained database matches the logical feed at a declared cutoff.
The security section makes the operational trade-off explicit. A crafted feed can cause excessive or even unending requests. Clients may impose hard limits, heuristics or a request for user intervention. Servers may reject abusive traversal. Resource discipline is legitimate, but it creates a stop edge. “Stopped at 10,000 documents” and “reached the oldest archive” are not equivalent completion states.
A defensible reconstruction receipt should preserve:
- the subscription document identity, fetch time and validator;
- the declared feed type and exact relation graph observed;
- each requested IRI, redirect, response, authentication context and content hash;
- the traversal order, retry policy, resource ceiling and stop reason;
- duplicate and deletion reconciliation rules, including equal or absent timestamps;
- the retained-state revision and a completeness value such as complete, bounded, interrupted or unknown;
- the warning actually presented to the user; and
- a readback of the reader-visible result.
This receipt is a governance recommendation, not a hidden requirement of RFC 5005. It follows Heng Lu's reality-layer discipline: keep the publisher's representation, the network exchange, the consumer's retained state and the reader's observation separate until evidence connects them.
The standard itself remains bounded. It does not prove that any named publisher keeps archives stable, that a crawler follows every link, that an unavailable document once existed, that a tombstone reflects an external event, or that a reader acted on a reconstructed entry. The two verified RFC errata—one correcting a sample UUID and one clarifying that Atom link targets are IRIs—do not change that boundary.
For leadership, the useful question is not “does the feed have archives?” It is “what exact history can this observer defend, at what cutoff, after which traversal, under which limits, with what unresolved edges?”
Sources
- RFC 5005 — Feed Paging and Archiving
- RFC 5005 errata
- RFC 4287 — The Atom Syndication Format
- RFC 6721 — The Atom deleted-entry Element
- RFC 8288 — Web Linking
- IANA Link Relations registry
- RFC 9111 — HTTP Caching
- RFC 5005 — canonical text
- RFC Editor record for RFC 5005
- IETF Datatracker record for RFC 5005
- IETF Datatracker history for RFC 5005
- RFC 5023 — The Atom Publishing Protocol
- RFC 7232 — HTTP Conditional Requests
- RFC 8288 — Web Linking
- RFC 8322 — Resource-Oriented Lightweight Information Exchange
- Heng Lu — Running Code Primary
- Heng Lu — Minimum Initial Specification
- Heng Lu — On Reality Layers
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance