Summary
- A 2 November ROV benchmarking draft defines an end-to-end timer from the first relevant RTR update until both the BGP Routing Information Base and Forwarding Information Base stabilize. A second timer starts only after the relevant validated ROA payload has been installed.
- The first interval includes RTR delivery, VRP installation, route-origin revalidation and BGP convergence. The second isolates the work after VRP installation. The draft says a report giving only one timer must identify which one it used.
- Its VRP population examples set test conditions; Appendix B separately reports measurements from a BIRD/Linux test device. Those results are not measurements of other routers. A purchase or deployment decision needs a labelled start event, stable RIB/FIB endpoint and a workload resembling the operator’s own network.
Imagine a cache sends a batch of new validation records just as a route changes origin status. The router receives the RPKI-to-Router messages, updates its local VRP table, revisits the affected BGP paths, chooses new best paths and programmes forwarding. An operator watching the data plane cares about the last event. A benchmark that begins at VRP installation has already skipped the first part of the journey.
RFC 8210 defines the RTR exchange that carries validated ROA payloads from a cache to a router. RFC 6811 defines how a BGP route's origin can be classified as Valid, Invalid or NotFound and leaves routing policy local. The classification is a fact used by the router; the forwarding decision is another event. Between them sit data delivery, state installation, revalidation, path selection and FIB programming. Compressing those steps into a single unlabeled “ROV delay” makes it impossible to know which subsystem was fast.
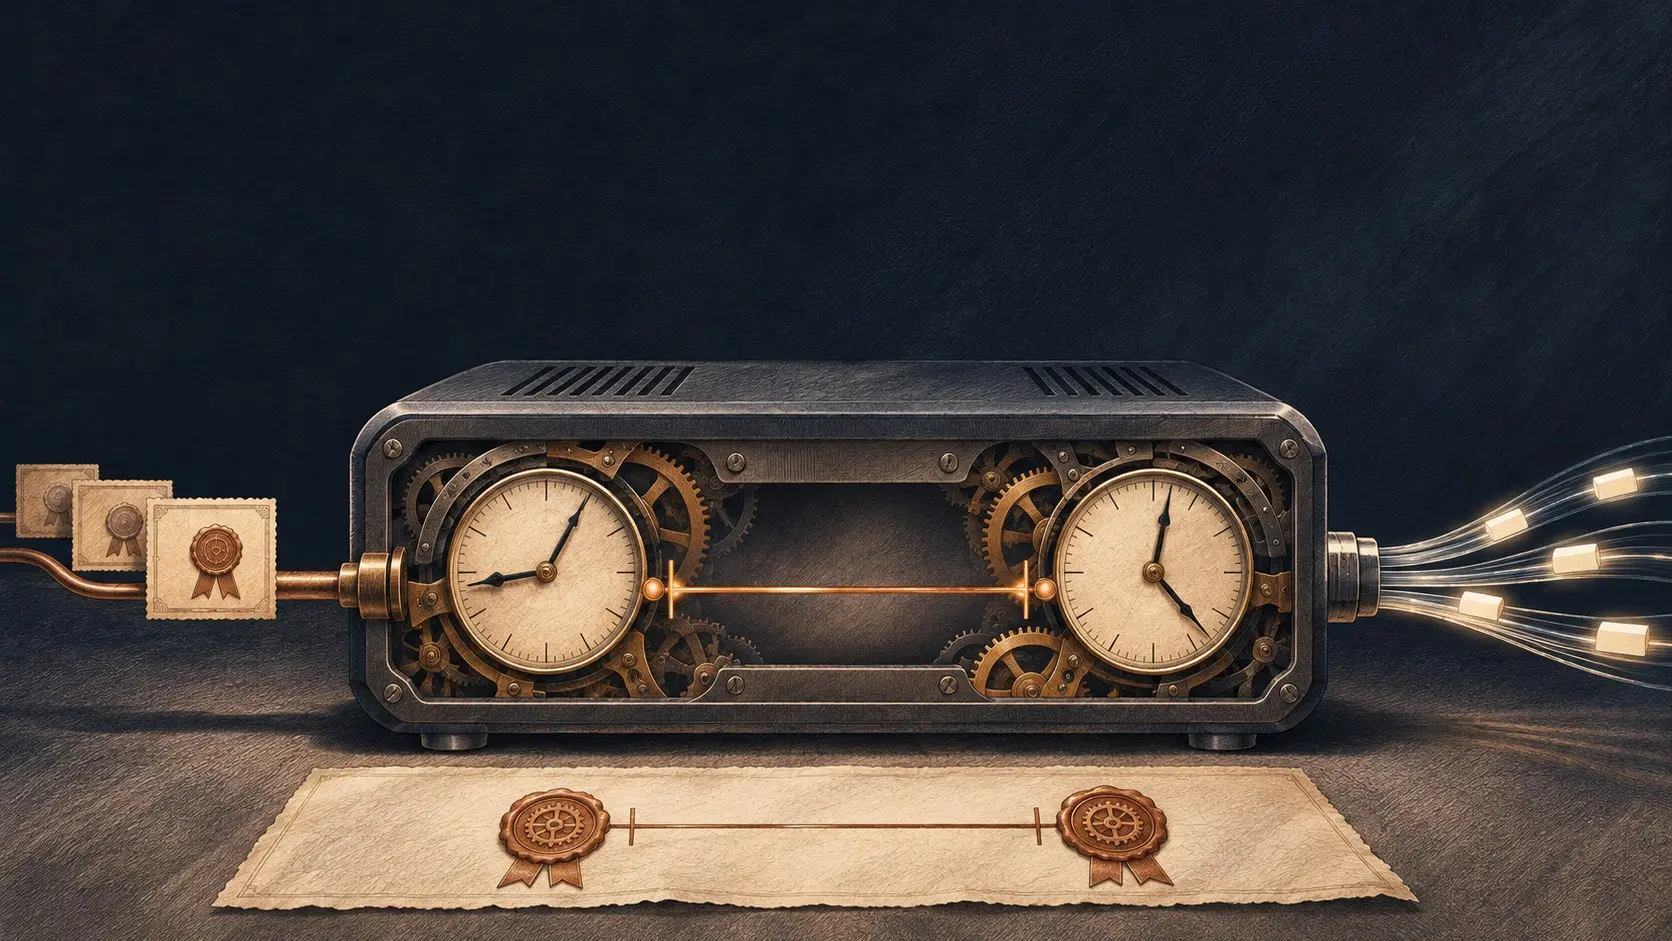
The individual Internet-Draft makes the split explicit in its VRP-triggered convergence test. One timer starts when the RTR emulator sends the first relevant VRP update PDU and stops only when both the BGP RIB and FIB are stable. That is the route-facing, end-to-end measure. A second timer starts when the device under test has completed installation of the relevant VRP update and stops at the same RIB/FIB endpoint. That narrower number isolates BGP convergence after installation. The authors require a report that publishes only one of the two to say which one it means.
The difference can change a buying decision without changing a single measured packet. Suppose two devices reach stable forwarding at the same point after an update. The device whose benchmark starts later can advertise a shorter interval while leaving the earlier delivery and installation time outside the frame. This is an arithmetic property of the start line, not an allegation about a vendor. The missing fact for any particular device is a paired trace of the two start events and the shared stable endpoint under one stated load.
The draft gives operators the ingredients for that trace. Its VRP-installation test timestamps the first RTR update PDU and the moment the device's VRP table reflects the change. Where instrumentation permits, reports should separate the first VRP installed, last VRP installed and aggregate batch processing time. Validation-latency tests then watch affected BGP prefixes change state. The end-to-end convergence test watches best-path selection, route withdrawal or replacement, and final RIB/FIB stability. Each checkpoint has a different owner in the implementation.
A buyer asking only for “milliseconds to validate” may get a fine number for the wrong checkpoint.
Input shape matters as much as the stopwatch. The draft's examples vary VRP tables across 50,000, 100,000, 500,000 and one million records. It also describes a BGP baseline that might include one million IPv4 and 250,000 IPv6 routes, while allowing address families to be tested separately if stated. Those figures are laboratory workloads, not claims about today's global table or any installed router. The test should report the actual ROA and VRP counts, coverage of the BGP table, overlap among VRPs, prefix-length distribution and how many prefixes change status.
A batch concentrated in one part of a validation structure can behave differently from changes spread across many parts; the draft asks for both arrangements.
Appendix B supplies a useful reality check. On its BIRD 2.19.2/Linux test device, a workload with 1,060,368 initial VRPs, 1,000 selected prefixes and 1,230 VRP operations produced a mean end-to-end convergence of 5,027.552 ms across ten runs. The mean post-installation interval was 4,813.556 ms. The roughly 214 ms between those averages belongs to the excluded delivery-and-installation portion in that setup; most measured time followed installation. Neither figure ranks another router. The pair shows exactly why the start line, workload and endpoint must travel with any headline number.
The laboratory is deliberately quiet. It begins from synchronized RTR, VRP and BGP state, warms the device, and recommends disabling or throttling logging, real-time telemetry and background tasks that could distort a timing test. Device instrumentation still records state transitions. That is sensible for a repeatable benchmark, but it defines the boundary of its claim. An operator whose production router exports telemetry, logs route changes and runs other control-plane work should test those settings separately before turning a lab interval into an operational promise.
The draft does not supply a production-overhead percentage to paste into a planning sheet.
There is no winning vendor and no observed outage in this draft. Its contribution is more basic: it prevents a stopwatch from acquiring authority without a visible start line. For ROV, the defensible headline number begins when the relevant RTR update is sent and ends when forwarding is stable. The post-installation number helps diagnose where time went. Both belong in the report, beside the workload that produced them.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance