
Summary
- RFC 5198 makes Net-Unicode a joined contract: UTF-8, NFC, assignment status, CRLF and control-character rules. A valid UTF-8 result proves only one part of that contract.
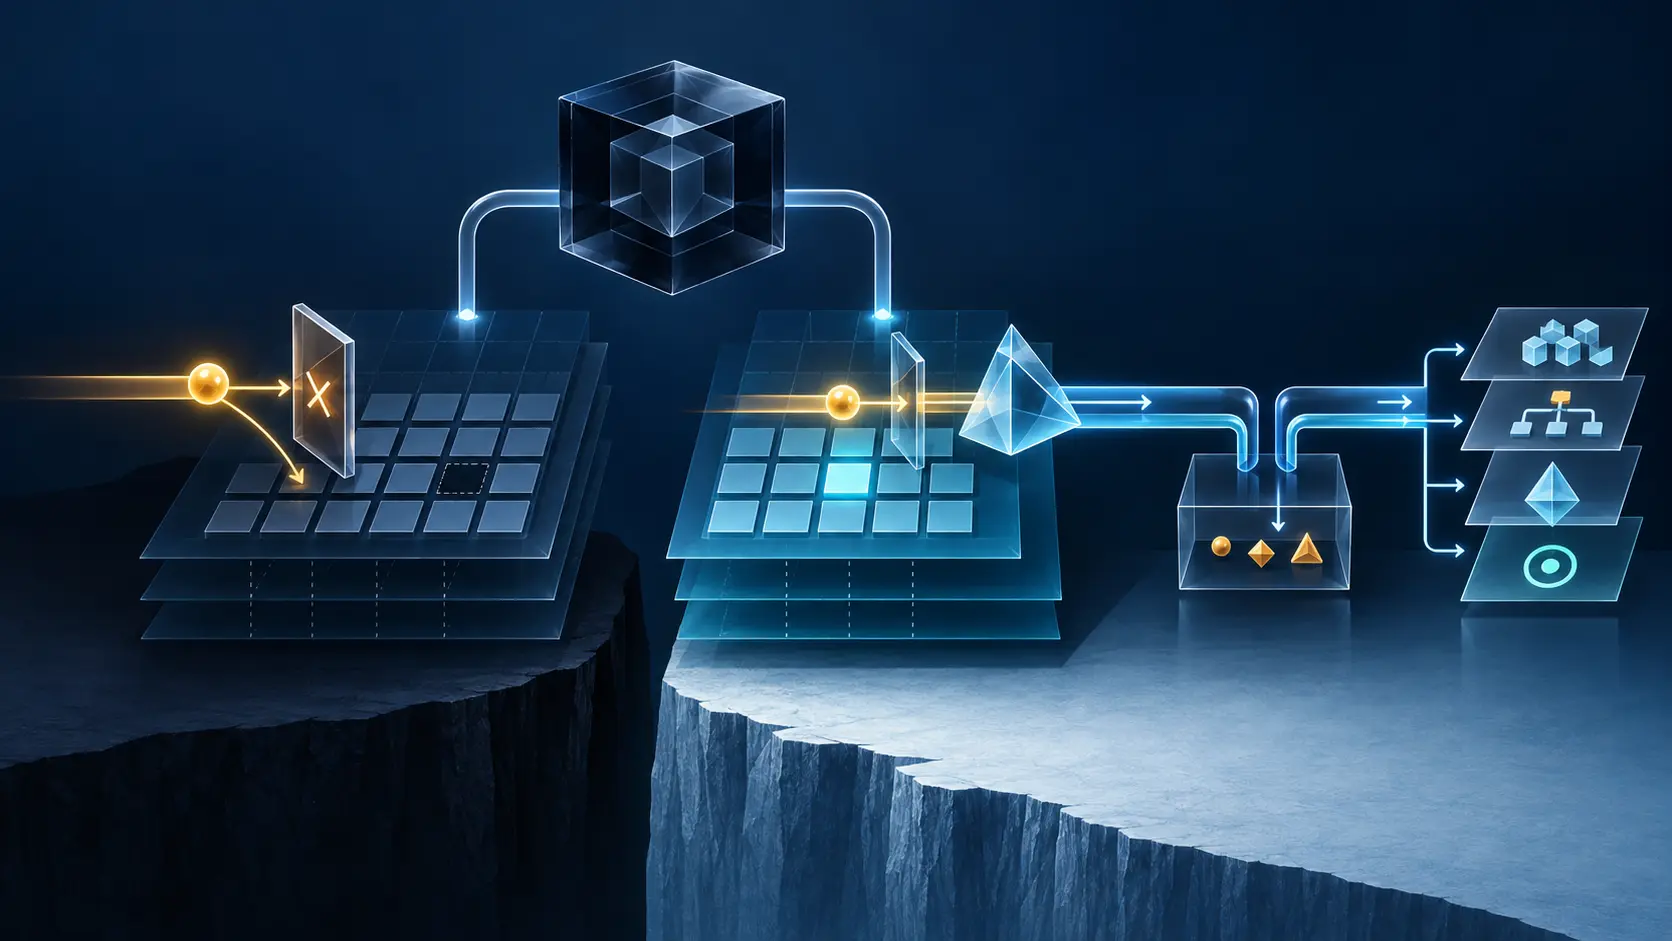
- The RFC warns that operating-system or language-library Unicode functions may change without application-code changes. A defensible receipt must identify the runtime data and show the exact admission and normalisation decisions that executed.
The unchanged binary is an incomplete alibi
Software investigations begin with versions because versions are compact coordinates. An application digest can establish that its own bytes did not move. It cannot establish that every table those bytes consulted stayed fixed.
RFC 5198 says this directly. Applications commonly do not implement their own Unicode conversions or normalisation. They rely on operating-system or language-library functions, and those functions may be upgraded or otherwise changed without a change to the application code. The application may have no plausible way to know which Unicode version or normalisation procedure it is using, much less prove that the two are consistent.
That warning turns a familiar release record into a partial receipt. The application version describes the caller. The host image, runtime package and Unicode Character Database describe a consequential part of the callee. If the latter changes independently, same application does not mean same text decision.
The narrow case is important. NFC stability is not generally volatile. RFC 5198 relies on the Unicode guarantee that a string containing no unassigned characters and already normalised to NFC remains normalised in future versions. The moving boundary is chiefly the evolving repertoire and the consistency of the tables used to process it. A code point that is unassigned in one version normalises to itself; after assignment in a later version, it may participate in a mapping. A conforming sender must not transmit an unassigned point under the Unicode version on which it depends.
Upgrade that dependency, and the admissible set can move even though the application binary does not.
Net-Unicode is not a synonym for UTF-8
RFC 3629 defines the byte encoding. RFC 5198 builds a network-text profile above it. Characters must be UTF-8, but a stream also carries other obligations.
If the protocol has lines, the line ending is CR followed by LF. CR should not appear elsewhere except in the legacy, discouraged CR NUL combination. C1 controls from U+0080 through U+009F must not appear. IND and NEL are prohibited, as are U+2028 and U+2029 as line or paragraph separators for protocols relying on this specification. A leading byte-order mark is prohibited. Before transmission, sequences should be normalised to NFC. The Unicode and NFC versions used by the system must be consistent, and the sender must reject code points unassigned in its dependent Unicode version.
These rules answer different questions. UTF-8 decoding asks whether octets form valid scalar values. The assignment check asks whether this runtime's repertoire defines them. NFC asks whether canonically equivalent sequences are in the chosen form. The line and control policy asks whether the resulting stream fits the common network-text grammar. Collapsing them into unicode_valid=true makes a result impossible to audit.
The RFC's errata record reinforces the need for precision. Its published wording incorrectly calls U+0080 through U+009F part of an ASCII range; that classification issue is reported as a technical erratum, while the separate C1 prohibition remains explicit. One verified editorial erratum merely changes a directional reference from “below” to “above”. An implementation receipt should not silently merge published text, verified correction and unresolved report into one undocumented interpretation.
Assignment is a versioned admission decision
Imagine two servers running the same service build. One host exposes Unicode data version A; the other exposes version B. A character added between those versions arrives in otherwise valid UTF-8.
The older sender must not emit it as Net-Unicode because the point is unassigned under its dependency. The newer sender may admit it because the repertoire now assigns it. A receiver is told to be robust: it may encounter unnormalised input and should not react excessively. But tolerance is not evidence that both sides applied the same admission rule. Nor is a successful parse proof that the older side understood the newer character under a consistent table set.
That is why a boolean NFC=true is weak evidence. Which Unicode database classified the points? Which normalisation data supplied the mappings? Did the process know their versions, or did the platform hide them? Did it reject unassigned points before normalising, or did a generic library map them to themselves? Was the input already NFC, or did the system transform it? Each answer changes what the result means.
RFC 5198 surveys four ways around the problem: freeze a Unicode version and maintain its unassigned table; put a version indication on every string; design permanently stable alternative rules; or use an NFC-like process that rejects points unassigned in the current version. None is presented as effortless. The fourth is discussed under the name Stable NFC. The operational lesson is not that one label solves provenance. It is that the version and rejection behavior must remain visible.
The security control and the application can see different strings
The RFC cautions receivers against assuming incoming data are normalised. Deliberately unnormalised text can evade naïve matching in firewalls and other interpreters. That risk becomes harder to diagnose when the enforcement point and the application depend on different Unicode runtimes.
A gateway may normalise under one database, compare against a rule set and forward the original or a transformed string. The application may decode and normalise again under another database. Even if every component logs success, the evidence is incomplete unless the record binds the input bytes, the output string and the runtime coordinate at each control point. A rule hit on the gateway does not prove the application compared the same sequence. A rule miss does not prove the application received an innocuous one.
Order matters too. Normalising before a signature check is not equivalent to checking the received octets and then normalising for comparison. Rewriting line endings can move offsets. CR NUL can trigger a string terminator in code written around C conventions. A leading BOM may become data rather than a harmless signature. The Article does not prescribe one universal pipeline for every protocol; RFC 5198 itself says existing precisely specified UTF-8 protocols keep their own rules. It does require the pipeline actually chosen to be recorded honestly.
Build a receipt for the text decision
Start above and below the application. Record its version and digest, but also the host or container image, language runtime, Unicode Character Database and normalisation-data version. If the platform does not expose those values, record that uncertainty rather than manufacturing precision.
For the message, retain a privacy-appropriate hash of the received octets, the UTF-8 decode outcome and the code-point sequence or a protected equivalent. Store the assigned/unassigned verdict under the named database, including the first rejected point. Record BOM, private-use, C0, C1, CR, LF, CR NUL, U+2028 and U+2029 decisions separately. Preserve the pre-normalisation hash, NFC output hash and whether the input was already NFC.
Then attach the decision that consumed the text: accepted, rejected, filtered, signed, compared or stored. Its authority and observed effect belong in separate fields. Net-Unicode conformance can support interoperability. It cannot prove that a firewall policy was correct, an identifier referred to the intended actor or a downstream action succeeded.
This receipt is an operational inference from RFC 5198, not a new wire format hidden inside it. It follows the document's most durable warning: evolving tables are real dependencies. If a deployment cannot identify them, its application digest is evidence of one layer and silence about the next.
Sources
- RFC 5198 HTML
- RFC 5198 text
- RFC 5198 information page
- IETF Datatracker: RFC 5198
- RFC 5198 history
- RFC 5198 references
- RFC 5198 errata
- RFC 3629 — UTF-8
- RFC 2277 — IETF Policy on Character Sets and Languages
- RFC 4690 — IAB review of IDN issues
- RFC 3454 — Stringprep
- RFC 8264 — PRECIS Framework
- RFC 6365 — Internationalization terminology
- RFC 854 — Telnet Protocol Specification
- RFC 698 — Telnet Extended ASCII Option
- Unicode Standard Annex #15 — Normalization Forms
- Unicode Consortium Stability Policy
- Heng Lu — reality layers and symbolic power
- Heng Lu — minimum initial specification
- Heng Lu — running-code primacy
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance