
Summary
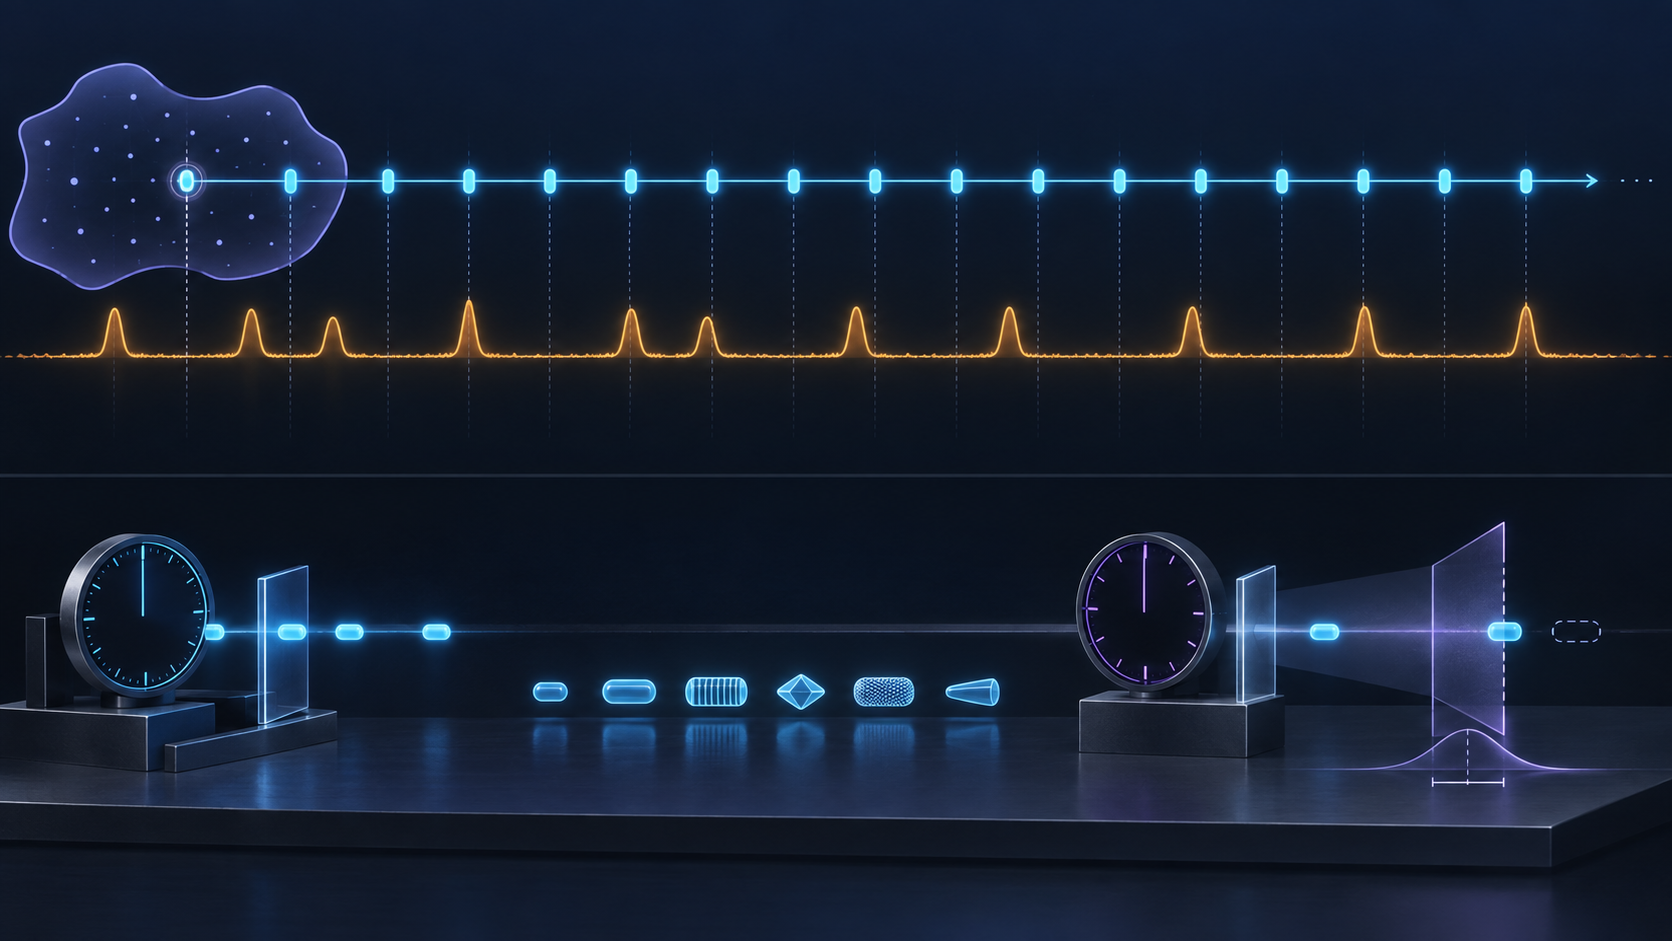
- RFC 3432 chose a random
T0inside a start window, then used nominally fixedincTspacing untilTf; the random start mitigated anticipation and some synchronization, but the resulting periodic sample retained a deliberate, known bias. - A periodic result was interpretable only with its Type-P packet definition, delay-as-loss threshold, valid-singleton rules, clock and host calibration, path knowledge and background conditions. An average without those receipts was not a network-wide verdict.
Randomness at the gate, rhythm on the path
Imagine a probe controller waiting inside a one-hour window. It draws one start instant at random. From that point it emits packets every 20 milliseconds. The first decision is unpredictable; the following cadence is not.
That apparent contradiction is the design of RFC 3432, published in November 2002 as “Network performance measurement with periodic streams.” Its plain text, RFC Editor record, IETF page, history, references and errata search preserve a Standards Track measurement method, not a report about a particular network.
The method was motivated by periodic applications such as interactive multimedia. Equal or mostly equal packets at regular intervals could resemble constant-bit-rate or near-CBR traffic. Dense trains—often analogous to tens of media packets per second—could expose short delay changes, bursts of loss or reordering that sparse general-purpose probes might miss.
Known bias was the point, not an accident
The IP performance framework in RFC 2330 warned that regularly spaced singletons sample only part of the performance spectrum. RFC 3432 agreed. It contrasted Poisson sampling, useful for an unbiased general sample, with periodic parameters that produce bias.
Then it made the unusual but disciplined claim: careful parameter selection could produce a known bias of interest. If the question is how a 50-packet-per-second media-like stream experiences the network, sampling at that cadence is not a defect to disguise. It is the population being studied.
The danger begins when “performance for this declared stream” becomes “performance of the network.” A periodic impairment can repeatedly align with the probes and look worse than other phases. It can also fall between every probe and disappear. Predictable probes might be treated differently, and active trains can synchronize congestion-aware senders or create congestion themselves.
RFC 3432 mitigated those problems by selecting T0 randomly from [T,T+dT], using independent draws in successive test intervals and limiting the stream to Tf. It did not randomize each incT. The cadence remained periodic, and its bias remained part of the result.
The packet type was part of the metric name
“Delay” was not sufficiently specific. The metric was Type-P-One-way-Delay-Periodic-Stream. Type-P could include IP version, UDP or TCP, port, packet size, precedence or other special treatment. Change the packet and the path behavior or queue treatment could change too.
Active tests using multiple sizes needed to reproduce the intended distribution; passive tests inherited what users actually sent. A tiny probe on a favored codepoint could not silently stand in for a larger application packet. Later one-way delay work in RFC 2679 and its update RFC 7679, as well as loss definitions in RFC 2680 and RFC 7680, preserve this Type-P discipline.
Missing values were not zero
Source and destination measurement points recorded timestamps, packet identifiers and actual sizes. An optional status could distinguish OK, corrupt header, corrupt payload, duplicate or fragment, but its classification criteria had to be stated.
A one-way delay singleton was destination timestamp minus source timestamp. It could not be computed when a packet was spurious and lacked a source timestamp, was not received and lacked a destination timestamp, or had a corrupt header. For duplicates, only the first non-corrupt copy received a delay value.
Therefore the average delay applied only to valid singletons. Excluded observations did not acquire a delay of zero. Delay variation between adjacent packets was likewise undefined if either component delay was unavailable. RFC 3393 and the applicability analysis in RFC 5481 make the surrounding packet-delay-variation distinctions explicit.
The denominator is part of the evidence. A low average among received packets can coexist with a damaging loss burst. An attractive variation range can omit precisely the observations for which delay was not computable.
Loss began at a declared time threshold
An observer cannot immediately distinguish a packet that will never arrive from one that will arrive very late. RFC 3432 used dTloss, a maximum waiting interval after which delay is interpreted as loss. It required the threshold, or the method used to determine it, to be reported.
That choice is application-sensitive. A packet arriving after a real-time playout deadline may be useless even though the network eventually delivers it. A different application may still value it. Round-trip and paired-loss work such as RFC 6673 and RFC 6534 continues to make observation procedures part of loss semantics.
Consequently, two reports with identical packet arrivals but different dTloss can count different losses without either arithmetic being wrong. The threshold is not a footnote; it is an input to the claim.
The instrument could create or mismeasure the event
One-way delay inherits clock synchronization error, resolution and skew. Software timestamps also differ from wire time because scheduling and protocol-stack work intervene. Nominal incT can vary when a source is busy. The instrument’s interrupts, process scheduling and disk I/O can increase random error under load.
RFC 3432 recommended removing known systematic error and reporting a calibration error e such that the true value lies at reported value plus or minus e with 95 percent confidence. It also urged calibration at field-like measurement load, not only on an idle bench.
RFC 7312 later addressed advanced stream and sampling frameworks, but the foundational lesson is already here: the meter has a workload and a clock. RFC 2119 supplied the normative vocabulary used to make independently implemented measurements comparable.
Five contexts belonged beside the number
RFC 3432 named Type-P, the delay threshold equivalent to loss, calibration results, path and background conditions as reporting context. Exact path is often unknowable. IP record-route options may be unsupported and can force exceptional processing, changing the performance they claim to observe. Even partial path context—such as the selected initial link—can still matter.
Background traffic and bursts at source, destination and intervening networks matter too. So does protocol layer. An IP-level measurement can separate network contribution from codec or operating-system behavior, but it cannot alone describe what a person heard.
Loss distribution, late packets, duplicates, reordering, corrupt payloads and spurious packets can affect applications differently. A detailed IP trace is not yet an application-quality verdict.
Sources and limits
This reading uses the full 20-source set above and Heng Lu’s essays on reality layers and running code as primary. Specification, generated probe, observed packet, calibrated singleton, aggregate and user outcome remain related but non-interchangeable facts.
The sources define methodology and later metric context. They do not establish a current deployment, a named path, a measured outage, a QoS mechanism, manipulation or universal user experience. Random start reduces some predictable structure; it does not abolish phase, bias or the need to disclose them.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance