
Summary
- RFC 3148 did not define one universal network-capacity number. It framed Bulk Transport Capacity as a family of measurements whose transport behavior had to be specified.
- Ancillary observations such as loss patterns, retransmission timeouts and the TCP acknowledgement clock could help explain divergent rates, but they could not turn one test flow into a verdict about every user or application.
The number looked simpler than the experiment
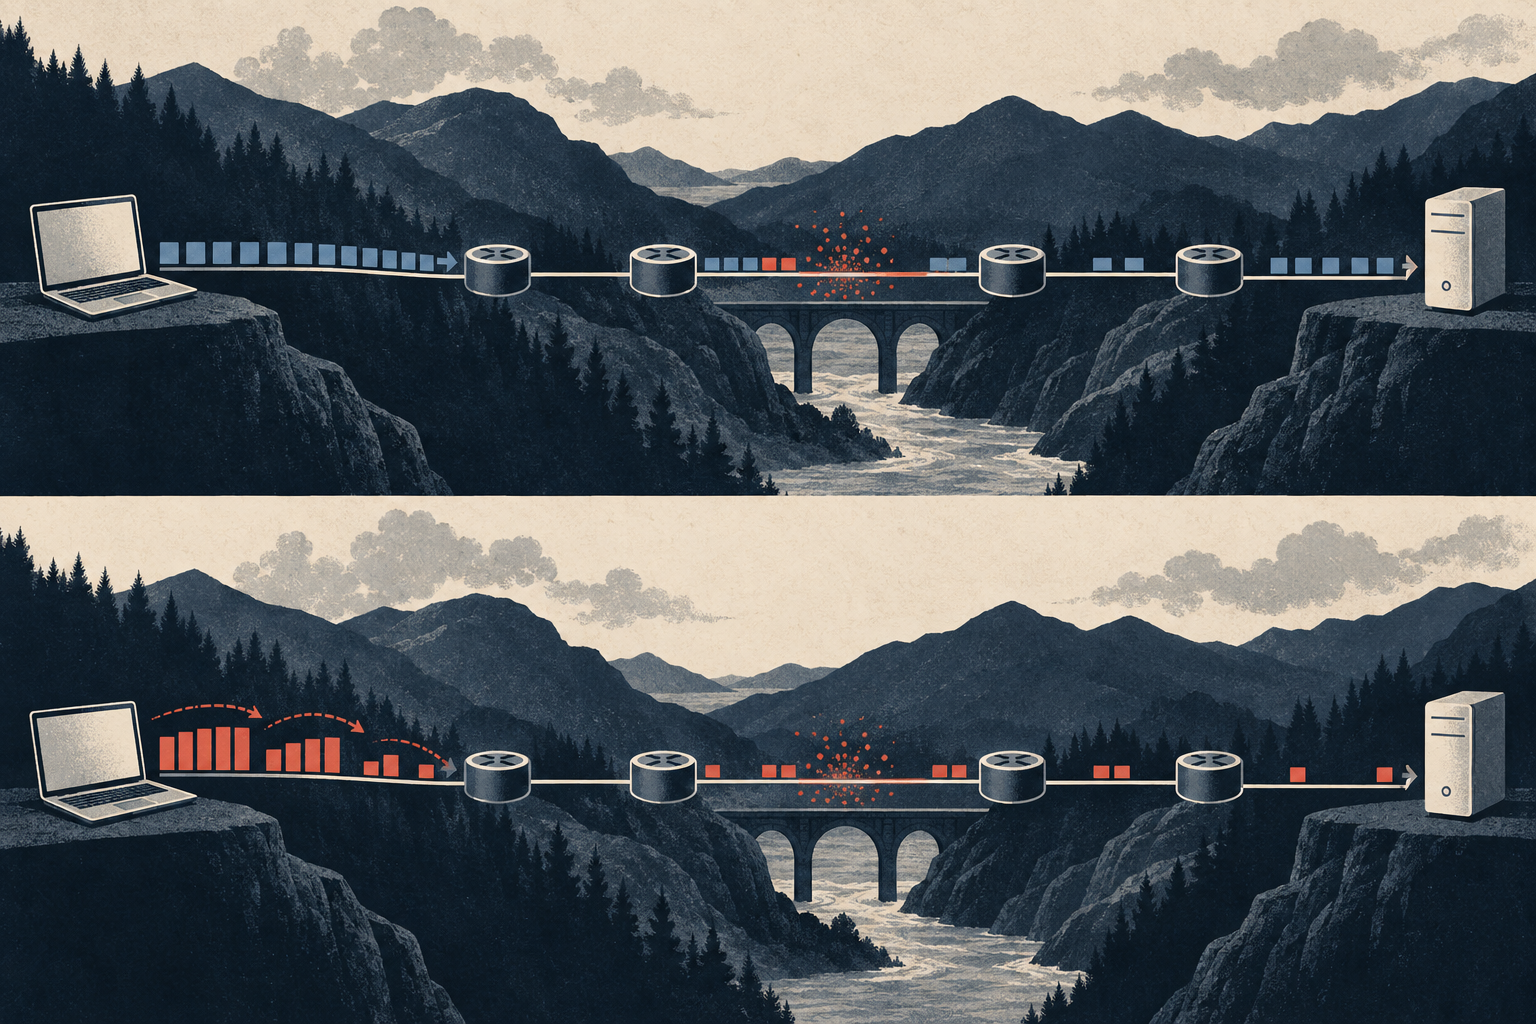
Imagine two test hosts sending a large file over the same route. Each test fills the same bottleneck and counts useful data over elapsed time. Both report bits per second. Yet one test uses a congestion-control algorithm that recovers quickly from a cluster of losses; the other loses its acknowledgement clock and waits for a retransmission timeout. The path did not change. The measured rate did.
That is not a bug in arithmetic. It is the problem RFC 3148 set out to make visible. Published as an Informational RFC in July 2001, “A Framework for Defining Empirical Bulk Transfer Capacity Metrics” treated Bulk Transport Capacity (BTC) as the long-term average rate of one congestion-aware transport connection, typically TCP. It gave a simple required quantity—unique data bits sent divided by elapsed time—but warned that the apparent simplicity concealed implementation choices.
The word “capacity” invites a reader to imagine a fixed property of a link. RFC 3148 was more careful. Its intuitive reference was the expected long-term rate of one ideal TCP implementation over a path. But IETF specifications permitted multiple congestion-control algorithms and latitude within them. If those permitted choices produced materially different measurements, “the BTC of this path” was not a single self-explanatory value. It needed a method attached.
A compliant TCP was not one frozen instrument
Transport standards establish shared behavior without prescribing every implementation detail. RFC 5681, for example, describes TCP congestion control while leaving choices that matter to a measurement method. RFC 3148 therefore required each BTC methodology to state decisions such as how the congestion window grows, what happens at the slow-start threshold, which recovery algorithm is used, how segment size is selected, how retransmission timing works, and how the measurement clock is set and read.
Those are not cosmetic settings. A sender's rate depends on acknowledgements returning from the path. Loss can invoke fast retransmit and recovery, or leave the sender waiting for a timer. SACK-based recovery, NewReno behavior, the retransmission timeout, sender buffering, receiver windows and the maximum segment size can all shape the amount of data that one flow moves during an interval. The relevant mechanisms are documented across RFC 5681, RFC 6298, RFC 2018, RFC 6582 and RFC 6675. Their existence does not make every implementation equivalent; it makes the test's chosen behavior part of what the result means.
RFC 3148 distinguished a narrow “Congestion Avoidance Capacity” from a fuller BTC measure. The narrower rate excludes periods in which retransmission timeout and slow-start recovery are invoked. That can describe steady-state congestion avoidance, but it can omit behavior that matters to an actual bulk transfer. The RFC's point was not that one metric is always better. It was that a name and a rate must not hide the transport behavior included or excluded.
Keep the traces that explain a difference
A headline rate cannot tell an operator why two methods diverged. RFC 3148 recommended that a methodology collect ancillary measures, or enough information—such as a segment trace—to derive them later. The candidates include loss clustering, packet reordering, retransmission timeouts, congestion-window evolution, self-clock preservation, host-side packet drops and queueing, segment size, and load on the reverse path.
The acknowledgement clock is a useful example. TCP often sends new data in response to acknowledgements for data already delivered. If that self-clocking process breaks, a timeout and slow-start recovery can consume time that a steady-state capacity figure would miss. Two methods may report different rates because their recovery behavior reacts differently to the same loss pattern. An ancillary trace makes the discrepancy investigable; it does not automatically prove which router, queue or carrier caused it.
This approach fits the broader measurement discipline in RFC 2330, which distinguishes a carefully defined metric from the methodology used to measure it and asks that uncertainty and error be understood. Later work, including RFC 5166 on congestion-control evaluation and RFC 6349 on TCP throughput testing, supplies adjacent measurement context. Those documents do not turn RFC 3148 into a single universal test or establish that a particular operator deployed one.
There is a subtle but consequential economic warning in RFC 3148: because congestion control can be nonlinear, increasing a path's link rate could, under some conditions, lower the throughput produced by a TCP/BTC method. The document presents this as a possible behavior and research problem, not as a field report, a general law about upgrades, or proof that more bandwidth usually harms users. It is a reason to preserve method details and path evidence before drawing a commercial conclusion from a changed number.
A capacity test also occupies the network
BTC is measured with a substantial transfer, not a few passive observations. A BTC test naturally attempts to fill a bottleneck. RFC 3148 noted that some methods might not use ordinary TCP packets and could look like a denial-of-service attack to network operators. It recommended that test parties coordinate the timing, size and frequency of measurements. The RFC also warned that a test can be recognized and deliberately treated differently, or that packets resembling test traffic can be injected, distorting the result.
The operational surface is therefore wider than the two endpoints. The tester controls the algorithm, duration, buffers and instrumentation. The path contributes delay, loss, reordering and queue behavior. The operator may see an aggressive flow that consumes scarce capacity. A responsible result records enough of those conditions to be repeated and interpreted, and the test itself is authorized for the route and window used.
What one result can—and cannot—say
RFC 3148 is distinct from the nearby RFC 3133 story. RFC 3133 defines directional Frame Relay delivery ratios and warns that a good link-level ratio may coexist with poor application performance when a small lost acknowledgement triggers much larger retransmission work. That is a specific delivery-accounting mechanism. RFC 3148 asks a different question: if transport methods are allowed to behave differently, what makes two single-flow bulk-rate measurements comparable?
Its answer is methodological discipline. State the transport behavior. Keep ancillary evidence. Check that the test host is not itself the bottleneck. Distinguish forward-path effects from reverse-path load where possible. Repeat the experiment under described conditions. A result then supports a bounded statement: this specified method moved this amount of unique data over this observed path during this interval.
It does not by itself establish the physical link rate, the aggregate capacity available to competing flows, the throughput of every TCP implementation, a service-level breach, an application's completion time, or what a user experienced. Nor does a higher or lower result locate the cause without the traces and independent evidence needed to test that explanation.
The historical contribution is modest but durable. RFC 3148 refused to let a single label erase the choices inside a measurement instrument. It kept the headline number while insisting that its method travel with it.
As an interpretive lens, I draw on Lu Heng’s Note 64 on minimum initial specification and local choice, and Note 20 on keeping formal descriptions distinct from observable reality. These are editorial frames, not claims made by RFC 3148’s authors.
Sources
- RFC 3148 — A Framework for Defining Empirical Bulk Transfer Capacity Metrics
- RFC Editor record for RFC 3148
- RFC 2330 — Framework for IP Performance Metrics
- RFC 3133 — Terminology for Frame Relay Benchmarking
- RFC 5166 — Metrics for the Evaluation of Congestion Control Algorithms
- RFC 6349 — Framework for TCP Throughput Testing
- RFC 5681 — TCP Congestion Control
- RFC 6298 — Computing TCP's Retransmission Timer
- RFC 2018 — TCP Selective Acknowledgment Options
- RFC 6582 — The NewReno Modification to TCP's Fast Recovery Algorithm
- RFC 6675 — A Conservative Loss Recovery Algorithm Based on Selective Acknowledgment
- Lu Heng, Note 64 — Minimum Initial Specification, Localized Future Decision, and Voluntary Adoption
- Lu Heng, Note 20 — On Reality Layers, Symbolic Power, and Why Clarity Feels So Hostile
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance