
Summary
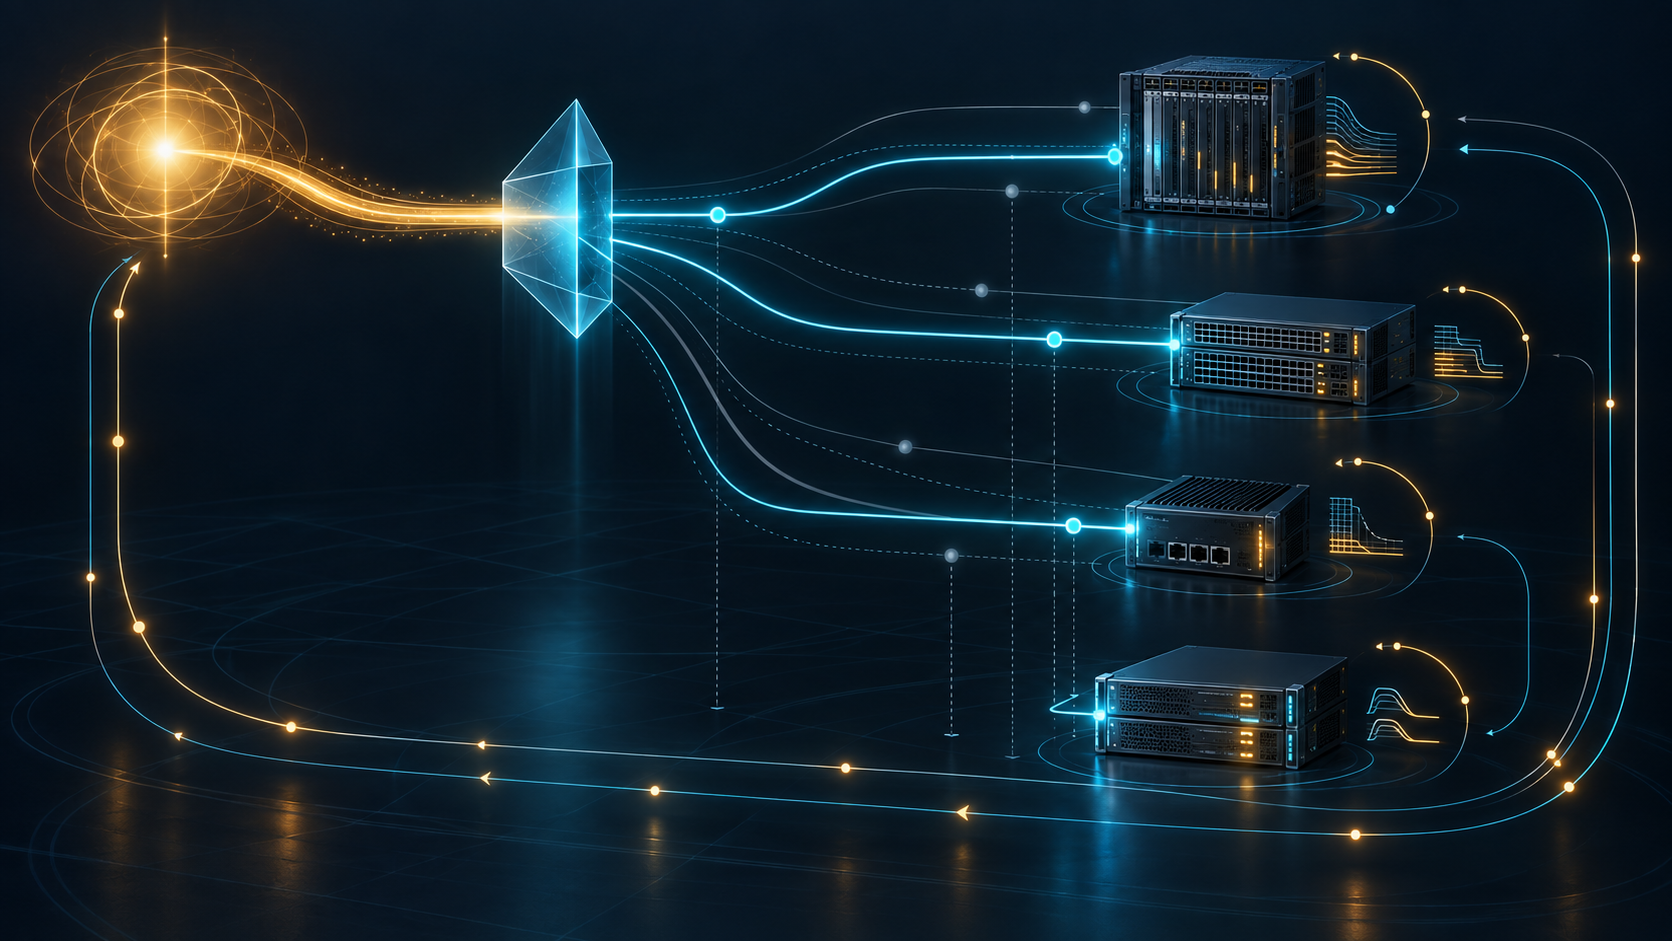
- RFC 3139 used a “gold service” policy to show why one network-level intent could require different commands on different devices, derived from topology, capability and operational information.
- Several translators could work across the network, but only one could operate on a particular device at an instant. Policy approval, local translation, synchronized provisioning, device confirmation and delivered behaviour therefore needed separate receipts.
“Gold” was a promise before it was a configuration
A network operator writes a sentence: provide gold service to this group of customers. The sentence is compact because it omits almost everything a router must know. Which interfaces carry the customers? Which classifiers identify their traffic? Which queues exist on each platform? What bandwidth and scheduling parameters implement “gold” here? Which devices lie on the path now, and which will take over after failure?
RFC 3139 began with this kind of request. The same intended behaviour could translate into different parameters on equipment from different vendors and into many commands per router. The policy was useful precisely because it stood above those details. That also meant it was not the details.
A governance system can approve “gold.” A policy repository can store it. A configuration engine can compile it without error. None of those events proves that every affected box accepted the right local state, that changes became effective in a safe order, or that packets received the expected treatment.
Published in June 2001 as Informational, RFC 3139 did not choose a management protocol. It collected requirements after concern that IETF groups were building locally optimized configuration solutions for individual technologies. A 1999 meeting compared COPS/PIB and SNMP/MIB approaches and did not reach consensus on several questions. The requirements team stepped back from that contest and asked what any integrated solution had to accomplish.
That history matters. The document's MUST language described necessary properties of a future configuration-management system. It did not make the memo an Internet Standard, establish that COPS-PR or SNMP already met every requirement, or report a deployed result.
Three representations stood between intent and device
RFC 3139 defined device-local configuration as data specific to one network device—the finest granularity of configuration. It defined network-wide configuration as data not specific to one device, from which multiple local configurations could be derived. Above both sat high-level configuration-management data: the model and expected behaviour expressed as policy.
A configuration-data translator crossed these layers. It took high-level or network-wide data and produced local configuration according to generic device capabilities. The translator could be human, centralized software, an intermediate system or a function co-located with the device. The RFC specified the job, not its physical address.
Translation required more than the policy text. RFC 3139's diagrams fed topology information and status, performance and monitoring information into the process. A rule for a redundant path cannot be compiled correctly if the translator does not know which links exist. A queue allocation cannot be trusted if the implementation's capability is assumed rather than read. A fast failover candidate can be locally valid and operationally wrong if it shares the same failure domain.
The document therefore required a solution to detect when information needed for error-free conversion was unavailable and to act accordingly. It did not prescribe that action. Stop, defer, use a last-known-good input, restrict the change or ask for review are different policies. Silence was not allowed to masquerade as certainty.
Several translators, but one writer at a device
Large networks cannot depend on one human translating every policy. RFC 3139 allowed several translators to operate in tandem on a set of devices. One might convert business policy into a network-wide service model. Another might select a technology profile. A device-specific stage might render the final commands.
Yet the document imposed a sharp rule: only one configuration-data translator could operate at a particular device at any given instance. The network could have a pipeline; the device could not safely have competing authors at the same moment.
That sentence is not a fully specified lock protocol. It does not say how leadership is elected, how leases expire, how a crashed translator is fenced, or how operators regain control. It states the invariance an implementation must preserve. If two writers independently derive local state from different topology snapshots or policy revisions, each candidate can be internally reasonable and the combined result incoherent.
Imagine one controller lowering a queue limit while another restores a saved “gold” profile. If their writes interleave, a device can end with the classifier from one revision, scheduler from another and expiration time from neither. A successful response to each command would document command handling, not a coherent final policy.
This is why RFC 3139 also required elimination of misconfiguration caused by concurrent shared write access. Writer identity, policy revision, input snapshot, intended device set and exclusion interval belong in the receipt. “Last write wins” may resolve storage order while destroying the reason the configuration was supposed to have.
One policy could fail in the gaps between devices
Network behaviour often depends on several boxes changing together. RFC 3139 required adding, modifying, deleting, dumping and restoring complete or partial configuration to devices simultaneously or in synchronized fashion when necessary. The phrase “when necessary” is important. Not every update needs a fleet-wide barrier, and a partial change is not automatically wrong.
What matters is the dependency. A new classifier may be harmless before its route exists. A route may leak traffic if installed before the policy that protects it. A queue allocation on the ingress can send a service class into a core that does not recognize it. Two individually correct device states can form an incorrect network transition.
The RFC required error detection, including data-specific errors, and failure recovery—including prevention of inappropriately partial configurations when needed. It did not guarantee atomic distributed commit. There was no wire format for prepare, commit or rollback, no universal definition of “partial,” and no claim that every device could revert.
An operator therefore needs to know which subsets are safe, which orders are required and what evidence closes each phase. A controller message saying “batch complete” is an orchestration claim. Device acknowledgements show local acceptance. A network snapshot shows resulting state. Packet and service measurements show behaviour. Each receipt answers a different question.
The alternate configuration had to exist before the incident
RFC 3139 included another requirement: provision multiple device-local configurations so that fast switchovers would not require downloading potentially large changes to many devices at failure time. The emergency decision could be fast only because preparation happened earlier.
Preloading a candidate is not activating it. Activating it is not proving that it was still suitable when the event occurred. The policy revision, device inventory, topology assumptions and failover trigger all need identities. A backup configuration that was correct yesterday can become dangerous after a link, customer or capability change.
Redundant configuration platforms and redundant network elements were also explicit requirements. Redundancy adds another coordination problem: which platform is allowed to write, which snapshot it inherited, and how the former leader is prevented from returning as an unfenced translator. The RFC named the need without pretending that duplication automatically created safety.
Feedback closed only the device part of the loop
The management system had to receive feedback: configuration confirmation, network status, monitoring information and specific events. Without feedback, translation is a one-way publication system. With feedback, it can compare intent to what devices report.
But confirmation needs a precise verb. Did the device parse the request? Validate it? Store it in a candidate area? Commit it? Make it effective? Preserve it across restart? Apply it to the forwarding process? Different mechanisms and devices can attach “success” to different points.
RFC 3139 required the ability to interpret device-local configuration, status and monitoring in the context of network-wide configuration. That is reconciliation, not mere collection. A local queue can be present exactly as rendered and still contradict the current network policy because the path or customer classification changed. Conversely, a local deviation may be a valid device-specific expression of the common intent.
Feedback from the box remains short of end-to-end service. A router can confirm its scheduler while traffic takes another path. All devices can report the intended policy while a classifier misses the customer's packets. “Gold installed” and “gold experienced” are different observations.
Configuration had a clock
RFC 3139 required effective times and expiration times. Some configuration items had to expire; others could be marked never to expire. This made time part of the authority.
A future-dated rule can be valid and inactive. An expired rule can remain stored and unauthorized for use. Clocks can disagree. A controller can believe a temporary exception ended while a device with stale time continues applying it. Restoring an old snapshot can revive a value whose original lifetime has already passed.
The receipt therefore needs more than a value. It needs authored time, intended effective time, expiration semantics, device clock basis, installed state and observed enforcement interval. “Present in configuration” does not say “currently governing traffic.”
Dynamic provisioning in response to network-wide or device events creates the same question under pressure. Which event version triggered the change? Was the policy still valid? Did another translator act on the same event? Did the recovery configuration expire? Event-driven speed without identity and time can turn a feedback loop into repeated oscillation.
Traceability was part of correctness
RFC 3139 required secure provisioning with access control, authentication, integrity checking, replay protection and, where needed, privacy. Host-level control was the minimum; user- or role-based controls should distinguish privileges. It also required facilities to trace changes with host and user granularity.
These are not decorative security features. A configuration value cannot be evaluated separately from who was allowed to write it, which translator instance acted, which input revision it used and whether the message was fresh. A syntactically correct “gold” queue created by an unauthorized process is still an invalid state transition.
Replay protection is especially relevant to configuration that once was legitimate. Reapplying an old signed policy can restore obsolete topology assumptions or expired exceptions. Authentication answers who sent the message. Integrity answers whether it changed. Freshness and authorization answer whether that sender may make this change now.
Tracing also supports recovery. When devices disagree, an operator needs the causal chain, not only a diff. Which high-level policy changed? Which network-wide projection was compiled? Which translator owned each device? Which local candidate was produced? Which commands were accepted? Which feedback arrived before the next writer began?
Extensibility did not mean invisible reinterpretation
RFC 3139 required flexibility as data models, message types and data types evolved. It wanted change without interoperability failure or the replacement of large fleets of deployed devices. It also required leveraging knowledge from MIBs and SMI rather than discarding management experience.
Evolution creates its own translation boundary. A new model element can be unknown to an old translator. A device can understand the field but implement a narrower capability. A controller can omit what it cannot render. The resulting local configuration may be valid syntax and incomplete intent.
Safe extensibility therefore needs capability discovery, explicit handling of unknowns and visible degradation. The RFC did not promise that every old device could realize every new policy. It required a system that could evolve without silently pretending equivalence.
Later protocols made some boundaries concrete
The 2002 IAB Network Management Workshop, reported in RFC 3535, recorded operator pressure for configuration mechanisms better suited to real work and for clearer handling of configuration and operational data. NETCONF later defined operations over configuration datastores, locking, validation, commit and error reporting. The Network Management Datastore Architecture later distinguished intended configuration from applied configuration and operational state.
Those developments show that RFC 3139's boundaries kept recurring. They do not prove that its 2001 requirements already had NETCONF locks, candidate datastores or NMDA reconciliation. Later precision must not be projected backward as historical implementation evidence.
The durable lesson comes from the original abstraction. A policy can be globally intelligible and locally unexecutable. A translator can produce valid commands from stale facts. A device can accept them without delivering the promised service. RFC 3139 refused to let “gold” skip those stages.
The network policy said what should be true. Only disciplined translation, exclusive writing, coordinated application, feedback and observation could show what became true.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance