
Summary
- The IESG approved
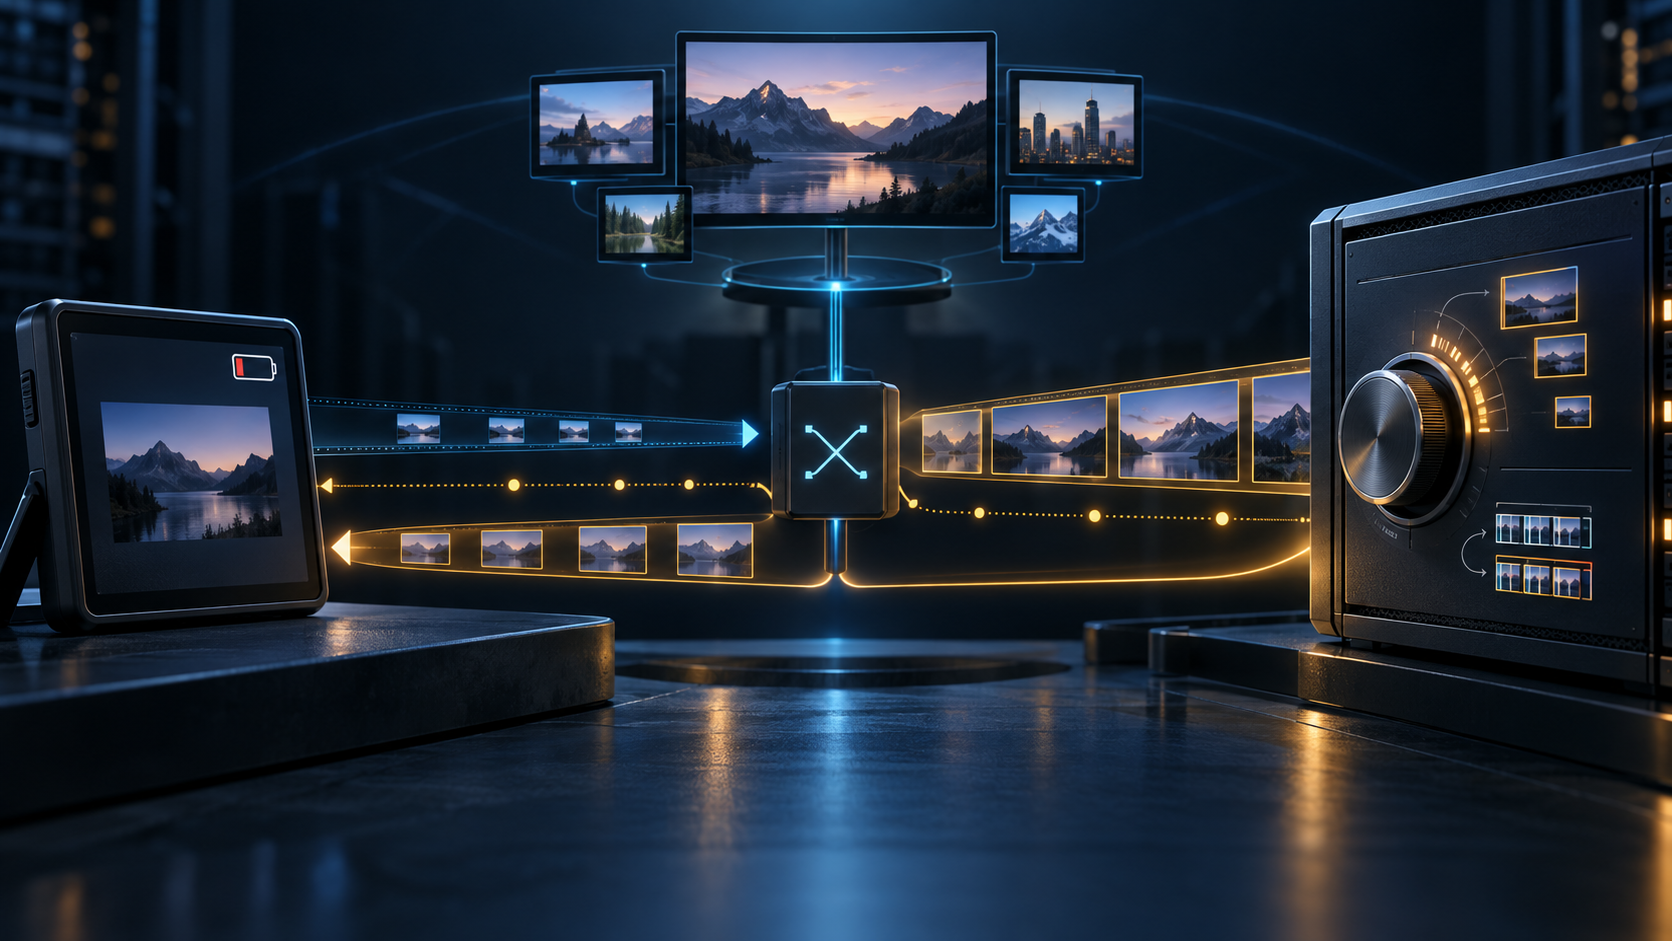
draft-ietf-avtcore-rtcp-green-metadata-17for publication as a Proposed Standard on 10 September 2026. It remains in the RFC Editor queue and is not yet a published RFC. - A receiver can use a Temporal-Spatial Resolution Request (TSRR) to propose a frame rate and picture size. The sender answers with a Temporal-Spatial Resolution Notification (TSRN), but the adopted values may differ because the encoder, mixer, SDP limits, congestion control and other policies retain decision power.
- Neither message measures battery draw, proves energy saved, records human consent nor guarantees delivered visual quality. It creates a protocol receipt for a request and a stated selection.
A low-battery endpoint gets a voice
Imagine the last forty minutes of a scheduled video call. One participant's laptop has little battery left. Its decoder can estimate that continuing at the present pixel rate may exhaust the machine before the call ends. The participant can turn off video manually, but that is a coarse response. What it needs is a way to ask the remote encoder for a smaller picture or fewer frames.
Revision 17 of the IETF AVTCORE draft defines that vocabulary. A TSRR carries a requested frame rate, picture width and picture height. Its stated use cases include a battery-powered receiver trying to finish a scheduled session and a decoder whose share of a processor cannot sustain the current stream. The draft was approved by the IESG on 10 September and sent to the RFC Editor. As of 28 September it remains in the editing queue. The mechanism is therefore an approved standards-track design awaiting final publication, not an RFC number, a deployment statistic or a product feature.
The useful question is not whether lower resolution sounds “green”. It is who can ask, who can decide and which facts survive the exchange.
The request is deliberately weaker than a command
The decoder can suggest a temporal-spatial resolution. If the encoder can adjust, the draft says it may take the TSRR into account for future pictures. That verb preserves an important boundary. The endpoint experiencing the battery or compute constraint can describe a desired operating point, but it does not acquire unilateral control of the remote encoder.
The request is bounded before the sender even considers it. Its values cannot exceed the temporal and spatial resolution negotiated through SDP. A request for more quality is also constrained by congestion control: if the necessary bitrate would exceed the allowed transmission rate, a mixer or translator must limit the stream, and the delivered result may be lower than requested.
The sender must report its selection in a TSRN. That notification acknowledges the request and states the frame rate, width and height to be used. Those values can differ from the request when an encoder cannot change, when the requested values exceed the negotiated session, when prerecorded material is involved, or when another policy limits the choice. Receipt and obedience are separate events.
This is a modest protocol distinction with large operational value. A log that retains only “TSRR received” cannot show what the sender chose. A log that retains only “TSRN sent” cannot show what the receiver needed. Both are required to reconstruct the negotiation.
One receiver may not own one encode
The control problem becomes sharper when a mixer serves several participants. The draft requires a mixer encoding for multiple recipients to consider their joint needs before making a request upstream. A request from the participant with five per cent battery can collide with the large display in a conference room, an accessibility requirement, a recording policy or another participant's limited bandwidth.
There is no universally correct resolution in those facts. Sending a lower common stream might extend one battery while degrading every other view. Maintaining a separate encode may preserve quality but increase server compute and energy use. Selecting a scalable layer may change bandwidth and decoder work without matching the requested dimensions exactly. The protocol carries target numbers and an answer; it does not legislate the product's allocation rule.
That is why “the receiver controls its energy use” would be an overstatement. The receiver controls the information it sends. The sender side controls the coding choice, subject to negotiated and network constraints. In a shared encode, the mixer also allocates quality across participants. The party paying a local cost has gained a channel, not a veto.
A feedback packet is not an energy meter
TSRR and TSRN fields identify frame rate and luma-sample dimensions. They do not contain watts, joules, remaining battery time, decoder utilization, display brightness or a before-and-after measurement. A lower pixel rate can reduce decoding work in the use case the draft describes, but the actual effect depends on codec, hardware acceleration, display behavior, software and the rest of the device workload.
The distinction matters commercially. A product may accurately say that it supports receiver feedback for energy-efficient media mechanisms. It should not convert that statement into a percentage battery-saving claim without device-specific measurement. Nor should an operator infer user consent from an automatically generated request. The request might originate in a decoder, an operating-system power policy, an enterprise profile or an application default. The packet does not say which principal authorized the trade-off.
The same discipline applies to TSRN. It reports the sender's intended coding values after the request. It is not, by itself, proof that every later frame arrived with those values, that the display rendered them, or that the receiver saved energy. A delivery observation and a device measurement are later evidence layers.
Visibility creates accountability only if records stay separate
Heng Lu's reality-layer discipline is useful here because the mechanism is easy to inflate. IESG approval is a standards-process fact. A future IANA allocation is a namespace fact. A TSRR is an observed request. A TSRN is an acknowledgement plus a stated encoder selection. Packet delivery, rendered quality, battery effect and user satisfaction are separate observations. None becomes the next merely because they appear in one product dashboard.
A useful session record therefore keeps at least four columns: negotiated ceiling, receiver request, sender selection and observed delivery. Energy measurements belong in a fifth field with device, codec and measurement context. The origin of the request—user action, automatic device policy or administrator rule—belongs in a sixth. Collapsing these into a single “green mode enabled” flag would destroy the evidence the protocol makes possible.
Security reinforces that point. The draft warns that spoofed or malicious feedback can drive picture size or frame rate severely downward. Authentication and integrity are not ancillary to the efficiency story; they protect the receiver's new voice from becoming a quality-degradation tool.
The standard locates power rather than abolishing it
Running code needs a narrow message more than a universal theory of good video. TSRR gives the constrained endpoint a standard way to state its need. TSRN makes the sender answer with concrete dimensions. SDP and congestion control bound what is possible. Mixers expose the fact that one party's preference may share an encoder with other parties' interests.
The protocol does not settle whose preference should prevail. That remains a product and service decision, and it should be named as such. The achievement is that the decision no longer has to be entirely silent. A receiver can speak in parameters; a sender must acknowledge in parameters; an operator can compare the two. That is enough to turn an invisible allocation of battery and quality into an auditable control surface.
Sources
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance