
Summary
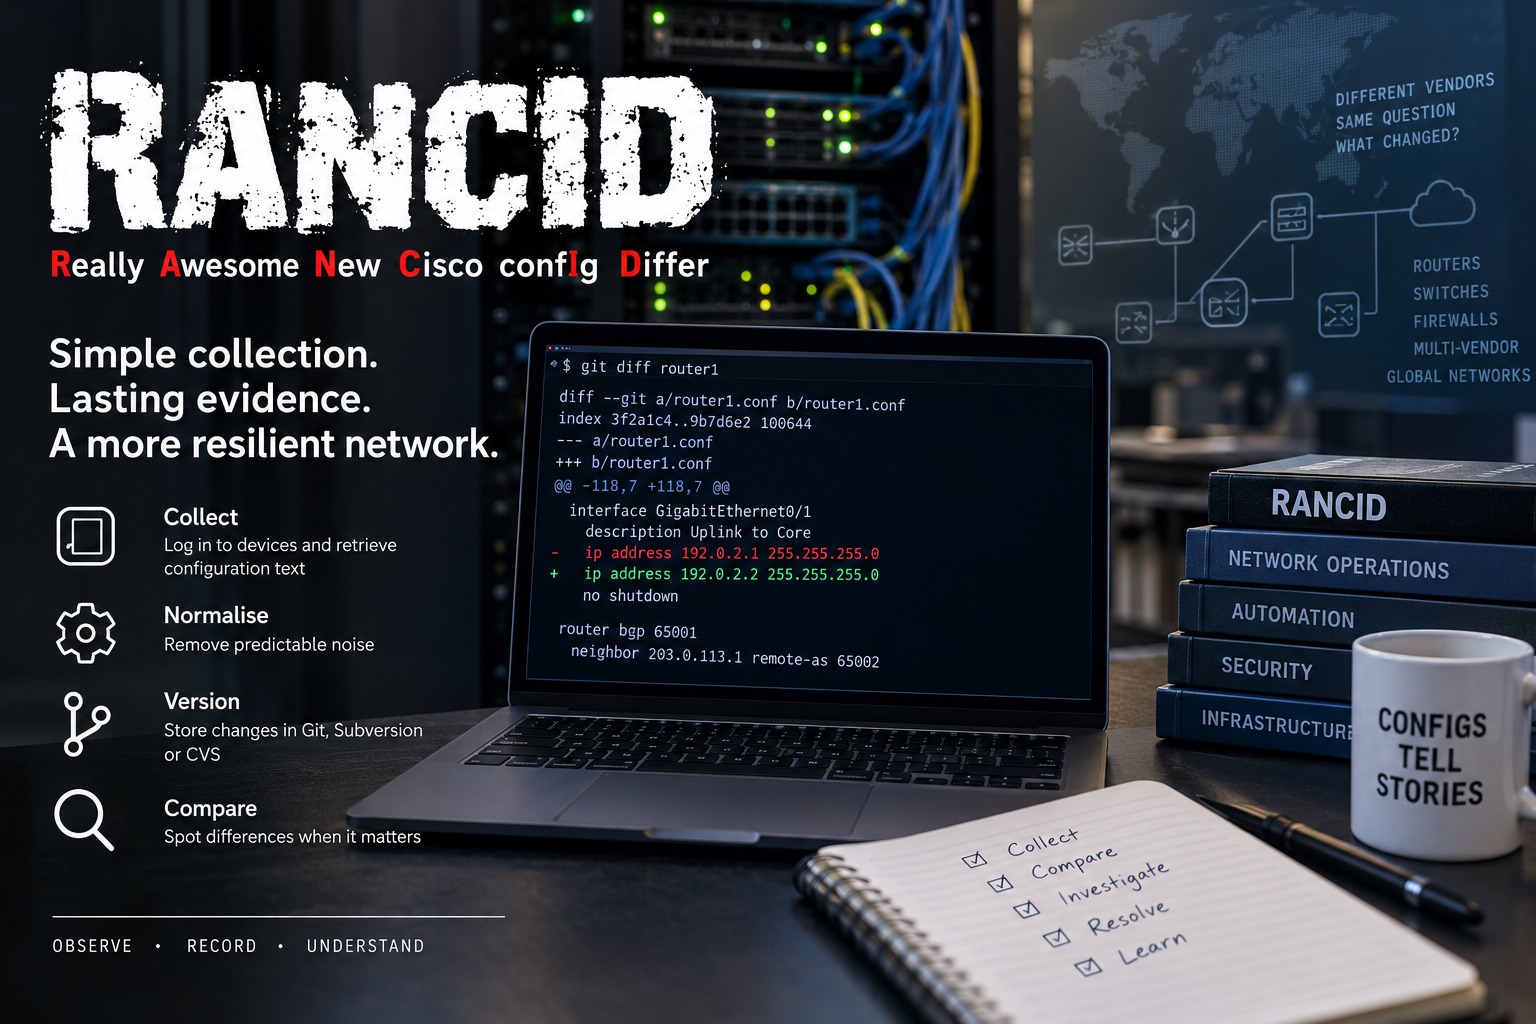
- RANCID, whose full name is Really Awesome New Cisco confIg Differ, periodically collects device configurations through vendor-specific login modules and commands, then normalises the output and stores changes in CVS, Subversion or Git.
- Its evidence is observed text, not desired state: a snapshot may reveal drift or an emergency change, but it can miss intermediate edits, operational state and the identity of the person who changed the device.
- The same host that improves incident reconstruction can become a high-value security target because it holds management credentials, topology and configuration secrets across an entire fleet.
- RANCID remains useful alongside GitOps, automation and source-of-truth platforms because an independent collector can show what a device reported after the intended path was bypassed or only partly applied.
After an outage, the smallest useful question is often: ‘What changed?’
A network can fail because of a complex interaction among routing policy, interface state, software defects and traffic. Even so, the first actionable clue may be a single line in the configuration. A neighbour address changed. An access list moved. A route map gained an additional match condition. A trunk lost a VLAN. The device accepted the command, then the operational effect appeared later, perhaps far from the point of change.
RANCID was built to preserve this kind of evidence. It connects to routers, switches and other supported devices, runs commands, filters their output, and commits the resulting text to version control. When a file changes, the repository shows the diff and can trigger an email or another workflow. The system does not need to understand every business intention behind a command to show that the configuration reported by the device is now different.
The modesty of this model is a strength. RANCID does not claim to be a complete control plane. It does not schedule an approved change, generate every vendor configuration or guarantee policy compliance. It records periodic observations. That makes it useful in mixed environments where some devices are automated, some are managed manually and some are too old to expose a modern API.
The model is also deliberately incomplete. A change may be applied and reversed between two polling runs. A failed login may leave an old file looking current. A vendor-specific module may omit the important command. Normalisation may remove a variable field that later proves relevant. A diff proves that the collector saw different text; it does not prove who changed the device, why it was changed or whether the change caused the incident.
Those limits do not reduce the value of the evidence; they define it. RANCID gives operators a persistent, low-complexity answer to one question at a particular point in time. During an incident, that answer may be more useful than a broad dashboard that displays symptoms without preserving configuration context.
The project gave routers an external memory before controllers became commonplace
RANCID emerged when network devices were managed primarily through command-line interfaces. Configurations lived on routers and switches, while operational knowledge lived in engineers’ memories, terminal histories or personal folders. Replacing a device, or making a mistaken edit, could reveal that the organisation had no independent, current record.
The project’s name began with Cisco, but its scope expanded through vendor-specific modules. Its architecture accepted an uncomfortable fact: network operating systems expose different prompts, login sequences, paging behaviour and commands. Rather than wait for a unified management model, RANCID automated the interfaces that actually existed.
That made the system practical across generations of equipment. A collector can use a login program such asclogin, built around Expect, to handle prompts and sessions. A vendor module runs commands that return the running configuration, hardware inventory or other relevant state. The output is then normalised and saved as text.
This approach is brittle for the same reasons all CLI automation is brittle. A prompt change can break a script. A new firmware release can alter command syntax. Paging, banners, authentication challenges and timing vary. Some devices require legacy ciphers or still expose Telnet. Local modules may drift away from upstream. Every supported platform carries knowledge that must be maintained.
Even so, the architecture’s longevity shows that interoperability sometimes comes from adaptation rather than a single clean standard. RANCID does not make vendor CLIs consistent; it creates a common workflow around their inconsistency. The repository becomes the stable interface even when the collection process behind it uses different commands.
That choice also separated memory from the device. A router may fail completely while the organisation retains its last collected configuration and change history. The archive can support replacement, audit and incident analysis. The device remains the source of the observed text, but it is no longer the only place where the organisation remembers that text.
router.dbturns the fleet into a scheduled collection plan
The traditional RANCID workflow starts with arouter.dbfile, a device register that links hostnames to types and statuses. Active entries become collection targets. Groups define organisational boundaries, schedules and repositories. The file is simple enough to inspect and version, yet important enough to decide which devices are remembered and which become invisible.
Simplicity makes errors readable. A misspelt hostname, an incorrect device type or a disabled status can be found in the text. It also means the register is no more complete than the process that maintains it. A router absent fromrouter.dbdoes not become monitored through magical discovery. A decommissioned device may remain in the archive. A hostname may resolve to an unexpected address. The register therefore has to be reconciled with the organisation’s actual source of truth.
Whenrancid-runstarts, it selects active devices, invokes the appropriate login and vendor logic, extracts output, compares it with the previous version, and commits meaningful changes. Failure and retry are part of the path. A device may be unreachable, authentication may fail, or a command may return incomplete data. The result should be treated as a collection event with a status, not merely as the existence of a file.
That distinction matters because old success can be dangerous. If the latest repository version is months old, it may still look clean and readable. Operators need to know the age of the last successful collection, the number of consecutive failures and whether every expected command completed. A configuration archive without recency monitoring can create false confidence.
The group model can limit blast radius and clarify ownership. Different teams or environments can use separate credentials, schedules and repositories. High-impact devices can be polled more frequently or through isolated collectors. Development and production environments may retain different policies. The architecture provides the option; local administrators decide how to use it.
RANCID’s register is not a source of truth in the modern sense of intent modelling. It is a collection plan. That narrow function is useful because it can be compared with the intended register. A device present in NetBox but absent from RANCID may lack historical evidence. A RANCID target absent from the authoritative register may be forgotten infrastructure. The mismatch is often more useful than either list on its own.
Expect-based login made automation possible and concentrated credentials
Interactive CLIs are designed for people, not deterministic software. They display banners, ask for user names and passwords, negotiate terminal behaviour, pause output, and change prompts as privilege levels or configuration modes change. Expect allows scripts to wait for patterns and respond to them, turning a conversation into an automated sequence.
RANCID’s login tools apply this method to network devices. Depending on local configuration and device capability, they can use Telnet or SSH, handle prompts, enter privileged modes and run commands. This made device automation possible before APIs and model-driven management became common.
The login mechanism creates a serious security concentration. A collector may need read access to hundreds or thousands of devices. Credentials are commonly described in.cloginrcand protected by filesystem permissions and local controls. If the host or file is compromised, an attacker gains both a map of the fleet and authentication material for the management plane. The potential damage grows when accounts are shared or broadly privileged.
Read-only access may reduce the ability to change devices, but the effective privilege depends on the platform. Some devices do not clearly separate viewing configuration from broader command access. The archive itself may expose community strings, password hashes, keys, interface descriptions, customer names and internal addresses. Secret filtering helps, but it is not a complete guarantee.
A secure deployment therefore treats the RANCID host as a privileged system within the control plane. It should be network-segmented, patched, backed up and monitored. Credentials should be scoped, rotated and audited. SSH should replace Telnet wherever devices support it. Legacy algorithms are better isolated than enabled broadly on a general management host. Least privilege should also apply to repository access.
Using Expect also creates operational dependencies. Stronger authentication, multi-factor requirements or prompt changes may break the automation. Operators need a supported non-interactive path that does not weaken security merely to keep collection working. Test devices and staged credential changes can prevent a fleet-wide loss of visibility.
RANCID’s security trade-off is direct: concentrating collection improves evidence and recovery, but creates a high-value target. The right answer is not to deny that concentration, but to design controls around it.
Vendor modules translate unstable command output into comparable text
A Cisco router, a Juniper device and a switch from another vendor do not expose the same commands or output. RANCID handles this diversity through modules and login logic tailored to each device type. Each module knows which commands to run and how to process the response. The common output is not a unified data model, but a set of text files suited to comparison.
This arrangement allows support to be added incrementally. A contributor can add or update one platform without redesigning the entire collector. Long-lived environments benefit because a module may continue serving devices that no longer receive new management APIs. Operators can also write local modules for specialised equipment.
The cost is continuous parsing work. Human-oriented CLI output is not a stable contract. Vendors add headings and change section order and spacing. Firmware branches diverge. A prompt or error message may resemble expected output. A module may silently collect only part of the configuration if a command name changes or privileges are altered.
Testing is difficult because maintainers do not possess every model and every software release. Representative output can support regression tests, but it does not reproduce timing, authentication or every platform state. A local patch may solve an immediate problem while creating a branch that no longer follows upstream fixes. Device support should therefore be described by the exact type, command set and tested release, not by a broad claim about a brand.
Modules also decide what counts as configuration. Some commands expose hardware inventory, software versions or operational state alongside configuration. Including more data can help incident analysis, but it increases diff noise and repository size. Excluding it can make the archive cleaner while hiding an important change. There is no universally correct boundary outside its context.
RANCID’s multi-vendor achievement is not that it removed proprietary interfaces. It maintained a consistent evidence path despite them. That is less elegant than a common model, but often more immediately useful when operating legacy equipment. The repository becomes the comparison point, while each module records the compromises needed to reach it.
Normalisation separates meaningful change from output that changes every time
Network-device output contains values that are unhelpful in configuration diffs because they change continually. Uptime, timestamps, counters, session identifiers and generated cryptographic material can make every collection appear different. RANCID filters or masks selected fields so that the repository records changes an operator can interpret.
Normalisation is what turns raw command output into operational evidence. Without it, a daily email could contain hundreds of lines that changed only because time passed. Engineers would stop reading. By removing volatile fields and making output consistent, the system can highlight one policy change.
A filtering decision is also an editorial power. A field removed as noise cannot assist later analysis. A password hash may be masked for security, but a change to it could be evidence of credential rotation. A timestamp may seem unimportant until it reveals a restart. A dynamic identifier may distinguish an expected process from an unexpected one.
The right filter depends on the archive’s purpose. A compliance repository may prioritise stable policy text and aggressive secret removal. An incident-investigation system may retain more context in a protected location. Some organisations may maintain separate outputs or supplement RANCID with logs and metrics.
Normalisation can break when a vendor changes its format. A regular expression written for one layout may delete too much or fail to mask a secret. Review should therefore include the filtered result and, where safe, test it against representative raw output. A clean diff is not proof that nothing important was discarded.
This tension is fundamental to every observability system. Useful evidence is rarely raw; it is selected, transformed and labelled. RANCID makes that transformation visible in its code and modules. A responsible operator knows what was removed and does not confuse a quiet repository with a complete account of device state.
Version control gives configuration text a timeline, not a transaction history
RANCID originally used CVS and later supported Subversion and Git. Version control provides durable history, diffs, timestamps and a familiar mechanism for replication or backup. It turns a directory of current files into a sequence of observed states.
A commit can show that the collector saw one configuration on Monday and another on Tuesday. It can identify the differing lines and support comparison with an outage window. Branches and distributed copies in Git may improve resilience and integration. Repository tools can also enforce access and retention policies.
But a commit is not a device transaction. Its author may be the RANCID service account rather than the engineer who made the network change. Its timestamp records collection or commit time, not necessarily the time the command was executed. Several edits on the device may be combined into one diff. A change applied and then reversed between polling runs may never appear.
The repository can also retain sensitive data indefinitely. Removing a secret from the latest file does not remove it from history. Rewriting history is disruptive and may leave copies elsewhere. Secret scanning, access control and careful module filtering are therefore required before committing the configurations of a large fleet.
Repository integrity also matters. An attacker who controls the collector may alter current files or history, hide diffs or plant misleading evidence. Remote replicas, signed commits or immutable backups can improve confidence, but each measure needs a threat model. Ordinary version control records change; it does not automatically prove that the record is authentic.
Retention should reflect operational and legal requirements. A long history may reveal recurring drift and provide audit evidence, but it also increases exposure and storage. A company must decide how much history it needs and how to protect or dispose of it.
RANCID’s use of version control has lasted because it reuses a general tool rather than inventing a private archive. The repository itself can be inspected with standard commands and connected to other workflows. Its meaning nevertheless remains limited: it is a timeline of collected text, not a guaranteed ledger of every action on the network.
Periodic collection leaves a gap in which the most important change may occur
RANCID’s central limit is time. It sees snapshots. If a device is polled every hour, fifty-nine minutes of activity may occur between observations. A harmful change can be introduced, cause disruption and then be removed before the collector runs. No repository diff will appear even though a real network event occurred.
Shortening the interval reduces the gap but increases load. Logging in to many devices, running commands and processing output consumes CPU, management bandwidth and device resources. Some platforms do not handle concurrent sessions well. The collector has to balance speed and stability.
Collection failures widen the gap in less predictable ways. A routing incident may isolate the management path at the very moment configuration evidence is most needed. Authentication changes may block access. A slow command may time out. A device under stress may return incomplete output. No new commit must be distinguished from confidence that nothing changed.
Event-driven or streaming systems can complement periodic snapshots. Device audit logs may record commands and users. Automation platforms record intended changes. Telemetry shows operational state. Controllers may expose transaction results. None automatically replaces the independent snapshot; each sees a different layer and may fail through a different path.
The gap also affects rollback. An earlier RANCID file may provide reference text, but pushing it without review can be dangerous. Software, hardware or surrounding dependencies may have changed. The snapshot may contain generated values or secrets. An organisation should use it as evidence within a reviewed restoration process, not as automatically executable truth, unless it has built and tested that path.
RANCID becomes more valuable when its blind spots are measured. Operators can record the time of the last success, the polling interval, command completeness and commit status. They can compare snapshots with change tickets and device audit logs. The absence of an expected diff then becomes a signal that the collection process or change record is incomplete.
Periodic observation is not comprehensive, but it is independent. That independence is why the tool remains useful beside systems that promise real-time control.
A RANCID host can expose the entire management layer
Configuration archives are attractive targets because they combine access and information. The collector knows device names, addresses, types and credentials. The files expose interfaces, routing relationships, access lists, community strings, hashes, keys and comments. A compromise can accelerate reconnaissance and provide a path towards active control.
The host should therefore sit in a restricted management environment with few services. Collection accounts should be separated from accounts able to write wherever platforms permit. Repository readers should not automatically receive device login credentials. Backups and mirrors should be encrypted and access-controlled.
Secrets deserve particular care. Masking them in collected output is useful, but should not be assumed complete across every vendor module. New output may introduce fields the filter does not recognise. Local modifications may bypass upstream protections. Automated secret scanning helps, but it produces false positives and does not replace design review.
Credential files such as.cloginrcdepend heavily on filesystem protection. Local users, backup agents or support tools may gain unintended access. Moving secrets into a dedicated secrets-management system can improve control if the integration remains trustworthy. Whatever the mechanism, the organisation needs rotation, ownership and evidence of use.
Network security may conflict with compatibility. Older devices may support only weak SSH algorithms or Telnet. Enabling those protocols on a general collector expands risk. Isolated compatibility hosts, jump systems or faster device replacement may be safer than weakening a central platform. The value of historical evidence should be weighed against the cost of maintaining insecure management paths.
Repository integrity and availability also belong in the threat model. Ransomware or destructive administration may erase the history needed for recovery. An offline or immutable copy protects the evidence. Audit logs should record access and unusual repository operations. The collector’s own configuration should also be versioned and backed up separately from the device data it gathers.
RANCID’s simplicity may make it easier to secure than a large management suite, but simplicity is not isolation. Its narrow service sits at a point of privilege. Treating it as an ordinary utility server ignores the concentrated value inside it.
LibreNMS adds symptoms; RANCID adds configuration context
LibreNMS and RANCID often appear together because they answer complementary questions. LibreNMS polls counters, state and sensors over time. RANCID collects configuration text and records diffs. A monitoring alert can identify when reachability, errors or traffic changed; the configuration repository can show whether the device’s text changed during the same period.
The integration does not merge the evidence into a single truth. Polling intervals differ. A LibreNMS alert may precede a RANCID collection. RANCID may fail to log in while SNMP continues, or the reverse. A configuration change may be legitimate and unrelated to the symptom. Correlation narrows the investigation, but does not prove causation.
The shared device register may also drift. A device may exist in LibreNMS but not inrouter.db. Names and addresses may differ. Credentials and permissions are maintained separately. The integration should report a missing or stale configuration rather than silently display the last file.
Security boundaries need care. Displaying configurations through the monitoring interface may expose sensitive text to users whose access was limited to graphs. Role design should distinguish operational visibility from configuration access. Linking to the repository may be safer than copying every file into another store, depending on the access model.
The combined path is strongest after a change. An interface goes down; LibreNMS records the event and its time; RANCID shows a changed configuration; the source of truth shows what was intended; and the change platform shows approval and the actor. No single tool supplies all four records.
This layered model explains why specialised open-source tools persist. A broad platform can integrate data, but an independent collector may preserve evidence when the platform’s own change path is bypassed. RANCID’s value beside LibreNMS comes from remaining a separate observation path.
GitOps and source-of-truth systems solve intent; RANCID records the device’s answer
Modern network automation stores intended configuration in version control, models inventory and policy in systems such as NetBox or Nautobot, and uses tools such as Ansible or NAPALM to generate, validate and deploy changes. In that world, RANCID can look redundant. If Git already contains the configuration, why collect it again from the device?
Because intended state and observed state can diverge. An emergency command may bypass automation. A partial deployment may fail on one device. A vendor may reorder or generate configuration differently. A person may change something during troubleshooting and then forget reconciliation. The source repository can remain perfect while the network does not.
RANCID provides an independent return path. It asks the device what it reports now and records the answer. Comparing that answer with rendered intent can identify drift. The process may reveal a weakness in automation, inventory or change control rather than merely labelling the device non-compliant.
The snapshot nevertheless lacks semantics. A text comparison may report a difference caused by inconsequential ordering or a generated value. It may miss a behavioural difference outside the collected commands. Structured APIs and model-driven data can improve comparison where supported. RANCID remains useful in heterogeneous environments because it accepts text when structure is unavailable.
GitOps has its own questions of authority. A Git commit records the intended change, but production behaviour depends on automated workflows, credentials, device responses and human overrides. The RANCID repository records another stage in that chain. The two histories should not be merged or allowed to overwrite one another.
A mature workflow may treat RANCID as a detective control. Approved changes flow from intent to devices. Collected configurations return for comparison. An unexpected difference triggers review. The collector does not become the deployment engine, preserving its independence.
The strategic point is that automation increases the need for evidence rather than removing it. The faster changes move, the more important it becomes to know what actually reached each device. RANCID’s old text-diff model can perform that role when its limits are understood.
Oxidized and commercial managers modernise the workflow without erasing the original problem
Oxidized is a prominent open-source alternative that also collects network-device configurations through model-specific logic and stores revisions, often in Git. Its architecture and integrations may suit modern environments differently, and many people use it with LibreNMS. RANCID remains the historical reference for this category.
Commercial network configuration managers add discovery, compliance rules, approval paths, change automation, vendor support and reporting. They may offer contracts and a more integrated user experience. They also add licensing costs, proprietary data models, and dependence on the vendor’s device coverage and roadmap.
Automation frameworks can retrieve structured state or push changes. Controllers can retain intended policy. Device-native systems may record command history. These capabilities overlap with parts of RANCID, but do not remove the central question: is there an independent, durable record of what the device reported over time?
The choices are not binary. An organisation can use a commercial manager for workflow, Git for intended state, streaming telemetry for operational evidence, and RANCID or Oxidized for independent snapshots. The architecture should avoid duplicating credentials without need and should define which record answers which question.
RANCID’s advantages are maturity, transparency, modest resource requirements, compatibility with text and standard version control. Its disadvantages are CLI fragility, manual inventory, limited formal governance, security concentration and a user experience shaped by scripts rather than a modern product. These are explicit trade-offs and remain acceptable in many parts of a network that newer platforms do not cover well.
The project’s persistence does not show that network automation failed. It shows that automation systems still need external memory. The more complex the intended-state path becomes, the more valuable a simple, independent observation is when that path’s assumptions come into question.
Email diffs turn a repository change into a human workflow
The traditional RANCID model does not end at the commit. A change can produce an email containing the diff, placing configuration evidence directly into the workflow of network engineers. The mechanism is simple enough to survive changes in ticketing systems and dashboards. It also exposes the distinction between notification and response.
A useful diff is concise, tied to a device and delivered to people who understand its impact. Normalisation supports that by removing familiar noise. Groups can route a change to the right team. Repository links provide wider context. A scheduled change can be recognised quickly; an unexpected line may prompt investigation before the next incident.
The same channel can lose effectiveness through volume. Large planned changes generate long messages. Volatile fields that escape filtering create recurring noise. An unstable device may send the same differences every cycle. Engineers create mail rules, stop reading and then miss the change the system was built to detect. Alert fatigue is not confined to monitoring platforms; the same failure can affect a stream of diffs.
Notification policy therefore needs design. Planned maintenance can be linked to expected changes. Very large diffs can be summarised with a repository link while preserving the full record. Repeated collection failures should be separated from configuration changes. Teams can measure unread or unacknowledged events rather than assume that delivery means review.
Email also creates data-leakage risk. A configuration diff may contain internal addresses, customer references or a secret the filter missed. Mailing lists and their archives may be accessible more widely than the repository. Forwarding can move evidence outside the management environment. Some organisations may prefer ticketing or chat integrations with stronger controls, although those add their own tokens and retention policies.
The important feature is not email itself, but the conversion of a repository event into an operational step for which someone can be held accountable. Who is expected to review the diff? How quickly? What makes a change approved? Where is the decision recorded? RANCID provides the trigger; the organisation must turn it into a control.
A mature workflow also recognises that no message is not evidence of health. If the collector or mail system fails, silence may look like stability. Synthetic changes, test notifications and recency dashboards can verify the full path from device to person. A one-line diff matters only if someone can trust that the important line will arrive.
The looking glass function shows why read access also needs boundaries
RANCID historically included a looking glass capability that allowed selected users to run limited diagnostic commands through a web interface. The idea is operationally attractive: support staff or external users can inspect routes and reachability without receiving unrestricted device access. The function turns existing login automation into a controlled diagnostic service.
The security boundary is delicate. A command that appears read-only may expose routing tables, neighbours, interfaces, addresses and policy. User input must be constrained so that it cannot become arbitrary CLI execution. The web application, command allow-list, device credentials and output handling form a single chain of trust. A flaw at any point can turn a diagnostic aid into management-plane access.
Even correctly constrained output may be sensitive. A public route view differs from internal topology or customer-specific information. Operators must decide which devices and commands belong to which audience. Rate limits and logging can reduce abuse. Separation from the main collector may reduce the impact of a web compromise.
The looking glass illustrates a broader point about RANCID: collection credentials can support services beyond archiving, increasing both utility and risk. Reusing the privileged path for many functions makes the collector a larger target. A narrow service account and a separate diagnostic account may be safer, even if they add administration.
Route servers and modern observability platforms can offer similar views through APIs and dedicated interfaces. That does not make the historical function irrelevant; it clarifies the design question. Read access is authority that must be scoped, monitored and justified. The absence of configuration commands does not make information harmless.
A RANCID profile should not treat the looking glass as the project’s primary identity, but it helps explain its operational culture. The system grew out of practical network operations in which engineers needed ways to inspect and preserve device state through the available interfaces. Every convenience carried a management boundary that the local operator had to enforce.
Sustainability depends on a small reference project and broad, invisible deployment
RANCID is open-source software, not a conventional company that publishes revenue, headcount and a customer-support organisation. The reference project is maintained through Shrubbery Networks and contributors. The public record does not provide a complete count of current maintainers, a budget or a succession plan.
This form creates resilience and fragility at the same time. The code can be downloaded, inspected, modified and run without renewing a licence. Operators can maintain local modules after a vendor or consultant loses interest in a device. The project does not automatically stop because of a single commercial decision to end a subscription product.
Open availability, however, does not create review capacity. Device modules need updates. Security problems require diagnosis and releases. Documentation and build systems age. A small number of people may hold knowledge on which thousands of installations depend without those installations being visible to the project or contributing resources upstream.
Downstream packages can help by adapting RANCID to operating systems and distributing fixes. They can also introduce delay or divergence. A packaged release may lag behind the reference release. Local patches may never return upstream. An organisation may believe it is ‘using RANCID’ while running a branch whose behaviour differs materially.
Most of the economics sit outside the project. Users pay for the collector host, storage, backups and engineering time. Consultants may earn income from deployment or support. The project creates value by accelerating investigation and preserving configurations, but that value does not appear as audited project revenue. A small maintenance burden may support enormous downstream assets without a proportionate funding mechanism.
Sustainability should therefore be watched through releases, security responsiveness, contributor activity, documentation and the health of the reference distribution. Large users can reduce risk by contributing fixes, test output, funding or maintainership instead of treating the project as a static tool. They should also preserve an exit plan: the repository format is portable, but local collection logic and credentials may not be.
The absence of a formal institution or dominant vendor is not necessarily a defect. It does mean that no central body can guarantee a roadmap. Organisations that depend on RANCID must decide how much responsibility to absorb internally and which external relationships are trustworthy enough to support it.
Migration should preserve the evidence, not merely replace the collector
When organisations move from RANCID to Oxidized, a commercial manager or a controller-based platform, the obvious task is to collect current configurations in the new system. The harder task is to preserve the meaning of the historical archive. Years of diffs may matter for audit, litigation, incident review or reconstructing why an old design exists.
A migration plan should retain repository history, timestamps, device identity and access controls. If file or host names change, a mapping is needed so old and new records can be compared. Secret-retention policy should be reviewed before history is copied into a new platform. Data protected in local Git may become more widely distributed after it is moved into a web application.
Collection equivalence also needs testing. The new tool may run different commands or normalise output differently. A sound migration may appear to change every line simply because formatting changed. Conversely, a supposedly equivalent model may omit commands that RANCID collected. Parallel runs provide evidence of coverage, recency and failure behaviour before the old collector is retired.
Credentials should not be copied automatically. Migration is an opportunity to reduce privileges, replace shared secrets, adopt stronger SSH algorithms and segment devices. Legacy equipment that cannot meet the new policy may need an isolated collector or an accelerated retirement plan.
The old repository should not remain connected indefinitely without an owner. If retained, it needs backups, security updates and access review. If archived, the organisation must know how to read and verify it. A compressed folder that nobody can interpret is not preserved evidence.
This migration discipline reinforces RANCID’s larger lesson. The durable asset is not the script or interface alone, but a trustworthy sequence of observations and knowledge of how they were produced. Replacing the collector while discarding provenance can make a modern system less useful than the older system it displaced.
RANCID’s use of plain text and version control helps because the data is not locked in a proprietary store. Portability, however, is only a possibility. It becomes real when the organisation documents modules, filters, schedules, device mappings and the limits of the record.
Configuration text is not network behaviour
A router can have a configuration that looks correct and still behave unexpectedly. Routes depend on neighbour state, received advertisements, timers, hardware resources, software defects and policies applied elsewhere. An access list may exist in the text but be attached to the wrong interface. A route map may be correct in isolation yet match data that changed outside the device. RANCID preserves an important layer, not the entire forwarding system.
This limit matters during diagnosis. A diff close in time to an incident is evidence worth investigating, but temporal proximity does not prove cause. Engineers should compare operational state: routing tables, adjacency state, interface counters, logs and telemetry. They should ask whether the changed command was active, whether its effect propagated and whether another system produced the same symptom.
The reverse also occurs. Behaviour can change without a configuration diff. A link fails. A neighbour announces a different route. A certificate expires. A hardware table fills. A process restarts and selects a new path under unchanged policy. Those events require monitoring or telemetry. RANCID should not be judged for failing to record state it was not designed to collect.
Some vendor modules include operational commands alongside configuration, and that can help. The choice should be documented because it changes the meaning of the archive and its noise profile. A routing-table snapshot may be large and volatile. Saving it periodically can support comparison while consuming space and producing diffs that obscure configuration changes.
Structured state models may improve reasoning, but they require vendor support and precise semantics. Text remains useful because it is close to what an engineer sees and can be inspected with ordinary tools. The strongest architecture uses both where possible: structured telemetry for current behaviour, configuration snapshots for the policy reported by the device, and intent systems for the approved design.
This separation protects against a common analytical error. A configuration archive does not prove compliance merely because files exist, and a live network does not prove configuration quality merely because traffic flows. Evidence from different layers has to be compared. RANCID earns its place by making one layer durable enough to participate in that comparison.
Audit value depends on provenance, retention and the ability to interpret the collector
Configuration history can support internal oversight, external audit and incident review, but the repository is not automatically an audit system. Auditors and investigators need to know which devices were in scope, how often they were collected, which commands ran, which fields were filtered and how access to the archive was controlled.
Provenance starts with the collector configuration.router.db, group definitions, login rules and vendor modules define the evidence. These files should be versioned and reviewed. A filter change can alter every subsequent snapshot. A schedule change can widen observation gaps. A credential change can silently remove part of the fleet.
Time is another dependency. Repository timestamps, device clocks, ticket records and identity logs must be aligned well enough to reconstruct a sequence. Commit time is not necessarily network-change time. Investigators should preserve that distinction rather than create false precision.
Retention needs a clear rule. Keeping every configuration forever may expose old secrets or personal or customer information. A policy that is too short may delete the only record explaining an old routing policy. Different classes of device or data may need different periods. Legal and regulatory obligations vary by organisation and jurisdiction.
Integrity controls can strengthen the record. Remote mirrors, restricted append-only backups, signed commits or external timestamping may make unauthorised alteration harder. None helps if keys, copies and the collector share one compromised administrator or storage system. Independence should match the intended threat.
Audit also needs negative evidence. The organisation should report failed collections, missing devices and periods when the archive was unreliable. Hiding those gaps turns a partial record into a misleading one. A clean sequence of commits does not cover a device the collector could not reach.
The central question is whether another qualified person can reproduce the meaning of the record after the original administrator leaves. If modules, filters and schedules are undocumented, the repository may preserve the text while losing its interpretation. RANCID’s simplicity helps, but governance is what turns it into evidence that can be relied upon.
Legacy devices make narrow compatibility a continuing infrastructure need
Network hardware often remains in service longer than the management model under which it was bought. A switch may continue forwarding reliably after its vendor moves to a controller, a different licensing model or another API. Replacement may require capital, an outage window and changes to dependent systems. Operators therefore maintain mixed fleets in which newer devices support structured telemetry while older ones expose only CLI and SNMP.
RANCID fits this reality because its basic requirement is limited: a reachable management session and a module that extracts useful text. It can preserve history for devices that no longer receive attention from newer platforms. That capability is valuable in universities, utilities, operator edge networks and other environments where infrastructure ages at different rates.
The benefit should not become an excuse for endless technical debt. Legacy access may require obsolete ciphers, shared passwords or Telnet. Vendor software may contain unpatched vulnerabilities. Spare parts and documentation disappear. The collector may keep the device manageable enough to delay retirement, while also recording evidence that supports a safer migration.
Organisations should classify compatibility exceptions. An old device can be isolated behind a dedicated collector and a separate management path. Credentials can be restricted. The repository can show whether its configuration changes at all. Replacement priority should reflect exposure and business criticality, not age alone.
This approach separates preservation from endorsement. RANCID’s ability to collect an old platform does not mean that the platform remains safe or strategically desirable. It means the organisation can retain visibility while deciding how and when to remove it.
That is why RANCID’s global impact cannot be measured through one service map. The software runs inside independently managed networks, often because those networks contain equipment that cannot be handed to a centrally managed platform. Its deployment is encoded in local repositories, package installations and scripts that upstream maintainers cannot see.
This invisibility complicates sustainability but confirms the project’s purpose. Network infrastructure is full of assets whose operational life exceeds the commercial life of their management tools. A simple collector can bridge the gap, provided it is used as a temporary control around known constraints, not as permission to forget them.
A narrow tool can outlive several waves of network management
The reference home of the RANCID project is Shrubbery Networks. At the research cut-off, the current site listed release 3.14, while the public archive dates the 3.14 series to 2025. Mirrors and downstream packages exist, but the reference site should be used for release and governance claims unless the project says otherwise.
The project does not publish an audited installation count, a budget, a complete maintainer count or a comprehensive device-support matrix. Its size is therefore difficult to measure. Longevity and package availability show continuing relevance, but they do not prove market share. Many deployments may be old, locally modified or invisible to upstream maintainers.
This ambiguity is common in small infrastructure projects. Software may be deeply embedded without generating a clear commercial record. Maintainer work may be voluntary, employer-funded or supported by consulting. Users benefit from shorter incidents and preserved evidence, but that value is not recorded as project revenue.
Sustainability depends on succession and compatibility work. New device software changes prompts and output. Old devices need legacy support. Security expectations change. Version-control systems and operating-system dependencies also evolve. A narrow tool can remain stable, but stability itself requires review and releases.
RANCID’s scope protects the project from some market pressures. It does not need to become a complete observability platform. It can continue collecting text as long as devices expose text worth collecting. The risk is that it becomes easy to ignore until a security or compatibility problem appears.
The strongest case for continuation is not nostalgia. It is the existence of heterogeneous, long-lived and incompletely automated networks. Those conditions are unlikely to disappear quickly. A tool that records evidence across them remains useful even if its interface looks old.
The text diff matters because it is bounded, inspectable evidence
RANCID’s central idea has endured because configuration text is close to the operational mechanism in many networks. An engineer can read a diff, search it with standard tools and retain it without a proprietary store. The evidence remains portable and understandable after the original monitoring platform changes.
Its limits should be stated just as strongly. The archive is periodic, not continuous. It records selected commands, not the whole device. Normalisation may remove context. A commit identifies the collection process, not the human actor. Credentials and repositories create management-plane risk. The file is not desired state, and restoring it blindly may be unsafe.
Those limits keep the tool honest. RANCID does not need to claim that snapshots are executable intent. It can complement GitOps because it records the device’s answer after automation. It complements LibreNMS by adding configuration context to symptoms. It complements commercial managers by retaining an independent repository.
The observable test is whether the archive improves a real investigation. Can the team identify the last successful collection, compare the relevant lines, connect the change to another record and recover without exposing credentials or pushing stale text? Can it show that the repository itself was not altered? Can it distinguish no diff because the configuration was stable from no diff because collection failed?
If the answers are yes, RANCID is more than an old script; it is a small evidence system embedded in network operations. If they are no, version control may be presenting a convincing history of the wrong thing.
The project’s lasting lesson is that control and evidence should not be assumed to be the same. A controller says what should happen. The device reports what it believes is configured. A monitoring system shows what selected signals did. A text diff preserves part of the disagreement. Networks become easier to govern when these records can be compared rather than forced into one story.
The final discipline is to preserve uncertainty in the record. A clean diff can prove that selected text changed between two successful collections. It cannot prove the full command sequence, the operator’s motive or the causal path to an outage. Those conclusions need other logs, interviews and tests. RANCID is most credible when users resist asking it to prove more than it collected.
That discipline is also what makes the system readable after decades. Its files can be opened without a special client, the history can be mirrored and the modules can be inspected. The architecture does not make the evidence neutral; filters, schedules and access shape it. But it keeps those choices close enough to the surface for an operator to challenge their assumptions. In a market tending towards ever larger management platforms, that inspectability is a material form of control.
It also provides an exit path. If the project, package or preferred integration changes, an organisation can retain the plain text and version history, provided it documented how the data was collected. Portability does not remove the work of migration, but it prevents the evidence from disappearing with one vendor account or proprietary data model. In long-lived networks, the ability to carry yesterday’s record into tomorrow’s tool may be as valuable as any new automation feature.
The archive then becomes institutional memory, not an appendage to one collector. Its value depends on continuing access, interpretable provenance and people who know where its limits begin. Those are governance choices, not software defaults, and they should be tested before an emergency actually reaches the network.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance