
Summary
draft-mo-cats-agent-selection-mapping-00says an AI-agent step should first exclude candidates that cannot satisfy capability, locality, tenancy, memory, context-window or budget constraints; only eligible instances may then be ranked across forwarding, computing and storage.- State affinity is not a permanent right to keep a session. A controller has to compare transfer and recomputation cost over the remaining horizon, apply freshness and stability rules, and preserve separate evidence for selection, commitment, handoff, execution and outcome.
The attractive mistake is to treat placement as a race between numbers. One instance is closer. Another has a shorter queue. A third already holds the key-value cache. If all three facts are poured into one score, the highest value appears to settle the question.
That is exactly the shortcut the new Internet-Draft rejects. The document was posted on 30 September 2026 as an individual Informational work item discussed on the CATS list. It is not an RFC, an adopted CATS working-group specification, an encoding or evidence of a deployed scheduler. Its useful contribution is narrower: it describes the information and decision boundaries that a Computing-Aware Traffic Steering system would need if the unit of work were a long-running agent session rather than a stateless request.
An agent session changes while it runs. A later step can require a different model capability, discover a new tool endpoint or accumulate a context that no longer fits beside the model weights. It may pause while a tool operates, then wake after the cache that justified its placement has been evicted. Its cost distribution can be heavy-tailed: a mean that looks healthy says little about the slowest tool call that determines a turn's completion time.
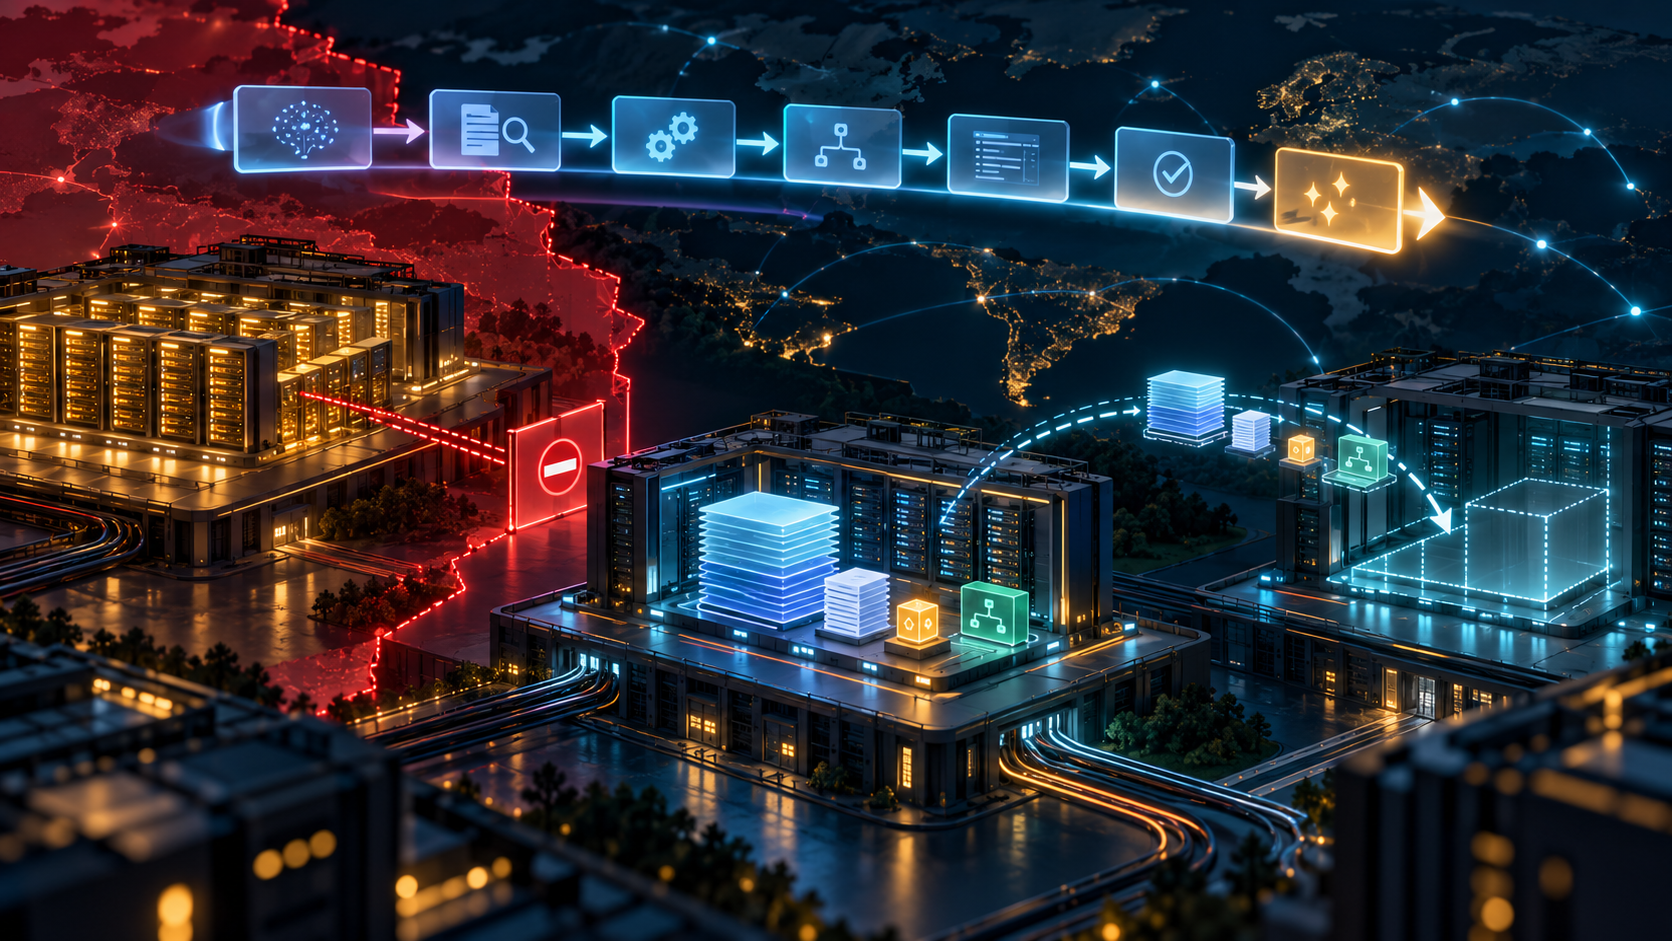
The draft turns those conditions into a three-layer mapping. The first layer is a descriptor of the next step: service and capability, working-set elements, constraints, preferences, remaining budget, tail objective, acceptable degradation and freshness tolerance. The second is a resource view of each candidate and its paths across forwarding, computing and storage. The third is the selection context: where the session is in its life, what remains of its horizon and budget, which decisions are committed, and how large and durable an improvement must be before movement is allowed.
The first control principle is filter before rank. A capability tier is not a mild preference if the step cannot run below it. A location rule is not a cost premium if moving the data would be forbidden. An unknown answer about state presence cannot satisfy a constraint merely because the candidate advertises excellent latency. The draft requires absence, staleness and unknown provenance to remain unknown. It refuses the managerial convenience of converting every limit into a negotiable scalar.
This sharply separates the proposal from the existing debate about normalized CATS metrics. A well-defined common score can help compare candidates that are already eligible. It still cannot declare an ineligible candidate eligible. Nor can it explain whether eight points of apparent improvement repay three seconds of state transfer and the risk of disturbing work already in flight.
The storage dimension makes the second control principle visible: state is not one object. Model-side context may be large but reconstructible. Retrieved passages may be cheap to fetch again. A tool result may be small yet impossible to recreate because the tool changed the outside world. Plan and scratch state can be tiny but costly to rebuild because earlier reasoning steps would have to run again. Longer-term memory may be small and read-mostly while subject to strict locality.
Each element therefore needs its own presence, residency tier, size, age, retention, retrieval cost, recomputation cost and governance rule. A scheduler that asks only whether “the session state” is present destroys the very distinctions that determine whether movement is lawful and economical.
The costs also have different clocks. Transfer is paid in bulk when the selected instance changes. Storage is evaluated per element and per step. Compute is paid per step. The draft's illustrative relation chooses the cheaper of transfer time and recomputation time for absent state, then tests the result against tail and budget limits. Those equations are not benchmarks. Their value lies in forcing the controller to state units and alternatives instead of hiding them inside an unexplained suitability number.
This means state affinity is evidence, not authority. An instance that holds the full working set deserves a preference because reuse can avoid delay and cost. It does not acquire a permanent claim on the session. If another candidate can receive the necessary state in three seconds while recomputation would take two minutes, and if the remaining horizon repays that move, transfer may be rational. Conversely, spare capacity at the new site is not a sufficient reason to leave when rebuilding context would consume the remaining budget.
The draft limits how often that question may be reopened. Decisions occur at explicit points: admission, the start of a turn or step, wake-up after a pause, expiry of a metric's freshness bound, sustained improvement, risk to a constraint, a tail event, a budget threshold and session close. A stream of telemetry updates is not supposed to become a stream of migrations.
Ordinary movement must pass a stability window: minimum time since the last move, minimum improvement, and a gain that survives the transfer or reconstruction cost over the remaining look-ahead horizon. Work already in flight is not moved for a preference. A violated constraint, or a tail event that permitted degradation cannot absorb, has a different urgency.
When movement is justified, the sequence is reservation, transfer or reconstruction, then commitment. A target that cannot make the required set usable must refuse or abort. The source remains usable. Repeated reservation, commitment and transfer exchanges must be idempotent. That sequence is the difference between a reversible handoff and a leap based on an advertisement.
The same evidentiary discipline applies to failure. The fallback ladder first relaxes a preference while keeping every constraint, then uses only degradation the descriptor already permits, then moves eligible work, then fails the step with reasons, and finally fails, defers or seeks human approval for the session. Silent retry until the budget disappears is not recovery.
Five artifacts keep the control surface auditable: the step descriptor, the resource-view snapshot, the decision record, the commitment and the handoff record. Their separation is not paperwork. They have different authors and lifetimes. A resource advertisement is not a reservation. A selection record is not proof that steering was installed. A committed handoff is not evidence that the model produced a useful result.
That last boundary matters because the resource view can be dishonest. An instance that exaggerates capability or claims to hold valuable state can attract the sessions whose state it wants to observe. Every quantity therefore needs an observation time, a freshness bound, a source and a confidence class. Reuse keys need tenant scope; aggregation and short retention reduce the privacy revealed by working-set structure, tool choices and locality constraints.
This is also where Heng Lu's reality-layer discipline becomes operational. The descriptor describes intent. The snapshot describes observed supply. Eligibility records the limits that were tested. Ranking records a policy choice. A commitment authorizes a bounded placement. A handoff records attempted state movement. Execution and outcome arrive later, from different observers. Collapsing them into a green “selected” badge does not simplify reality. It erases the point at which responsibility can be assigned.
Sources
- https://datatracker.ietf.org/doc/charter-ietf-cats/
- https://datatracker.ietf.org/doc/draft-ietf-cats-data-model/
- https://datatracker.ietf.org/doc/draft-ietf-cats-framework/
- https://datatracker.ietf.org/doc/draft-ietf-cats-metric-definition/
- https://datatracker.ietf.org/doc/draft-ietf-cats-oam-fw/
- https://datatracker.ietf.org/doc/draft-ietf-cats-usecases-requirements/
- https://datatracker.ietf.org/doc/draft-mo-cats-agent-selection-mapping/
- https://datatracker.ietf.org/doc/draft-mo-cats-agent-selection-mapping/history/
- https://datatracker.ietf.org/doc/draft-mo-cats-agent-service-characteristics/
- https://datatracker.ietf.org/doc/draft-pang-cats-fallback-decision-framework/
- https://datatracker.ietf.org/doc/draft-zhu-cats-metric-semantics/
- https://heng.lu/minimum-initial-specification-localized-future-decision-voluntary-adoption-internet-coordination-system/
- https://heng.lu/on-reality-layers-symbolic-power-and-why-clarity-feels-so-hostile/
- https://heng.lu/running-code-primary-the-patch-needed-to-preserve-the-internet-original-design/
- https://www.ietf.org/archive/id/draft-ietf-cats-framework-24.txt
- https://www.ietf.org/archive/id/draft-ietf-cats-metric-definition-11.txt
- https://www.ietf.org/archive/id/draft-mo-cats-agent-selection-mapping-00.txt
- https://www.ietf.org/archive/id/draft-mo-cats-agent-service-characteristics-00.txt
- https://www.rfc-editor.org/rfc/rfc8174.txt
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance