
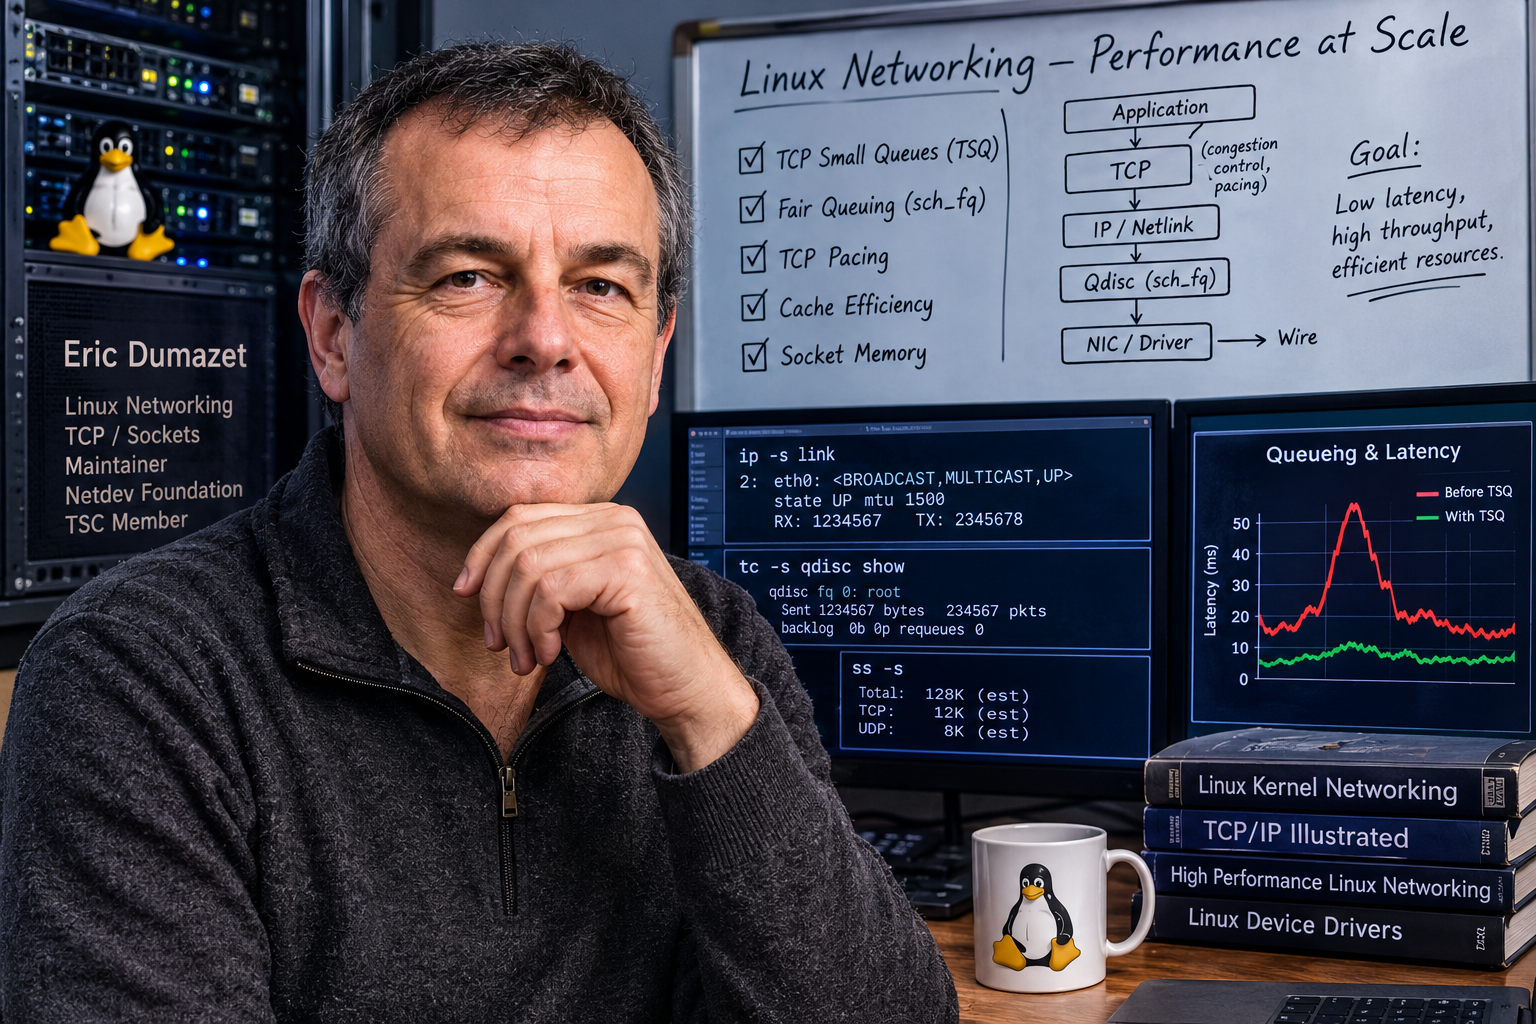
Summary
- Eric Dumazet currently appears as a maintainer of general networking, TCP and sockets in Linux and sits on the Technical Steering Committee of the Netdev Foundation. These roles are shared with other maintainers and reviewers: they represent strong integration responsibility, not exclusive authority over the kernel network.
- His clearest named contribution is TCP Small Queues, introduced in 2012 to prevent a single TCP flow from placing too much data in queues below the transport layer. By linking local socket credit to packet completion, TSQ reduced sender latency and memory pressure without eliminating all queues along the path.
- Later work on
sch_fqand internal pacing turned transmission timing into explicit control. Fair queueing separates flows; pacing spreads packets over time. These mechanisms support several congestion controls, including environments that use BBR, but BBR has its own authorship and evolution. - Dumazet's more recent work relates structure layout, cache-line traffic and per-socket state to efficiency in large fleets. The lesson is that Linux networking is also an accounting exercise for CPU, memory, queue depth and time. The economic impact can be material, but public data does not allow an exact financial value, nor a promise of the same gain on every system.
A fast server can still waste time behind its own packets
The story begins inside a transmit queue. The application wrote data, TCP concluded it could send more and the kernel passed those bytes to lower layers. From the application's point of view they appear to have left; in practice they may still be waiting on the same machine.
High throughput hides delay. An interactive request sits behind a large transfer, buffers hold memory and the idea of data “in flight” no longer matches what is merely queued locally. TCP Small Queues changed that relationship by limiting how much a socket can place below TCP and by returning send capacity when hardware actually completes work.
The public record is rich in engineering and deliberately limited in biography
The strongest evidence comes from the kernel itself:MAINTAINERS, patch discussions, documentation, talks and years of public review. These support his current responsibility for general networking, TCP and sockets, his involvement in the Netdev Foundation and a visible affiliation to Google through the maintainer email address.
There is no complete authorised biography, no verified current corporate title, no total patch census and no exact breakdown of his time. Filling those gaps with plausible details would reduce accuracy. The profile focuses on observable mechanisms and decisions. Dumazet emerges as an engineer with technical responsibility whose work only becomes infrastructure after review, modification, testing and deployment by others.
Maintainer status places him close to decisions, not above the community
On 4 August 2026, Linux records listed him under general networking, TCP and sockets. A maintainer can ask for an interface redesign, reject an excessive maintenance cost, apply accepted changes and represent a subsystem towards mainline.
The same source shows shared authority. David S. Miller, Jakub Kicinski and Paolo Abeni appear under general networking; Neal Cardwell shares TCP, and specialised reviewers act according to the patch. Architectures, drivers, security, testing, stable and the final kernel process impose other limits. Dumazet's influence is large precisely because it operates inside that distributed system.
Linux became economic infrastructure when the number of connections grew
On a small machine, a few extra bytes per socket or an additional cache miss may go unnoticed. On a server with hundreds of thousands of connections, the cost multiplies until it competes with the application itself for CPU, memory and power.
“Server economics” is not a public savings figure. It is the translation of technical overhead into density, remaining CPU capacity, memory reserved for networking and delay caused by local queues. Distributions and operators choose kernel, qdisc, congestion algorithm and NIC. Dumazet does not control those choices; he improves the common starting point.
TCP's familiar function hides a dense system of accounting
TCP is presented as a reliable byte stream, but it must decide how much may remain outstanding, when to retransmit, how to charge memory, order packets and divide CPU and queues among thousands of sockets.
An implementation can be correct and still perform badly: large local backlog, bursts, locks or structures that waste cache. The common thread in Dumazet's work is accounting. Bytes are assigned to the socket, completions return credit, send times are calculated and hot fields are separated from cold ones. The goal is to keep the link productive without creating a second hidden network inside the host.
Before TCP Small Queues, the sender could create a backlog it no longer controlled
Before TSQ, TCP could hand too much traffic to the qdisc and driver. The congestion window could be correct while a local queue still held packets below the transport. The application could not retrieve them when a more urgent flow appeared.
This weakened feedback: TCP observed acknowledgements from the path, but some of the data had not even left the host. It also consumed memory, especially when many flows did the same. Throughput needed to be preserved without allowing each socket to treat the lower layers as unlimited storage.
The 2012 TSQ series gave the socket a local queue budget
The 2012 patches limited, per socket, the amount of data queued below TCP. When local credit ran out, the socket stopped; when packets completed, it regained permission to send.
The idea was small: account for local bytes and use completion as a progress signal. Control returned to the transport that understood the flow. It was no longer necessary to deposit a large batch at once to keep the link busy. Applications that had never heard of TSQ inherited more disciplined behaviour.
Packet completion became a useful signal inside the host
Completion might have seemed like mere cleanup. TSQ used it as information: the lower layer made progress, so the socket can receive new credit.
That local feedback complements remote acknowledgements. One describes progress below TCP; the other, progress along the path. qdisc, driver and NIC statistics show other points. No single signal solves everything. TSQ uses one of them to limit local excess without replacing end-to-end congestion control.
TSQ reduced one source of bufferbloat, not every queue on the path
TSQ did not eliminate bufferbloat. It limits the sender's local backlog. Queues remain in qdisc, driver, NIC, access, routers, switches and receiver.
The precise claim is more useful: the mechanism reduces a socket's ability to create an over-large hidden queue. It can lower latency and memory use and bring TCP state closer to device progress. It does not replace active queue management, proper configuration or congestion control.
Limits, offloads and workloads determine how much TSQ helps
The effect depends on the local limit, packet size, qdisc, device queues, segmentation and flow mix. An interactive service and bulk replication do not respond the same way.
The implementation has also evolved since 2012. Other contributors adjusted integration and fixed cases. It is correct to credit Dumazet for the origin without presenting the current mechanism as a frozen piece that is exclusively his.
sch_fqseparated flows and put time inside the scheduler
In 2013, Dumazet published thesch_fqscheduler. It keeps per-flow state and a time-ordered structure to release packets according to their send instant. New flows can be served early; paced flows wait their moment.
The design prevents one large transfer from monopolising the local queue and gives TCP a place to perform pacing. It does not guarantee equality between applications; it provides a more disciplined service policy and a practical interface for send timestamps.
Fair queueing is a policy choice, not a promise of equal results
“Fair” does not mean every application will see the same performance. Packet size, path, receiver, congestion, offloads and number of connections still change the outcome.
The very definition of a flow is policy. One application can open many connections and another only one.sch_fqreduces local domination, but it does not decide fairness between users or companies. For the operator it is an arbitration tool, not a universal guarantee.
Pacing turns an estimated rate into a sequence of send times
An algorithm can choose the correct rate and still release it as a burst. The average looks good, but the queue suffers a spike.
Pacing spreads packets over time. It can stabilise queues, improve coexistence and express the congestion model more accurately. Implementation depends on timestamps, timers, qdisc, segmentation and NIC. A software rate becomes real only when it turns into physical times on the link.
Pacing and congestion control solve different parts
Congestion control decides how much of the path to use; pacing decides when the permitted data leaves. A good model can be destroyed by bursts, and perfect pacing can execute the wrong rate.
Dumazet's infrastructure allows several algorithms to express rate over time. Authorship of each model belongs to its own designers.
BBR uses pacing, but has its own authorship and history
BBR is often associated with Dumazet because it depends on pacing and emerged in a Google environment. That does not make him its sole inventor. The algorithm has distinct authors, model and versions.
Dumazet's contribution is foundational: queues, pacing, instrumentation and sockets make other controls viable. This formulation recognises his importance and preserves credit for Neal Cardwell and other congestion engineers.
TSO saves CPU and can recreate the burst that pacing tried to avoid
TCP Segmentation Offload allows a large segment to be handed to the NIC, which splits it afterwards. This reduces per-packet cost, but inserts hardware between the timing decision and actual emission.
If a large block leaves at once, the NIC can create a burst. TSQ, qdisc, TSO, driver and hardware must be treated as a system. A CPU saving can worsen latency if there is no coordination.
Quantum, timestamps and NIC behaviour must describe the same reality
The kernel works with quanta, timer resolution, timestamps, offload units and physical queues. A large quantum recreates bursts; a small one consumes CPU; a NIC with different granularity changes the output.
That is why qdisc is part of capacity planning. Developers need to measure the full path, and benchmarks that mention only congestion control or link speed omit much of the mechanics.
TCP internal pacing reduced dependence on a specific qdisc
In 2017, Dumazet published internal pacing in TCP. The transport gained a greater ability to hold traffic according to rate and timers, without depending entirely on a specific discipline.
The qdisc remained relevant for ordering and policy. The logic moved closer to the subsystem that carries intent, but final emission stayed distributed across TCP, scheduler, driver and NIC. It was evolution by layers, not a complete replacement.
Queueing discipline remains an operational decision with service effects
Linux offers qdiscs for different goals.sch_fqfavours pacing; FQ-CoDel combines per-flow separation and active queue management. They are not identical.
Defaults vary by distribution and environment. Cloud images, appliances and container hosts may choose differently, and offload can move execution. Upstream provides the mechanism; the operator decides whether it truly shapes the service.
A few bytes per socket become a fleet constraint
Each connection keeps sequences, timers, congestion state, queues and counters. At scale every byte multiplies and every frequent field occupies cache.
Less memory per socket can increase density; better layout reduces misses and coherence traffic. This is the strongest bridge to server economics, but it does not allow a universal financial gain or a personal valuation of the work.
A cache line becomes infrastructure when it is touched on every packet
The CPU moves whole lines. Hot data next to cold fields makes useless bytes circulate; two CPUs altering the same line generate coherence traffic even when touching different values.
Dumazet's recent work adopts that physical reading. Separating hot and cold fields reduces memory traffic that grows with packets and sockets. The gain depends on processor and load; one production profile cannot become universal law.
The 2024 structure work shows a mature phase of performance engineering
The 2024 presentation began with profiles: which fields are hot, which lines move and which structures dominate memory. Tools can suggest rearrangements, but they do not replace review of alignment, locking, compatibility and maintenance.
In mature infrastructure, a large gain can come from removing a cache miss or moving a field, not from launching a new algorithm. It is less visible, yet decisive at scale.
Hyperscale profiles are strong evidence and incomplete public science
Large operators see volumes and hardware that are hard to reproduce. They can detect costs absent from microbenchmarks. Dumazet's Google affiliation places him in that context.
Part of the workloads and data remains private. A talk can show method and direction without exposing all inputs. This requires qualification, not dismissal. The best outcome is to convert more private observations into public tests and workloads.
Locks and receive queues are part of the same resource story
Although the focus is on transmission, Dumazet's trajectory also covers sockets and the receive path. Incoming packets require polling, allocation, classification, queues and delivery between CPUs. At high rates, locks and shared state become cost.
Linux reduces this by moving work, batching operations and lowering contention. The principle is the same: use enough coordination for correctness without letting the accounting consume the application.
Batching increases throughput and changes latency and fairness
Grouping packets or completions amortises locks, calls and cache. NAPI, drivers and offloads depend on it.
The batch waits to form and may arrive as a burst. Large batches increase efficiency and waiting. TSQ, fair queueing and pacing do not fight batching; they impose limits to preserve feedback and latency.
TCP performance emerges from layers that can cancel each other out
The algorithm defines intent; TCP creates packets; TSQ limits backlog; qdisc orders; TSO groups; the driver maps; the NIC transmits; the network adds queues and loss.
Precise pacing can be undone by coarse segmentation; a low-latency qdisc by excessive enqueue; compact layout by a new lock. Dumazet works at those seams and improves the installed path instead of ignoring it.
Public review turns a local optimisation into shared infrastructure
An improvement begins as a claim of less latency, memory or CPU. To enter Linux, it faces netdev: methodology, generic abstraction, rare architectures, tests and future cost.
The maintainer can split the series, reject a vendor interface or defer a patch. It is slower than a private change and more sustainable. Dumazet's authority includes evaluating not only today's result but tomorrow's maintenance.
netandnet-nextseparate urgent repair from future development
Fixes normally go tonet; features go tonet-next. This avoids mixing urgent maintenance with next-version refactoring.
The boundary requires judgement. A fix can change behaviour; a feature can reveal an old bug. Maintainers split series to make risk explicit and prevent a commercial calendar from replacing technical readiness.
Review, rejection and redesign do not appear in commit counts
Commits measure visible authorship, but not the sentence that forces a redesign nor the rejection that avoids years of cost. Applying a patch means taking on integration, not inventing the idea.
The profile combines attributable mechanisms and stewardship. TSQ,sch_fq, pacing and layout are clear, but they do not summarise decades of review, nor turn every integrated patch into personal creation.
Testing reduces risk without representing every machine Linux will meet
Builds, selftests, KUnit, syzbot, laboratories and downstream testing detect regressions, but they do not cover every CPU, NIC, qdisc and workload.
A hyperscale improvement can harm a rare device. Experience, compatibility and rollback remain necessary. Tests strengthen governance; they do not eliminate judgement.
Stable backports require a second decision after mainline
A mainline patch does not automatically enter every stable tree. It must be a real, bounded and safe fix. Distributions decide again.
Performance changes may depend on code absent from an old branch. Impact arrives in stages: upstream, stable, distribution, cloud and configuration. No one controls the whole chain.
Current TCP and socket maintenance is deliberately shared
MAINTAINERSdivides the work between Dumazet, Neal Cardwell and other reviewers. This reduces dependence on one person and combines knowledge of congestion, sockets, drivers and testing.
Plurality requires clear ownership. Overlapping areas create gaps if everyone waits for someone else. Healthy succession spreads authority and preserves the reasons behind decisions.
The Netdev Foundation can fund without becoming merge authority
The foundation, under the Linux Foundation, supports CI, tooling, travel and research. Dumazet participates in the TSC. A grant does not guarantee a merge.
The distinction is healthy: deep maintenance costs money, but upstream legitimacy comes from public evidence. Funding should increase decision-making capacity, not buy an exception.
Google affiliation brings capacity without ownership of Linux TCP
The Google email proves affiliation, not a complete role. A hyperscaler can fund profiling, hardware and review that later benefits the whole ecosystem.
The asymmetry is that workloads and data are not fully public. Open review is the counterweight: the patch must be generic and acceptable outside Google. The company provides time and evidence; it does not own the stack.
Downstream operators decide whether the improvement changes the service
Distributions choose kernels; clouds, qdisc and congestion control; appliances, versions; manufacturers, capabilities; applications, traffic. There is no complete census of TSQ orsch_fquse.
A mechanism can be present and inactive, or active by default without being noticed. Dumazet's impact is broad and indirect: it changes the common set of options; each operator converts that into experience.
Userspace stacks compete for specialised workloads, not every Linux function
DPDK, VPP and custom stacks bypass parts of the kernel to gain high rates, at the cost of dedicated cores, huge pages and a separate operational model.
Linux integrates sockets, security, namespaces, observability and drivers. Dumazet's work lowers the cost of the general path without claiming it is ideal for everything. Bypass serves specific cases; Linux remains the broad base.
Linux remains the default because integration is worth more than raw speed
A stack needs to be fast, compatible, secure, observable and maintained. An isolated path may deliver more packets per second and higher operational cost.
A Linux application inherits TSQ, pacing and accounting through common sockets. That invisibility is a strength: the benefit remains even when the user does not know the author's name.
A faster host does not prove the network path improved
A smaller local queue does not fix congested access, a slow destination or a router with loss. TSQ and pacing govern the sender, not the entire path.
They can reduce one source of delay and make the flow more regular. They do not guarantee the application's result. End-to-end performance still depends on application, receiver, route and configuration.
One benchmark does not represent every server, NIC and workload
Packet size, connections, CPU, cache, NIC, offloads, qdisc, timers, kernel and load change the result. A Google profile can reveal real cost without predicting a percentage for another fleet.
Good communication preserves conditions. Dumazet's talks are attributed operational evidence; public tests and independent measurements are necessary to generalise.
Succession is a technical problem because part of the design lives in memory
Strange limits may exist because of an old NIC, an API still in use or a regression fixed years ago. The code does not always tell that story.
Veteran maintainers carry context. Documentation, tests, files and new reviewers turn private memory into institutional knowledge. Succession must preserve principles and allow adaptation to future hardware.
Hardware pacing and device memory may move the boundary again
Modern NICs programme packets, control queues and expose telemetry or local memory. They reduce CPU and shift behaviour to firmware.
Linux needs to express intent, observe the result and recover when models diverge. Driver APIs, timestamps and errors become as important as rate. The principles remain: feedback, limits on hidden queues and observability.
Cache economics can deliver more gains than new transport formulas
New algorithms will keep appearing, but the next material gain may come from a better layout, lock or batch. It has no flashy brand and benefits many applications.
The 2024 work shows a mature stack evaluated by physical costs. The question shifts from “which protocol wins?” to “how much machine does each connection consume?”.
Dumazet's lasting contribution is resource discipline, not heroic myth
An exaggerated version would make him the inventor of modern TCP and BBR; another would erase the individual in the community. The evidence allows precision.
Dumazet introduced TSQ, signed foundational work onsch_fq, developed internal pacing and showed the importance of layout. He also maintains critical areas within a shared system. His contribution is to treat packets and sockets as claims on time, memory, queue and CPU locality.
The final impact is dispersed through design, review, integration and operation. A commit is attributable; a denser fleet or an avoided failure is not. That difficulty does not license exaggeration or erasure: it shows that infrastructure value is born from a collective chain with identifiable individual decisions.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance