Summary
- Imagine a spotless audit of 100 signed receipts while one administrator's action never entered the book. Mikhail Sergeev's 23 October WEXP Coverage draft separates proof about those receipts from proof about the full set of actions. Its PostgreSQL example defines a testable book: committed appends in one closed epoch.
- The buyer's decision is plain: can the person who runs the log also approve the claim that nobody bypassed it? Coverage can expose that assumption and name its approving authority. The buyer then decides whether to rely on it.
The green tick's blind spot
Picture an internal investigation after a disputed administrative change. The log vendor presents every receipt it has, each with a valid signature. The dispute remains: did the administrator have a path that never produced a receipt? The green check on the visible records cannot answer. Mikhail Sergeev's WEXP Coverage draft, dated 23 October 2026, forces the investigation one step farther: name the actions that ought to have been captured, the receipts actually created, and the authority behind the claim that the first population is visible at all. This is a constructed situation, not a reported breach.
The investigator can verify every row in the exported log. The seal fixes the exported rows against later edits. The missing administrator action would still be missing. That is the draft's difficult demand: show how actions entered the book before anyone sealed it. Coverage becomes a set of claims tied to a named scope and a closing time. The person controlling the entry door becomes part of the result.
This is an individual Internet-Draft, identified by the IETF Datatracker as an active proposal without an RFC stream. Its value here is architectural: it shows precisely which assertions a buyer of an audit system would have to accept. It records neither an IETF decision nor a measured failure at an actual operator.
Five populations, one uncomfortable question
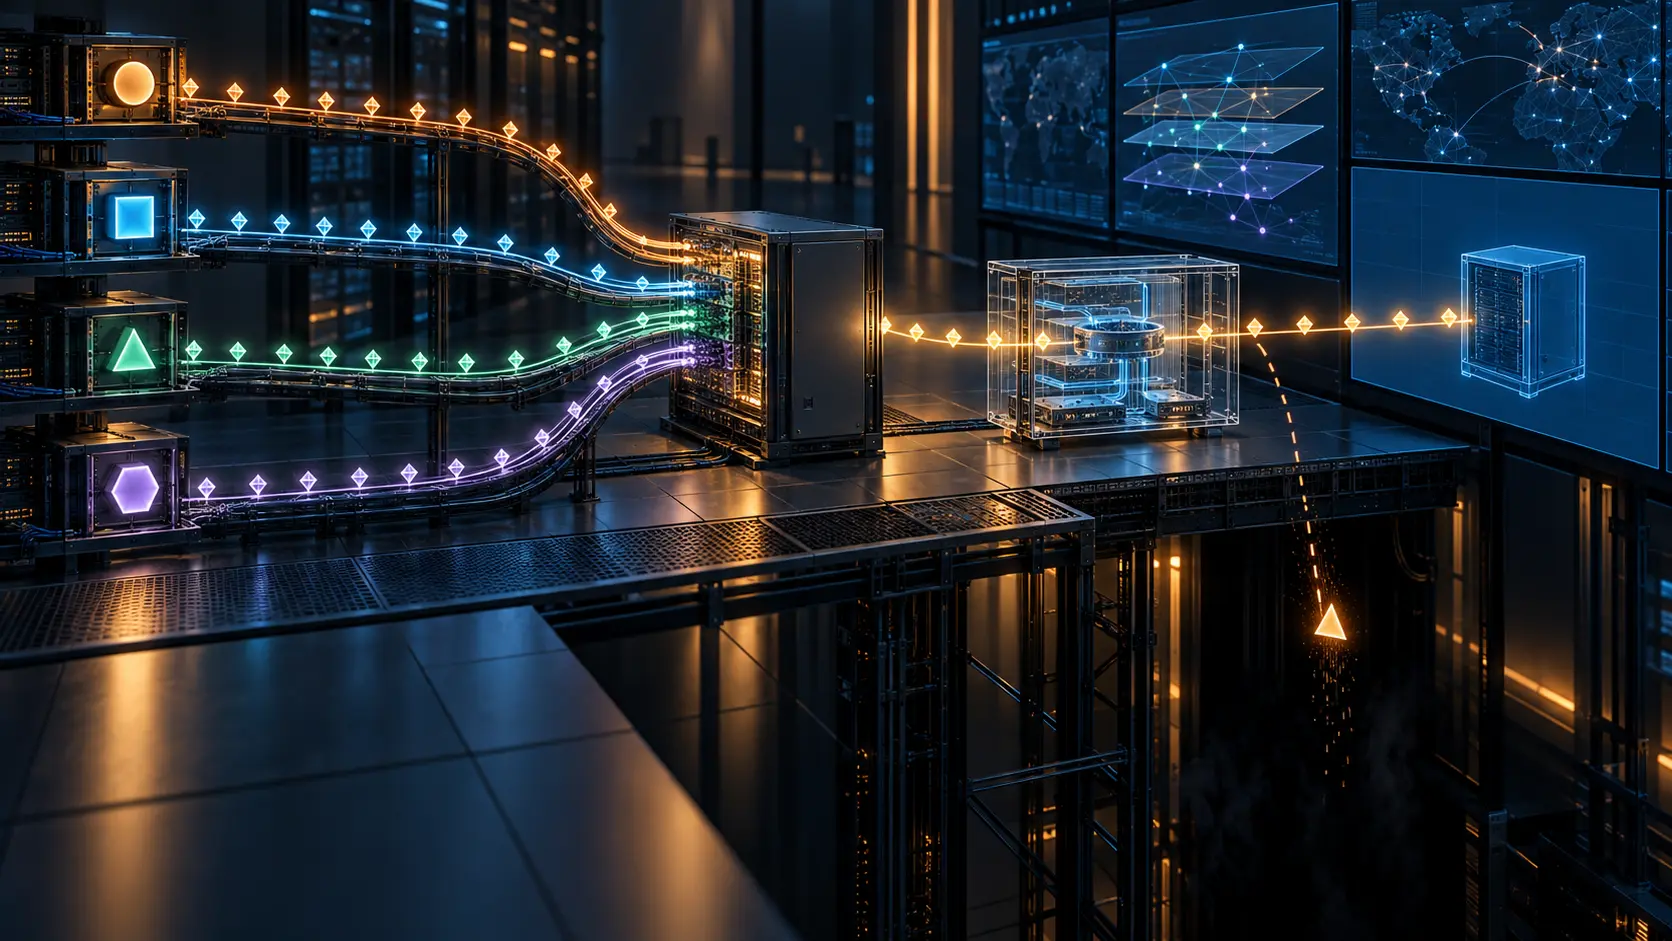
Follow one administrator action through the system. The action itself belongs to A. A final receipt, if created, belongs to C. If the intended recipient can retrieve it before the delivery deadline, it also appears in R. The evaluator receives copies of the receipt populations, Cv and Rv, and a source ledger view, S. This alphabet matters only because each step can fail separately. The source ledger does not arrive with proof that every action entered it; that is the claim the audit must test.
The distinctions matter before anyone reaches cryptography. A request can fail, then be retried. A database transaction can commit while its response is lost. A receipt can be finalized but never reach the intended recipient. A copied receipt can arrive twice. The draft's lifecycle rules require a deployment to say which of those events counts as an action, a receipt and a delivery. Otherwise an impressive total can be built from the wrong units.
Its proposed claim set makes those units explicit. creation-complete asks whether every actual action has a related final receipt. creation-sound asks whether each final receipt relates to an actual action. creation-exact requires a one-to-one match. There are separate claims for delivery, source coverage and correspondence between supplied views. empty-actions has its own name. Ten claim identifiers replace a single, elastic word: complete.
Suppose an auditor receives a signed receipt file and an apparently matching action export. A one-to-one comparison of those supplied files may succeed. That establishes correspondence of the files under the declared comparison rule. If the source export omitted a committed action, the files can agree beautifully while the coverage claim fails. The draft specifically bars a seal of an empty view from standing in for an unavailable source. It also distinguishes an empty source that was fully read from an empty array handed over after a failed query. The green tick has finally been asked what it actually checked.
The assumption with a name on it
Coverage cannot avoid premises. It can make them public to the relying party. In the draft, a premise may be checked, assumed, unknown or refuted. An assumed premise needs an identified policy authority, reason and scope. It cannot merely say, in longer words, that the audit is complete. A source-capture premise has to describe a property of the deployment: how actions enter the source, what paths can bypass it, and what controls make that story credible.
This is where governance enters the machine room. A controller may be able to change the source, issue a receipt outside it, restore a prior database state or present one branch of a fork. The draft says two matching seals or two organizations do not by themselves establish complete action capture or exclude a suppressed branch. Different keys are cheap; independent control is an institutional fact. A relying party that accepts a no-bypass assumption has made a trust decision about people and privileges, even if the result is computed deterministically afterward.
The draft's illustrative conflict case is revealing. A positive derivation rests on an accepted capture assumption. A separate, usable counterexample establishes an omitted action. The result must retain both and report the claim as not-established with conflict. Changing policy to hide the counterexample is forbidden by the proposed rules. The point is unusually concrete: the authority that approved an assumption cannot erase contrary evidence merely by changing the evaluator's settings.
What three seals can buy
Sergeev then chooses a deliberately tight example. In the draft's pg-ledger/0.2.0 profile, the action is a committed append to a named action ledger in a single-primary PostgreSQL 18 batch. That definition excludes a broader business effect. A payment shown as committed in this ledger, for example, would still need a separately specified link before anyone could claim that external funds moved. The profile's narrowness makes its own question answerable.
Every append and every seal locks the same epoch row. Three committed barriers close, in order, action admission, final receipt creation and recipient admission. Receipt finalization waits for the action seal; external admission waits for the creation seal. A complete snapshot after the barriers can supply action, receipt and inbox views. Sequence numbers and wall-clock timestamps alone are not commit-order proofs. Raw duplicate attempts and conflicting variants stay available for inspection; only authenticated, identical receipt occurrences can be collapsed as retries.
That is a serious attempt to give the word all an operational meaning. It also puts the limits in the open. The profile depends on correct database and host operation, intact storage, enforced role separation, no bypass or early external issuance, complete authenticated export, and stable keys and policy. A privileged administrator, a restore, a fork or an out-of-ledger issuance can defeat those premises. A seal cannot certify the hands that held the sealing machine.
The draft's constructed 100-action example sharpens the distinction. It imagines 99 valid per-action appraisals and one established missing receipt, under an exact closed population. The 99 appraisals remain valid for their own targets; they do not turn the population into 100 covered actions. Nor does a bare count of 99 prove the missing hundredth. The omission requires positive membership evidence for that action and a sufficiently exhaustive negative check for its receipt. The example is a logical test case, not a report of an incident.
A useful answer can be narrower than a verdict
The proposed evaluator can report a local fact even when a stronger claim remains open. A demonstrated mismatch between two supplied views can be recorded while completeness of the true populations is unresolved. A source query failure is reported as unavailable, not as proof that no actions happened. When support and refutation both survive, the result carries both. When neither survives, the result says which evidence or premise is missing. This design resists the executive-summary habit of turning an evidence gap into a red or green badge.
The WEXP Core companion draft appraises content claims about exact execution targets. Coverage addresses population claims. A credible appraisal for each target supplied to Core does not enumerate targets that never arrived. The distinction is the hinge of the article: a system can do an excellent job describing what it saw and still have no basis to claim that it saw everything.
Sources
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance