
Summary
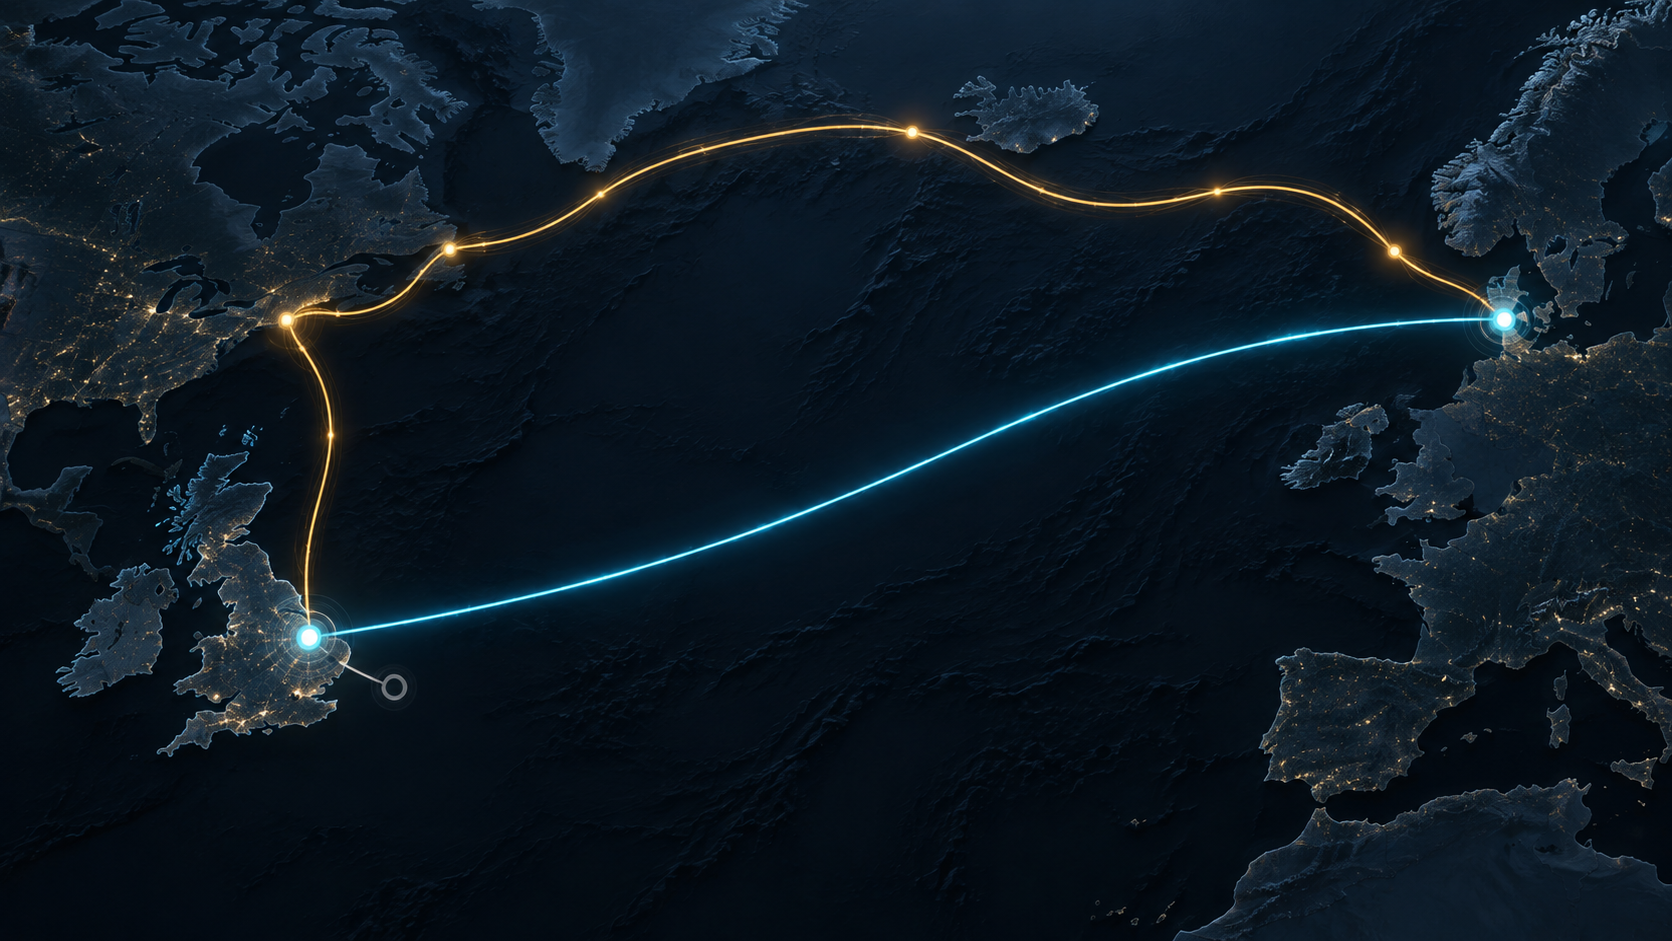
- Two posted paths toward a TDC loopback in Denmark took 175.604ms and 181.747ms after appearing to cross North America; a Colt control reached the same address in 22ms.
- Follow-up tests showed GTT reaching TDC from London in about 20ms, so the opening idea that GTT lacked a European path was wrong. The reporter later attributed the problem to an unnamed UK AS exporting its prefix only to Cogent while Cogent would not peer with TDC in Europe.
- TDC reportedly arranged a direct route to the UK AS, apparently at LINX. It fixed the reported problem, but the reporter said it was non-redundant and could send traffic back through North America during an outage.
The most useful line in this routing story is not the 175.604 milliseconds at the end of a traceroute. It is the 20 milliseconds in a later trace run from inside the network first suspected of causing the detour.
The first number made the geography look absurd. A path described as starting in London ran through named Cogent routers in Liverpool and Montreal, crossed to GTT in New York, and then returned to TDC in Denmark. A second sample, described as coming from NTT's London looking glass, showed Ashburn and Washington before reaching the same TDC loopback at 181.747ms. The control sample through Colt stayed in Europe and reached it in 22ms.
That was enough to identify a symptom. It was not enough to identify the decision that produced it.
The thread, posted to the RIPE Routing Working Group, gradually supplied the missing counterfactual. A contributor ran GTT's own looking glass toward the same address, 93.178.170.33. From London, the displayed path entered TDC directly and completed in roughly 20ms. From Amsterdam it took about 12ms; from Copenhagen, roughly 2–4ms. GTT plainly had a working European way into TDC for the tested address.
The original hypothesis — that GTT could reach TDC only, or preferentially, through North America — could no longer carry the explanation. The trace was real; the story attached to it was not yet complete.
Three paths, one diagnostic reversal
The thread began on 29 July 2026. Peter Keller described persistent latency between an end-user site in Cambridge and a destination hosted on TDC's AS3292 network in Denmark. The site's building-managed provider had changed its upstream international connectivity. Keller could not confirm the new supplier, but said the timing coincided with the problem.
The public traces targeted 93.178.170.33. Its reverse-DNS name identifies it as a TDC loopback, and RIPEstat currently places the address in 93.178.128.0/18 originated by AS3292. It should not be mistaken for the undisclosed application destination. The address was a stable target with which operators compared available paths toward TDC.
The comparison was stark. Cogent's displayed path reached 175.604ms after the RTT rose to roughly 76ms in Montreal and then to the final 175ms at TDC. The NTT example arrived at 181.747ms through US-labelled routers. Colt reached the same loopback in 22ms via a London TDC handoff.
Router names are not affidavits of physical location. Operators assign them, reverse DNS can be stale, and traceroute shows replies to probes rather than a commercial contract. Here, however, the names, the RTT jumps and the independent control path told a consistent enough story to justify investigation: at least two sampled paths were taking a costly transatlantic route while a short European route existed.
Then the GTT tests changed the diagnostic question. If GTT in London could hand traffic to TDC and complete the path in about 20ms, the fault was not simply “GTT has no European interconnect with TDC”. Operators had to ask which route each network learned, from whom, at which location and under what preference.
That is the difference between a route picture and a route diagnosis. A picture says where the answering hops appeared. A diagnosis must also explain why the selected advertisement won.
The prefix evidence moved the control point
A contributor added a Cogent looking-glass result from Germany for 93.178.128.0/18, the prefix containing the tested loopback. The displayed AS path was 3257 3292 3292 3292 3292: Cogent was learning the route through GTT, AS3257, with TDC's AS3292 prepended. The result showed a Canadian next hop and community 174:22003.
This was a more useful object than another city label. It connected the latency symptom to the route Cogent had selected. Even then, the output did not by itself reveal the contracts, export policy or intent behind that selection. It narrowed the investigation to a relationship among advertisements and interconnections.
The thread's later resolution supplied a reported answer. On 4 September, Keller said he had discussed the matter with TDC's peering manager and an engineer. According to his account, the unnamed UK AS was announcing the relevant prefix only to Cogent, despite having three other transits available. Cogent, meanwhile, would not peer with TDC in Europe.
Those two choices fit together. A UK network can buy several transits yet make a prefix reachable through only one of them. A carrier can have a physically extensive European network yet lack the particular European peering relationship needed for the preferred route. Neither fact is visible in a corporate coverage map. What matters is the advertisement that enters BGP and the policy that ranks it.
No public Cogent or TDC postmortem accompanies the thread, so this remains the reporter's account of the carriers' diagnosis. It is still more specific, and more operationally testable, than the early theory about GTT's geography.
The fix was direct — and singular
Keller reported that TDC arranged a direct route between itself and the UK AS. On 7 September he relayed that both networks were present at the London Internet Exchange and said the arrangement appeared to be there. The reviewed record does not expose the session, route-server entry or BGP export that would independently prove the location, so LINX should remain a reported inference.
The important result is plainer: Keller said the route solved the problem.
The important qualification arrived in the same update. The direct route was non-redundant. If it failed, traffic could temporarily return to the North American path.
That sentence turns a successful incident response into an unfinished resilience decision. A direct bilateral path can be an excellent quick repair. It places the relevant networks in control, shortens the path and avoids waiting for a larger carrier to alter a general peering policy. But one session, one port or one exchange fabric can also become the only thing standing between normal latency and the old detour.
The new route therefore did not eliminate the original path. It demoted it to a failure state.
That distinction matters for service operators. A dashboard observed only in normal conditions will now show success. The risk appears only when the direct session is withdrawn, its transport fails, maintenance begins or one party changes export policy. Without a controlled failover test, the team knows that the primary path works and only suspects what the backup will do.
What the thread proves — and what it does not
The public material establishes a sequence of operator-reported evidence. It shows three contrasting path samples toward a TDC loopback. It shows GTT's European looking-glass paths contradicting the first interconnect hypothesis. It shows a Cogent route for the covering prefix learned through GTT. It records Keller's later account of the UK AS export policy, Cogent's peering stance and TDC's direct-route repair.
It does not name the UK AS, the building-managed provider or the application destination. It does not publish a measurement ID, packet capture, collector replay, bilateral configuration or post-change endpoint trace. It does not prove that the forward and return paths were the same. It does not show that every Cogent or NTT path, every TDC prefix or every hour behaved this way.
It also does not prove why the UK AS exported the prefix only to Cogent. Participants discussed price and incentives. Those are plausible hypotheses, not evidence of a financial motive. A good operational account can explain the control surface without inventing intent.
The case is valuable precisely because the diagnosis improved in public. The community did not stop at an evocative traceroute. It found a counterexample, examined the covering prefix, contacted a network able to change the path and recorded the weakness of the repair.
A repair record should include its failure state
The missing operational object is compact. First, identify the exact UK prefix and list the transits to which it is exported. Second, record the direct session's location, owner and accepted route set. Third, nominate an independent European backup that does not share the same port, transport or policy dependency. Fourth, measure both normal and withdrawn-primary states from the affected endpoints.
This is not paperwork for its own sake. It separates four questions that the initial trace compressed into one: where packets were observed, which advertisement won, who could change the decision, and what happens after that change fails.
The first three questions got useful answers in the RIPE thread. The fourth remains open.
Evidence boundary
The latency values and route outputs are the measurements posted by thread participants. The diagnosis and successful repair are Keller's account after discussions with TDC, not an independently published carrier incident report. RIPEstat supplies current ASN and prefix identity, not a historical replay. RIPE Atlas documentation is used only to bound what path observations and reverse-DNS-based location inference can establish.
Sources
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance