
Summary
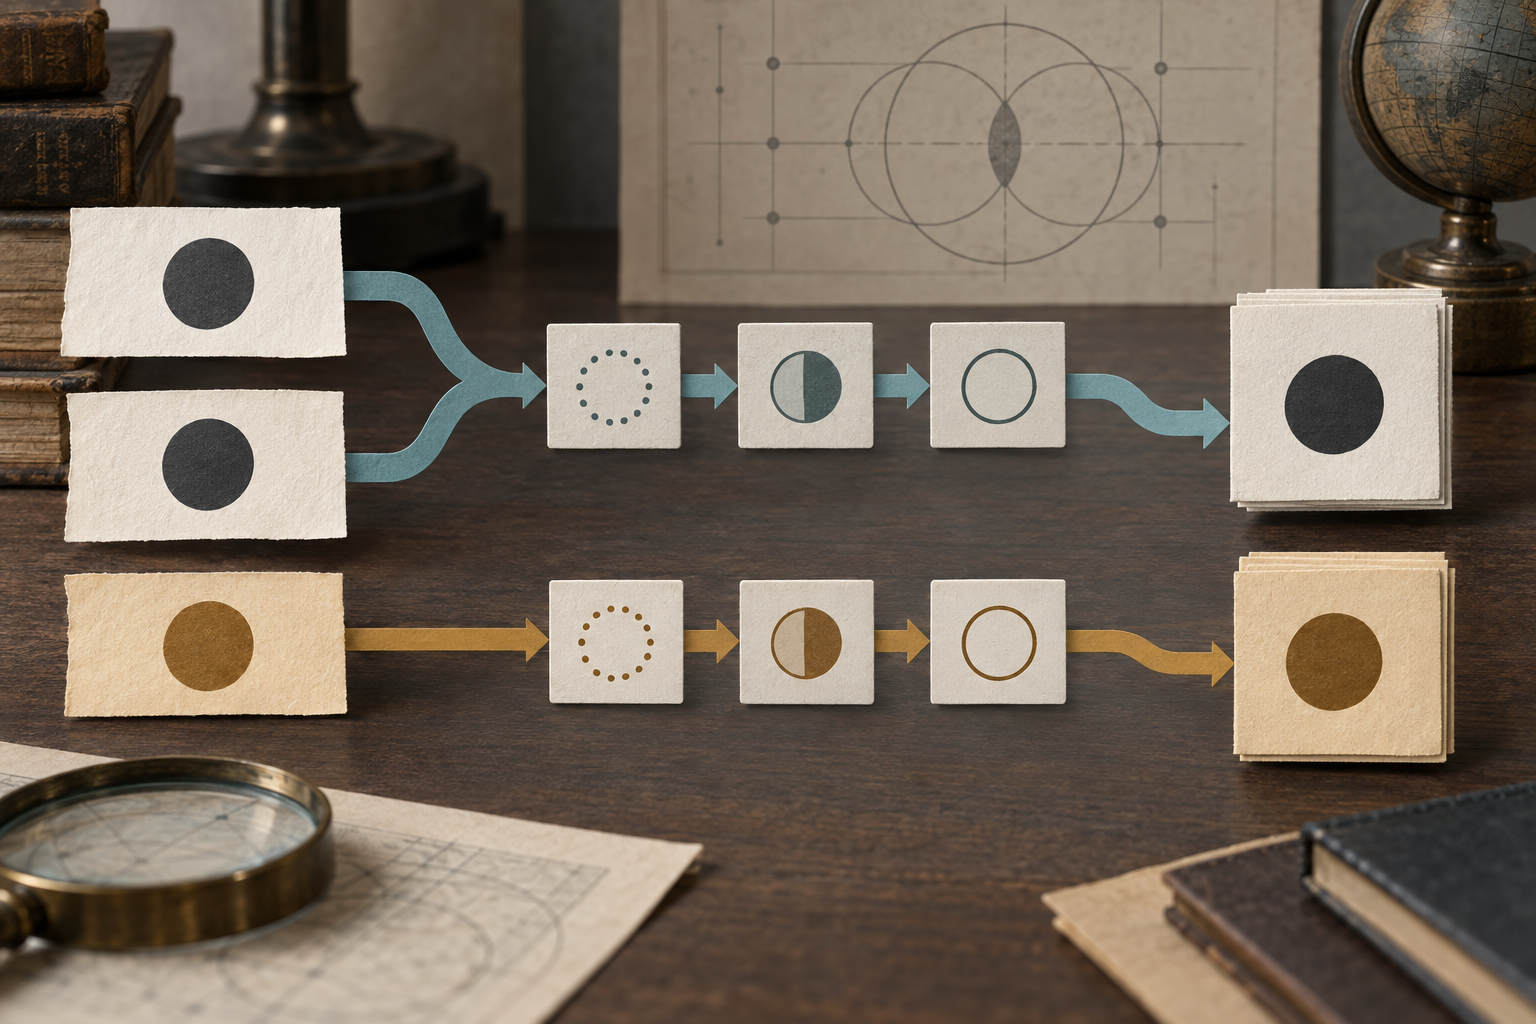
- RFC 3722 turned iSCSI name entry into a prescribed sequence of Unicode mapping, NFKC normalization and prohibited-character checks so implementations could compare the prepared UTF-8 form byte-for-byte.
- That repeatability addressed transcription and implementation constraints, not identity ownership or spoofing: visually similar characters remained distinct, and the profile was frozen to Unicode 3.2.
In a storage console, two names can look interchangeable to a person and still be different to a target. That gap matters when an administrator types a name from a label, email or runbook, but a compact initiator must decide whether the bytes it received match a configured target. RFC 3722, published in April 2004, addressed that narrow but consequential boundary for Internet Small Computer Systems Interface (iSCSI) names.
The design problem was a collision between two expectations. A person transcribing an internationalized name benefits from case-insensitive handling and predictable treatment of equivalent character sequences. A simple or embedded device benefits from a comparison rule it can implement exactly: prepare the name, encode it as UTF-8 and compare the resulting octets. If each side makes its own discretionary choices, one spelling can produce different protocol values. If a device is expected to perform broad, locale-sensitive matching, the protocol becomes harder to implement and less predictable.
RFC 3722 chose a profile rather than an open-ended cleanup process. It specifies Unicode 3.2 as the repertoire and applies Stringprep mappings, normalization and rejection rules. The mapping tables include B.1 and B.2 from the Stringprep framework; the profile then uses Normalization Form KC (NFKC), checks prohibited output against tables C.1.1 through C.9, and applies bidirectional-string checks. The sequence is important: the implementation is not invited to invent a more convenient equivalence relation after seeing the input.
The rules make some input distinctions disappear and preserve others. Uppercase ASCII entered through a user interface MUST be mapped to lowercase. The permitted ASCII set includes lowercase letters, digits, hyphen, period and colon; whitespace is excluded. A subtle example is U+3002, the ideographic full stop: RFC 3722 prohibits it even though some domain-name input systems treat it as equivalent to the ASCII period U+002E. The profile therefore does not simply inherit whatever substitutions another application happens to perform.
The result is not “all Unicode cleaned up.” It is a specific prepared representation under an explicitly named repertoire and table set. The UTF-8 encoding rules come from the separate UTF-8 specification, and the iSCSI name grammar and naming-authority constraints remain separate checks. RFC 3721 describes the surrounding name and discovery model; RFC 3722 supplies a string-processing profile. Neither turns successful preparation into proof that a name is authorized, currently controlled by a particular party, or reachable at a particular address.
The residual limitation is the part easiest to miss. RFC 3722 does not map visually similar characters to one another. A Latin letter, a Greek or Cyrillic lookalike, or two glyphs that a particular font renders similarly do not become equal merely because a human reader confuses them. The security section explains the risk: if systems or operators use inconsistent interpretations, an initiator could reach a different target than intended or fail to reach the legitimate one. That is a warning about a possible failure mode in name handling, not a report of a demonstrated exploit.
This boundary clarifies what Stringprep can and cannot decide. Mapping and normalization can converge defined variants into one representation. Prohibited tables can reject inputs the protocol does not permit. Bidirectional checks can enforce constraints for mixed-direction text. But none of those operations establishes who owns the naming authority, whether a displayed label is trustworthy, or whether a visually deceptive string should be accepted by a human. Those questions require controls beyond this profile.
RFC 3491, Nameprep, is related because it defines another Stringprep profile for internationalized domain names. It is not the iSCSI profile, and domain-name conventions should not be silently imported into iSCSI name processing. RFC 3454 provides the framework; RFC 3722 selects the rules for its own protocol purpose. RFC 7143 later consolidated iSCSI protocol material, but the historical profile’s Unicode 3.2 basis remains a property of RFC 3722—not a current recommendation for every new identifier system.
The standard thus traded permissive interpretation for reproducibility. It gave implementers a fixed recipe and operators a way to reason about why two inputs compare equal or fail. Yet a reproducible comparison is only as sound as the string presented to it, and it does not resolve lookalike deception. The lasting lesson is not that Unicode became safe for storage names; it is that a protocol must define exactly which differences it erases, which it rejects and which it leaves for people and surrounding controls to manage.
Sources
- RFC 3722 — iSCSI Name String Profile
- RFC Editor — RFC 3722 information
- RFC 3722 errata
- RFC 3721 — iSCSI Naming and Discovery
- RFC 3720 — iSCSI Protocol
- RFC 3454 — Stringprep framework
- RFC 3491 — Nameprep profile
- RFC 3629 — UTF-8
- RFC 7143 — Consolidated iSCSI Protocol
- RFC 2396 — URI Generic Syntax
- RFC 2732 — IPv6 literals in URLs
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance