
Summary
- RFC 3492's Bootstring copied basic ASCII code points literally, then encoded every non-basic point as a delta that carried both code-point distance and an insertion position in the growing output.
- Self-delimiting integers and adaptive bias made that representation unique and reversible. They did not make it a translation, normalization, IDNA validation, registration receipt or identity proof.
Punycode is often remembered by its visible result: an ASCII label whose latter half seems opaque. RFC 3492 is more interesting when read backward, from the decoder's bench. The decoder does not translate a word. It reconstructs a sequence by starting with the characters that could already survive in ASCII and inserting everything else into exact gaps.
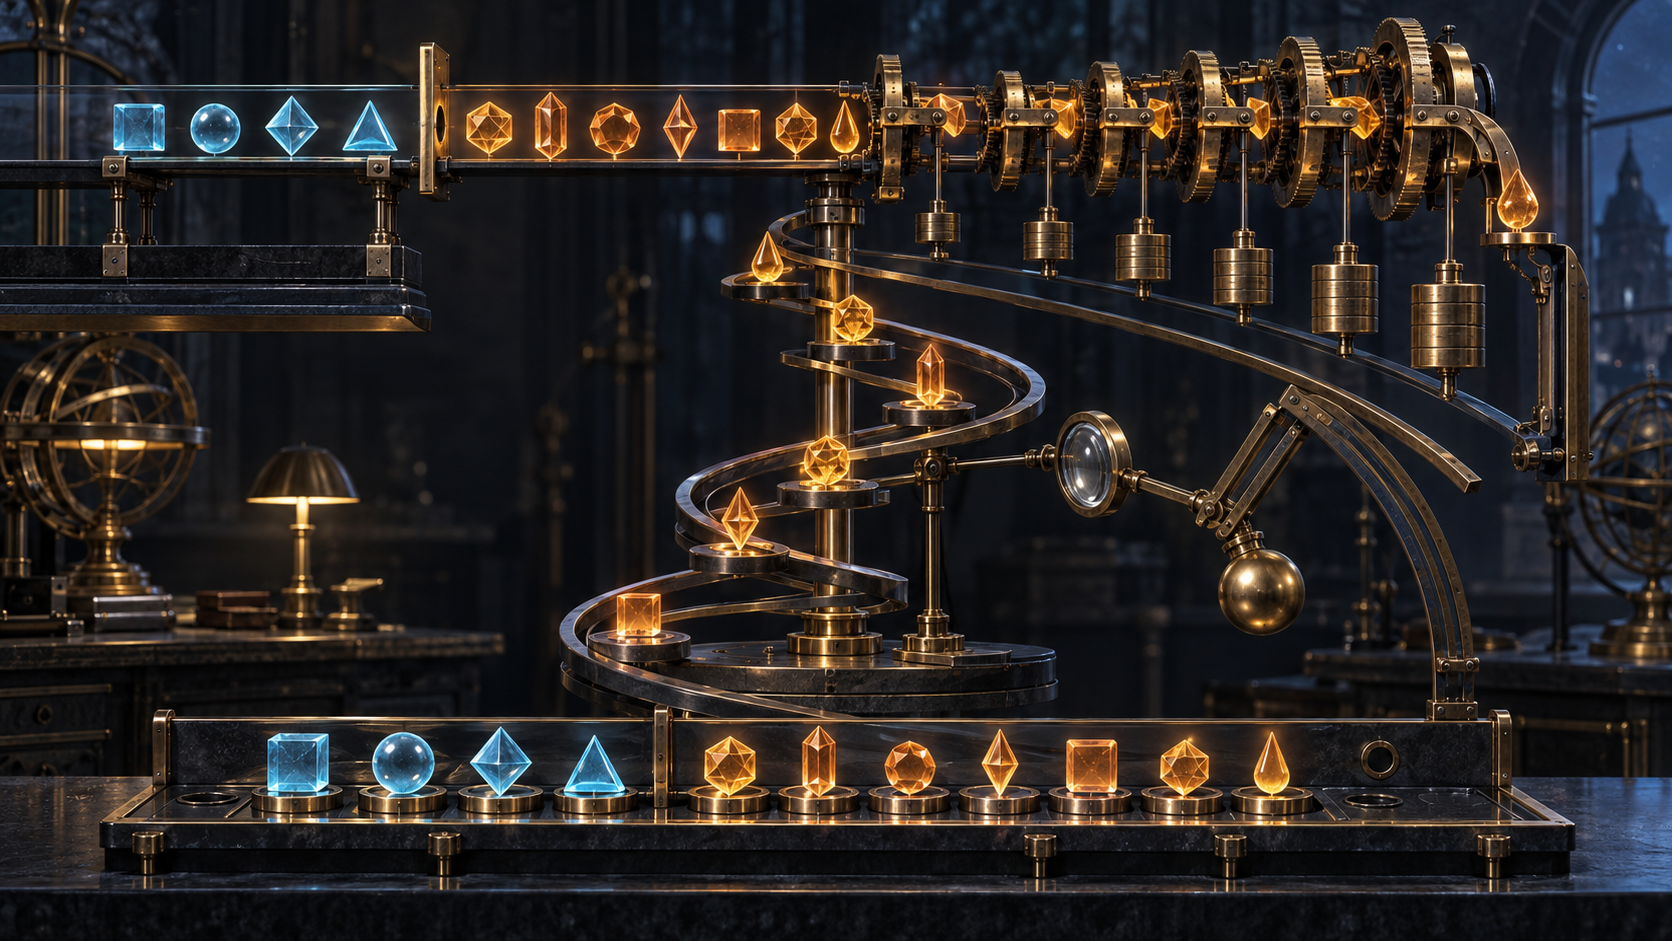
Bootstring first segregates the basic code points. It copies them to the front in their original relative order. If at least one exists, a delimiter follows. For Punycode the basic set is ASCII and the delimiter is the hyphen-minus. This literal portion is not a miniature translation. It is simply the part of the input that needs no encoding.
The tail carries the missing structure. The decoder maintains two state variables: n, a candidate code-point value, and i, a possible insertion position in the output built so far. Advancing the state moves i through every gap; after the end, i wraps to zero and n increases. A delta says how many of those non-insertion states to cross before inserting the current n at the current i.
That is the crucial compression. One nonnegative integer carries a distance through code-point space and a location in the growing string. The encoder processes non-basic points in numerical order, which tends to keep successive distances smaller, and derives the deltas that will make the decoder rebuild the original order. The tail therefore records position without writing an explicit position table.
Several deltas must be concatenated, so ordinary positional integers would leave an ambiguity about where one ends. Bootstring instead uses generalized variable-length integers. A threshold for each digit decides whether another digit follows. Exactly one final digit falls below its threshold. With little-endian digits, a decoder can separate the first integer, then the next, while reading forward. For fixed thresholds, each nonnegative integer has exactly one representation.
The thresholds do not stay fixed across deltas. After every insertion, an adaptation function changes a bias. A large first jump is damped strongly; later jumps are scaled and adjusted for the number of code points already handled. The latest delta becomes a hint about the likely size of the next. This is not linguistic prediction. It is a local arithmetic forecast used to spend fewer basic characters on nearby magnitudes.
Punycode fixed the mechanism at base 36, with letters carrying values zero through 25, digits carrying 26 through 35, an initial code point of 128 and an initial bias of 72. The parameter set shaped efficiency. Provided Bootstring's constraints held, the parameters did not change whether encoding and decoding were correct.
Correctness still required defensive arithmetic. RFC 3492 identifies overflow as a failure and shows where additions and multiplications must be checked. It argues that a 26-bit unsigned integer is sufficient for valid IDNA labels under Unicode and the 63-character DNS label limit. That bounded conclusion did not turn unchecked overflow into acceptable behavior for a general implementation.
Uniqueness mattered to security. If one Unicode sequence could acquire several ASCII encodings, those labels could live under different DNS authorities. Punycode avoided that split by offering at most one basic string per extended string. Yet the RFC immediately preserved the next boundary: different Unicode sequences may still count as “the same” text under some human, language or normalization rule. Punycode never decided that question.
RFC 3490 placed Punycode inside IDNA's acceptance and display operations. IDNA2008 later kept Punycode A-labels while changing surrounding preparation and validity rules. That continuity illustrates Heng Lu's minimum-initial-specification principle. A narrow reversible encoding could remain stable while policy about admissible code points, local mapping and registration evolved elsewhere.
The reality-layer lesson is equally exact. Input code points, prepared code points, literal prefix, delta stream, reconstructed sequence, accepted A-label, registered name, DNS answer and recognized identity are different receipts. Punycode joined two of them: a sequence and its ASCII representation. Its success was refusing to pretend it had joined the rest.
Sources
- RFC 3492
- RFC 3492 text
- RFC Editor record
- IETF Datatracker record
- IETF history
- RFC 3492 errata
- RFC 3490
- RFC 3491
- RFC 3454
- RFC 5890
- RFC 5891
- RFC 5892
- RFC 5894
- RFC 5895
- RFC 1034
- RFC 1035
- IANA Repository of IDN Practices
- Unicode Technical Standard #46
- Heng Lu on minimum initial specification
- Heng Lu on reality layers
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance