
Summary
- RFC 3469 divided MPLS recovery into detection, hold-off, notification, switching and actual traffic return; completing a control action was not the last event.
- A pre-established recovery path could still share the failure, lack reserved capacity, provide reduced service or leave traffic unprotected while the network waited for a permanent arrangement.
The backup line was already drawn on the operator's diagram. Labels had been assigned. The management system called the path “protection.” Then the working route failed, and none of those facts answered the question that mattered: could the traffic use the other path now?
RFC 3469, published as an Informational memo in February 2003, turned that uncertainty into a framework. It did not specify one protocol and did not certify a deployment. Restart behavior was outside its scope. Its contribution was to dismantle the convenient word recovery into events that different machines, teams and clocks owned.
The first distinction was between rerouting and protection switching. Rerouting created a new path or path segment after a fault. Protection switching used a recovery path established before the fault. The two were not rivals. A network could switch rapidly onto a prepared detour, enter a semi-stable state, let routing converge and later move traffic to a more suitable working path.
That sequence explains why a backup-path object was weak evidence. A pre-established path might overlap the working path at the failed link or node. It might have labels but no reserved bandwidth. It might be a path built for another purpose and merely pre-qualified as acceptable. It could fail before, or with, the working path. Its control-plane existence said little about what resources would be available during a shared emergency.
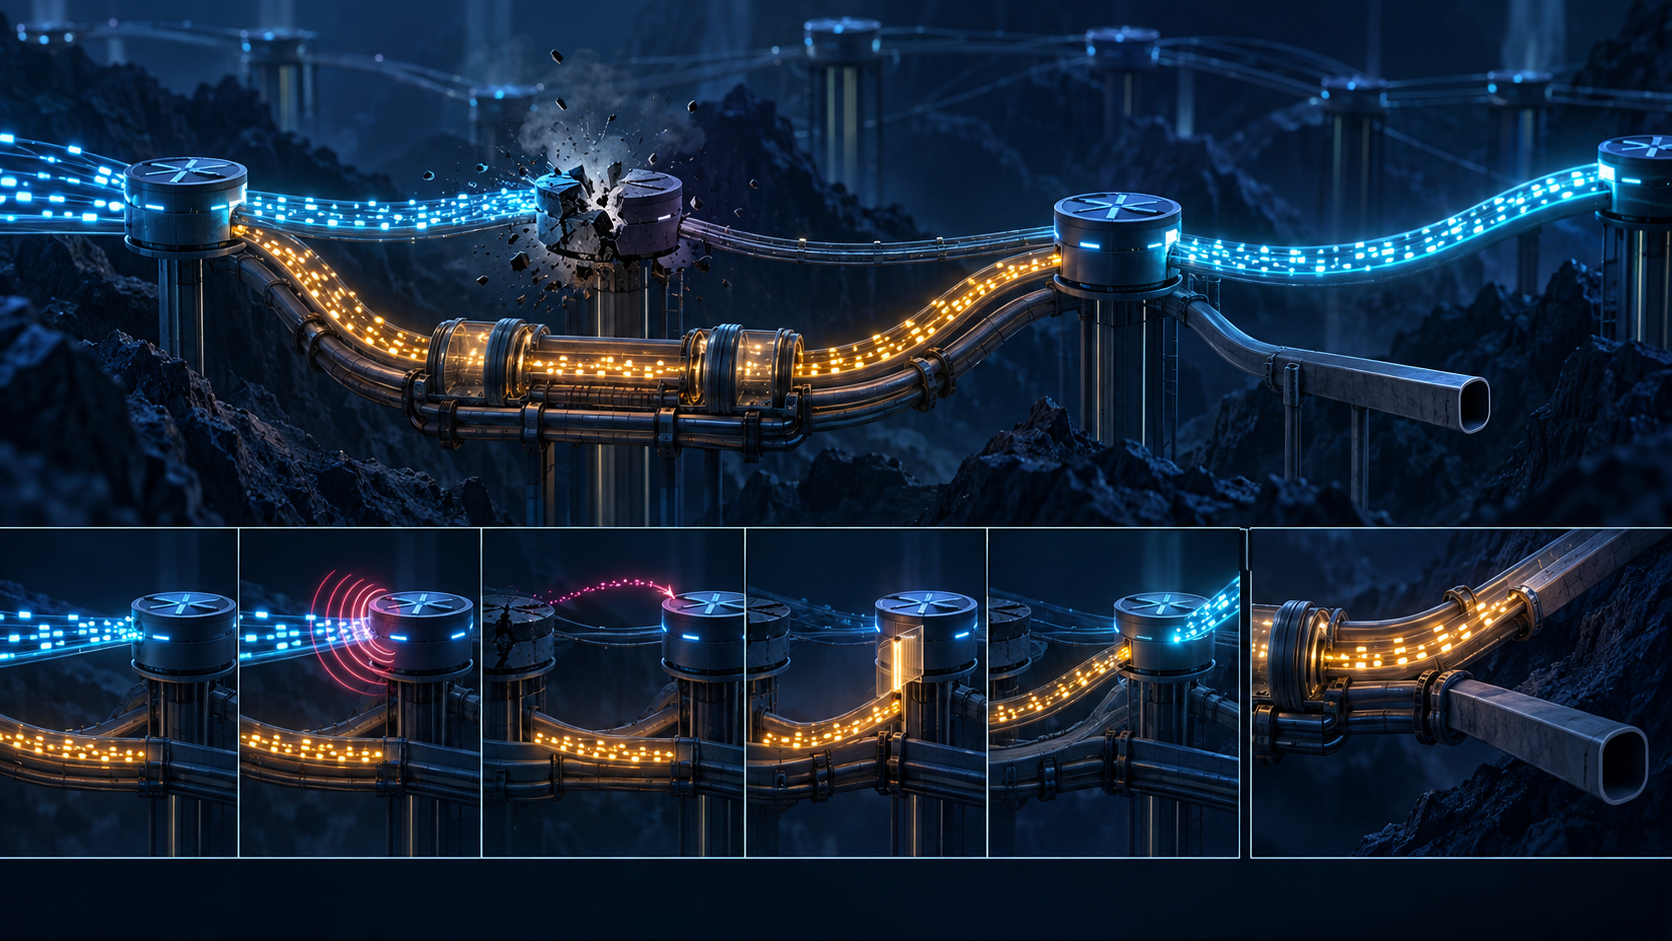
RFC 3469 gave the initial recovery cycle five intervals. T1 ran from impairment to detection. T2 was an optional hold-off before MPLS action. T3 carried a Fault Indication Signal to the Path Switch LSR when the detecting node could not repair locally. T4 covered the recovery operation, including any exchange with the Path Merge LSR. T5 began after the last control action and ended only when traffic had again arrived at the disrupted point.
The last interval is the quiet correction to many modern dashboards. “Switch completed” is not “traffic recovered.” Labels may have changed while packets are still propagating, queuing, being discarded, arriving out of order or contending for insufficient resources. An honest clock stops at observed traffic, not at the configuration transaction.
Even that is only initial recovery. RFC 3469 separately modelled reversion. Repair of the impairment had to be detected; a clear hold-off could test stability; a clear notification could travel; the reversion operation could run; then traffic had to return to the preferred path. Immediate switch-back was not always virtuous. If a repaired path flapped, haste created another outage. Make-before-break could reduce loss and reordering, but it still needed an observed completion.
A third cycle handled dynamic rerouting. Once routing protocols converged, the network could calculate and establish a new working path, optionally wait through a bounded hold-down, switch again and observe traffic on the new route. Fast protection therefore bought time. It did not necessarily deliver the final topology.
The framework made path setup and resource allocation independent dimensions. A recovery path could be pre-established, pre-qualified or established on demand. Resources could be pre-reserved or reserved only after failure. RFC 3469 called a path equivalent when it could preserve the working path's performance guarantees, and limited when it could not. A limited path was useful precisely because degraded service could be better than no service, but it was not supposed to become an invisible permanent condition.
The familiar protection ratios carried different costs. In 1+1 protection, traffic was replicated and the merge point selected a copy; capacity was consumed continuously. In 1:1 protection, the spare route could carry preemptible lower-priority traffic until a fault displaced it. One-for-many and many-for-many designs shared capacity more aggressively, making the simultaneous-failure set and protection plan decisive. “One backup exists” did not say who would receive it.
Topology also changed the receipt. Local repair could react near a failed link or neighbour and avoid a long notification path. Global repair could protect a larger segment and perhaps use a more disjoint route, but the point of repair needed the alarm. An alternate egress could restore forwarding without recreating the exact old path. A bypass tunnel could aggregate many recovery paths while holding enough resources for only some of them at once.
Nor did recovery necessarily cover every packet. The framework allowed selected protected traffic portions and bundled path groups. A successful premium class could coexist with loss in ordinary traffic. The historical reference to MPLS header EXP bits must now be read through the later Traffic Class terminology in RFC 5462; the durable point is selective authority, not the old label.
Faults themselves had layers. Hard path or link failures differed from performance degradation. A degraded condition crossed a provisioned threshold before becoming a fault declaration. A lower layer could supply a faster signal. The node that detected the condition might send an FIS to a different node authorized to switch. Observation, declaration, notification and action were therefore four records, not one.
After the switch, the network faced another decision. In revertive mode, traffic returned to the preferred original path when it became stable. During the detour, that traffic might be unprotected because its one recovery path was already in use, while resources on the failed preferred path remained reserved. In non-revertive mode, the detour could become the new working path, the repaired route could become protection, or a newly optimized pair could be built. A green forwarding graph could still contain a large second-failure exposure.
RFC 3469 captured this with two measures. Recovery time included detection, hold-off, notification, operation and traffic return. Full restoration time lasted until traffic used links engineered to carry it under the recovery scenario. The two were equal only when initial recovery was already equivalent and permanent. That distinction is more informative than a single failover number.
The memo's comparison criteria broadened the record further: setup vulnerability, backup capacity, extra latency, protection quality, packet reordering, state overhead, loss and coverage. Its SONET-like 50 millisecond reference was an engineering aspiration around switching, not production telemetry and not an end-to-end guarantee.
Later work supplied mechanisms and vocabulary. RFC 4090 standardized RSVP-TE fast reroute. RFC 4426, RFC 4427 and RFC 4428 refined recovery terminology and multilayer analysis. RFC 5714 framed IP fast reroute. They show that the problem evolved; they do not prove that any particular RFC 3469 plan ran, that two paths were physically diverse or that an application stayed healthy.
Heng Lu's running-code lens supplies the final discipline. “Configured,” “pre-established” and “recovered” are symbolic states until forwarding and traffic receipts agree. The minimum-specification lens explains why RFC 3469 defined composable primitives instead of one universal repair algorithm. The reality-layers lens keeps impairment, alarm, switch, packet and application outcome separate.
The historical lesson is not that every network needs more backup paths. It is that a backup path is only one component in a recovery claim. Record who saw the fault, who declared it, who had authority to move traffic, which resources were actually available, where packets reappeared, what quality survived and when protection was restored again. Only then does the word recovery describe an event rather than a hope encoded in configuration.
Sources
- RFC 3469
- RFC 3469 plain text
- IETF Datatracker record
- IETF Datatracker history
- RFC 3469 errata search
- RFC 3031: MPLS Architecture
- RFC 2702: MPLS Traffic Engineering Requirements
- RFC 3272: Internet Traffic Engineering Overview
- RFC 3386: Network Hierarchy and Multilayer Survivability
- RFC 4090: RSVP-TE Fast Reroute
- RFC 4426: GMPLS Recovery Functional Specification
- RFC 4427: Recovery Terminology
- RFC 4428: Multilayer Recovery
- RFC 5462: MPLS Traffic Class Field
- RFC 5714: IP Fast Reroute Framework
- Heng Lu: Running-Code Primacy
- Heng Lu: Minimum Initial Specification
- Heng Lu: On Reality Layers
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance