
Summary
- RFC 3386 described a cross-layer recovery race: optical or SDH/SONET protection could respond to the same physical failure that MPLS or IP was preparing to route around.
- A hold-off timer gave the lower layer a bounded first chance to recover. It coordinated authority; it did not prove that service, route diversity or the application had recovered.
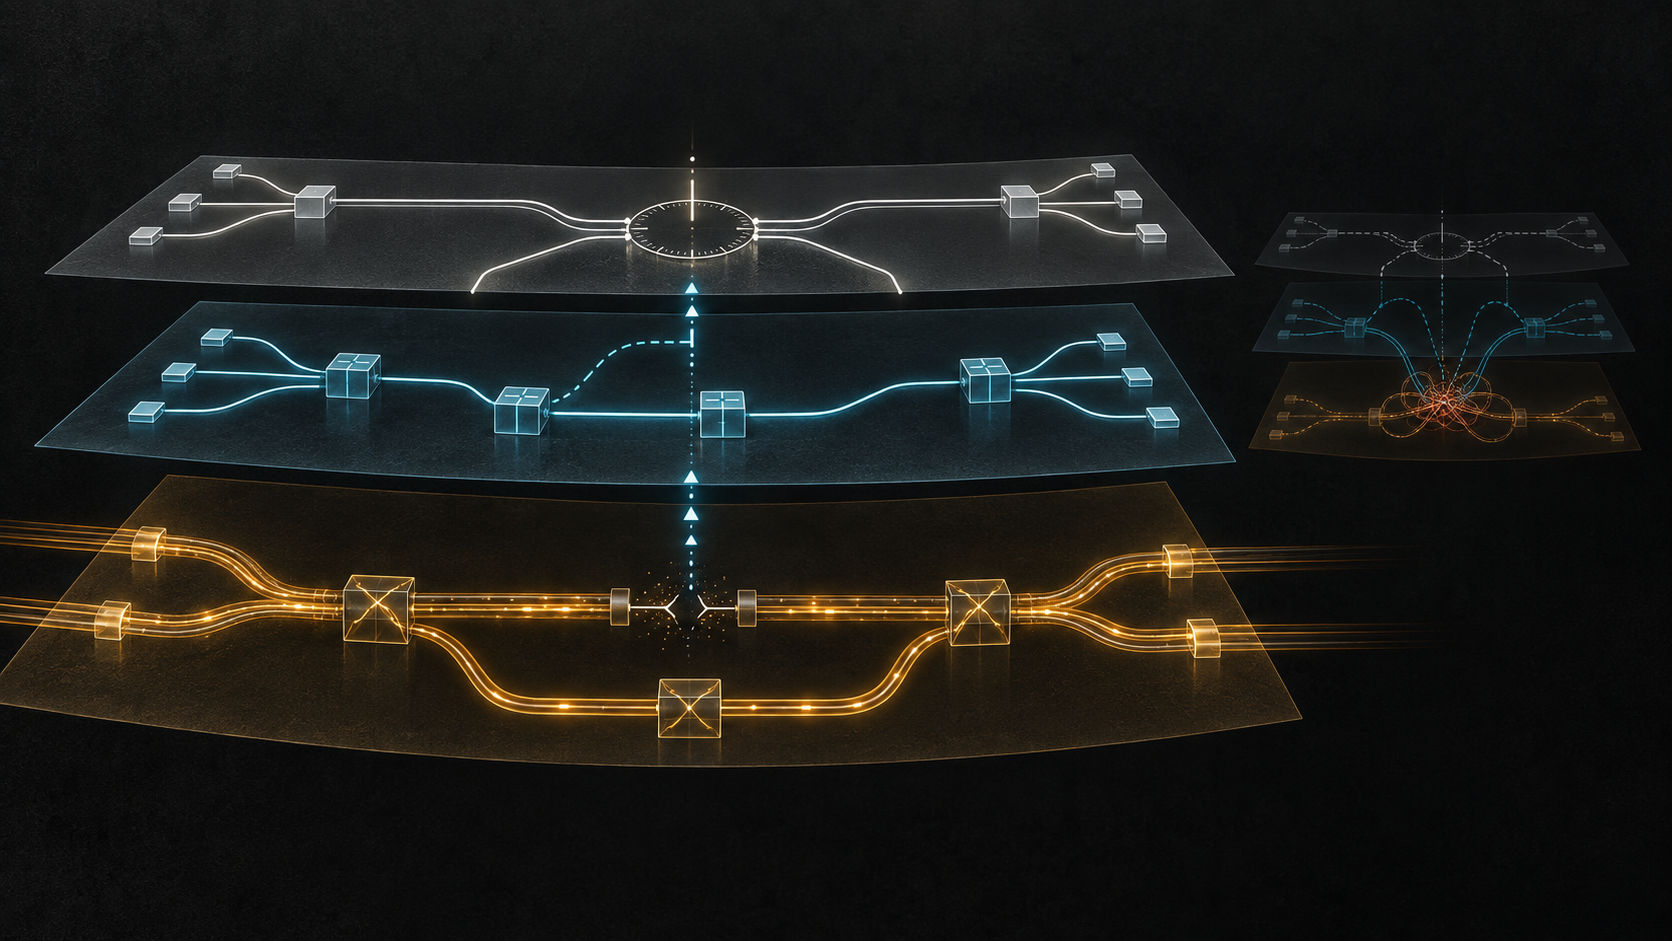
A cable is cut. The optical equipment sees loss of light. SDH/SONET sees a failed circuit. MPLS sees labels stop carrying traffic. IP sees reachability deteriorate. Each layer can have a sensible local answer, and that is precisely why the system can make a bad global decision.
If every controller reacts immediately, the lower layer may switch the circuit while the upper layer is rerouting the same demand. Traffic moves twice. Spare capacity is claimed twice. A path calculated from one topology becomes stale while another layer silently changes the substrate beneath it. What looks like redundancy becomes a race among partially informed repair systems.
RFC 3386, published in November 2002 as an Informational memo, treated this as a practical service-provider problem. It came from a design team in the IETF Traffic Engineering Working Group. The document did not standardize one recovery protocol or certify one deployment. It collected near-term requirements for survivability and hierarchy across packet and non-packet networks.
Its most revealing mechanism was modest: let one layer wait.
The memo distinguished vertical hierarchy—communication and abstraction between technologies such as optical transport and MPLS—from horizontal hierarchy among areas or administrative subdivisions of one technology. Vertical recovery was difficult because each layer could protect itself while hiding its detailed operation from the others.
RFC 3386 proposed nested timers as a default form of loose coordination. When a lower layer needed longer to restore than a higher layer, the higher layer could hold off. In its concrete example, MPLS recovery had to leave enough time for SDH/SONET protection switching. The lower layer received a temporary first right to repair the service.
That delay had a price. Too short a timer allowed both layers to act and contend for resources. Too long a timer extended an outage that the upper layer might have repaired. The timer was therefore not a generic performance knob. It encoded an operational belief: this lower layer is configured to protect this service, and it deserves this much time before authority returns upward.
The opposite configuration changed the answer. If an SDH/SONET circuit was unprotected, or the lower layer was not expected to restore it, the upper layer should not wait through a ceremonial timeout. RFC 3386 required adjustable hold-off values or an immediate lower-to-higher fault indication so the higher layer could act at once. One fixed timer could not honestly represent both protected and unprotected infrastructure.
The direction was asymmetric. The memo said higher-layer faults should not trigger lower-layer protection. A routing failure is not automatically an optical failure, and a lower layer that lacks that context should not start moving physical resources merely because an upper protocol is unhappy.
Timing numbers appeared in the document, but with unusually useful restraint. The design team proposed 100–500 milliseconds for 1:1 protection with pre-established capacity, 100–750 milliseconds with pre-planned capacity, 50 milliseconds for local restoration and one to five seconds for source path restoration. The figures excluded propagation delay. The authors also said they would not attest to scientific proof that those bounds met the needs of any specific application.
That caveat changes how the table should be read. It was a requirements scaffold, not field telemetry and not an SLA. A 50-millisecond network action does not establish that a voice call, financial transaction or application session remained usable. Detection, hold-off, switching, convergence and propagation occupy different portions of the clock; the application owns the final continuity test.
The memo also separated protection from restoration. Protection relied on resources arranged in advance. Restoration selected a new route after a fault. Pre-established protection committed capacity, while pre-planned protection could share or double-book it. Shared spare capacity improved utilization during normal operation but created a scarcity decision when several services failed together.
Restoration and preemption priorities made that decision visible. Higher-priority traffic could be recovered first; lower-priority or extra traffic could be displaced if capacity ran out. “Backup exists” was therefore incomplete. An operator needed to know whether capacity was reserved, shared, already occupied, preemptable and sufficient for the simultaneous failures being designed against.
Shared-risk groups supplied the physical boundary. RFC 3386 defined an SRG as elements collectively affected by one fault or fault type. Two logical links might share a conduit, fibre cable, right of way, optical ring or office. A calculated alternative could be topologically distinct at MPLS while remaining attached to the same lower-layer failure domain.
Local restoration and path restoration exposed another tradeoff. Repair near the fault could be fast, but the resulting path could be inefficient and later require re-grooming by the head end. Source-based rerouting could use resources more efficiently but usually took longer. The first route to carry packets again was not necessarily the stable route the operator should retain.
Horizontal boundaries had their own receipt problem. RFC 3386 wanted inter-area signaling to communicate whether restoration succeeded or failed. Without that result, the other side of a connection could perform unnecessary work or preserve a path whose remote segment was still down. A recovery request, a recovery attempt and a recovery result were separate records.
Later documents sharpened the vocabulary without erasing the original compromise. RFC 4427 defined a common recovery language. RFC 4428 examined multilayer recovery and the danger of duplicated action. RFC 7347 retained a provisionable hold-off concept for MPLS transport protection. RFC 7926 later showed how abstraction between client and server layers can conceal shared-risk information. These are continuities in design reasoning, not proof that RFC 3386’s targets were universally deployed.
Lu Heng’s minimum-initial-specification lens clarifies why the memo preferred a small interoperable set of mechanisms over an all-knowing cross-layer control plane. Recovery order, fault indication and timers were shared decisions that needed a minimum contract. Internal algorithms and topology could remain local. Coordination did not require one layer to become sovereign over every other layer.
The reality-layers lens reveals what the timer cannot say. A configured lower-layer protection scheme, a detected fault, a switch command, a completed switch, a restored MPLS path, a converged IP route and a functioning application are different facts. Timer expiry proves only elapsed time. It cannot promote an assumption about a hidden layer into a receipt from that layer.
The durable lesson of RFC 3386 is therefore not “wait for optics.” It is to make recovery authority explicit and temporary. Name the layer expected to act. Record the failure domains it actually covers. Give its action a deadline. Provide immediate escalation when that action is unavailable. Preserve the completion receipt. Then test the service at the boundary that matters.
A resilient network is not one with the most recovery mechanisms. It is one in which those mechanisms know when to act, when to wait and when to return control—and in which nobody mistakes the wait for evidence that the service came back.
Sources
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance