
Summary
- The source set examined for this briefing identifies public information surfaces for ISC, its status reporting, F-Root and the wider root-server system, but it does not independently verify a named incident, deployment test, recovery action or measurable performance result.
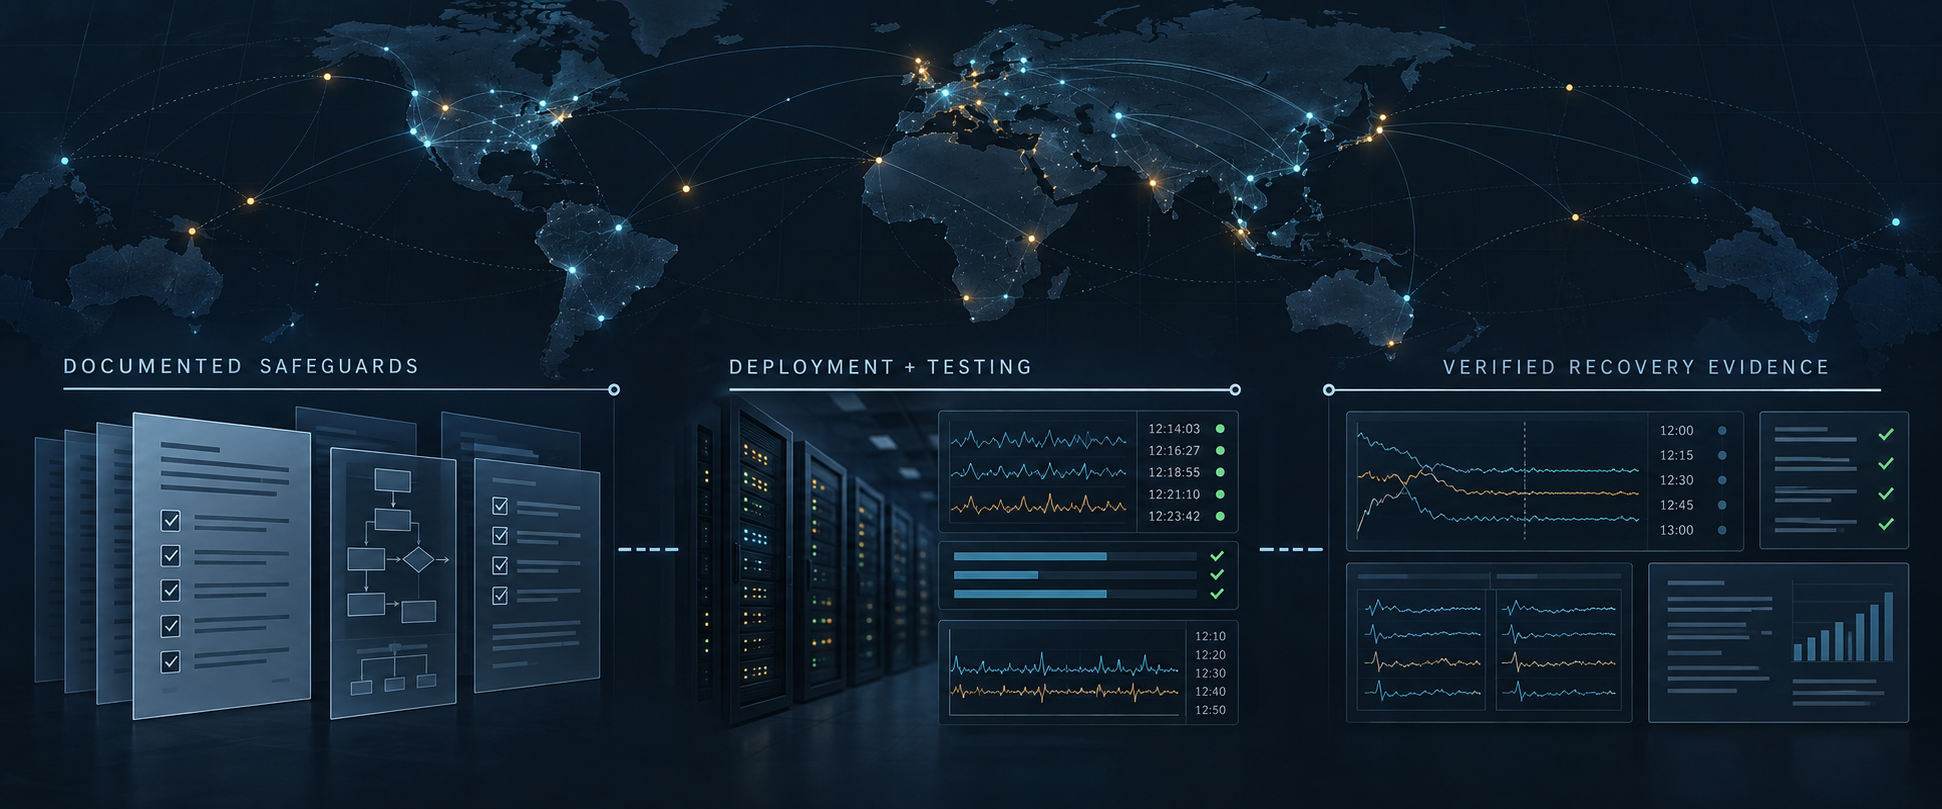
- Operational assurance becomes auditable when a record connects seven fields: the event or test, its scope, its timing, the responsible control, the observed result, the remedy and later validation.
The difficult part of infrastructure assurance is not finding a page that says a control exists. It is following that control through a specific operational sequence: a condition is detected, someone becomes responsible, an action is taken, an outcome is measured and the result is checked again after the immediate pressure has passed.
That distinction matters for ISC-AGP1 Internet Systems Consortium Inc.. A public interface can document where information should appear. It cannot, by its existence alone, demonstrate that every relevant action occurred, that a downstream environment adopted a remedy or that the remedy remained effective.
Five visible information surfaces
The record examined here contains five official or authoritative starting points. The ISC status page is the organisation’s public status surface. The ISC website is its principal institutional and operational landing point. The F-Root site provides a service-specific operator surface. The Root Server Technical Operations Association site supplies wider root-server context, while InterNIC’s root-server technical-operations page provides another authoritative ecosystem reference.
Together, these pages establish where a reader may look for institutional, status and root-server information. In the source set reviewed for this briefing, however, they did not yield an independently verified record of a specific ISC-related incident, maintenance event, deployment test, recovery action or quantified performance result.
That is a bounded research finding. It does not establish that ISC suffered a failure, that no internal tests exist, that no operator deployed a remedy or that relevant evidence is unavailable elsewhere. Absence from this source set is not evidence of operational absence.
Three different levels of assurance
A useful accountability test separates three levels that are often compressed into one claim.
A described mechanism shows that an organisation has named a process, interface or control. It may tell readers where notices are posted or where operational information is maintained.
An execution record shows that the mechanism was used in a defined situation. It connects a named event or test to an action, an owner and an observed result.
A durability record shows what happened after the immediate response. It identifies whether the remedy remained in place, whether the same condition recurred and whether later testing reproduced the expected result.
The first level is valuable. It enables scrutiny and gives operators a place to begin. But it cannot substitute for the second and third levels. A design may be sound while execution varies; an immediate remedy may work while follow-up validation remains incomplete. The evidentiary task is to preserve those distinctions rather than award or deny confidence on the strength of a landing page.
The seven-field assurance ledger
An auditable ISC-related operational record would not need to disclose every sensitive technical detail. It would need enough structure to let an operator, investigator or affected community follow the chain of practical control.
Named event or test. The record should identify what triggered action: an incident, a maintenance exercise, a deployment validation or a resilience test. A stable identifier prevents later updates from becoming detached from the event they describe.
Defined scope. Readers need to know which service, software release, environment or user population was inside the assessment—and what remained outside it. Without scope, a successful result can be mistakenly treated as universal.
Time sequence. Detection, acknowledgement, intervention, restoration and closure should be separated. A single statement that an issue was “resolved” cannot show how long each control stage took or where delay accumulated.
Responsible control and owner. The record should identify which control was expected to prevent, detect or contain the condition and who could activate it. Responsibility may sit with ISC for one stage and with another operator for another; an assurance record should not collapse those roles.
Observed result. The record should state what was measured and by whom. Availability, correctness, deployment completion and user impact are different observations. A result is more useful when its method and limits are visible.
Remedy and deployment state. Publishing or preparing a remedy is not identical to completing deployment. The ledger should distinguish the action ISC took from any action required in systems controlled by others, and it should avoid claiming completion beyond the evidence available.
Follow-up validation. Durable repair requires a later check. That may be a repeat test, a review of recurrence, an independent observation or another bounded validation. The purpose is not to promise permanence; it is to show whether the original result survived time and operational change.
Who can close the evidence chain
No single party necessarily controls every field. ISC can document actions, timing and observations within the systems or processes it controls. Dependant operators can preserve evidence about their own testing and deployment. Independent observers can publish their methods and distinguish direct measurement from inference. Affected organisations can record the service consequence they actually experienced rather than assuming that a central notice describes every local outcome.
This division of responsibility is not a reason to abandon assurance. It is the reason the evidence must be linked. If each party publishes only its own isolated statement, readers receive fragments: a remedy without deployment, restoration without scope or monitoring without a named event. An event-to-repair ledger makes the hand-offs visible.
What the present record permits
The examined pages support a limited conclusion: ISC and the root-server ecosystem maintain identifiable public information surfaces. The same record does not independently establish a particular operational outcome under pressure. Confidence should therefore remain proportional to what is visible.
That is neither an accusation nor a clean bill of health. It is an evidence boundary. The practical remedy is not to infer failure from silence, but to ask for a record that can survive later review: named event, bounded scope, dated sequence, accountable control, observed result, deployment state and follow-up validation.
Operational assurance becomes credible when a reader can trace those fields without having to convert institutional description into assumed performance.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance