
Summary
- Simultaneous multithreading lets instructions from several independent hardware contexts issue to one wide superscalar core in the same cycle. It exploits thread-level parallelism to fill capacity that a single thread's instruction-level parallelism leaves unused; it is not the same as adding physical cores.
- The celebrated 1995 results were workload- and machine-model results: up to eight contexts on a widened Alpha 21164-derived model, with multiprogrammed SPEC92 workloads and important trade-offs in per-thread progress, shared-cache pressure, fetch policy and implementation complexity.
The dark squares inside a wide core
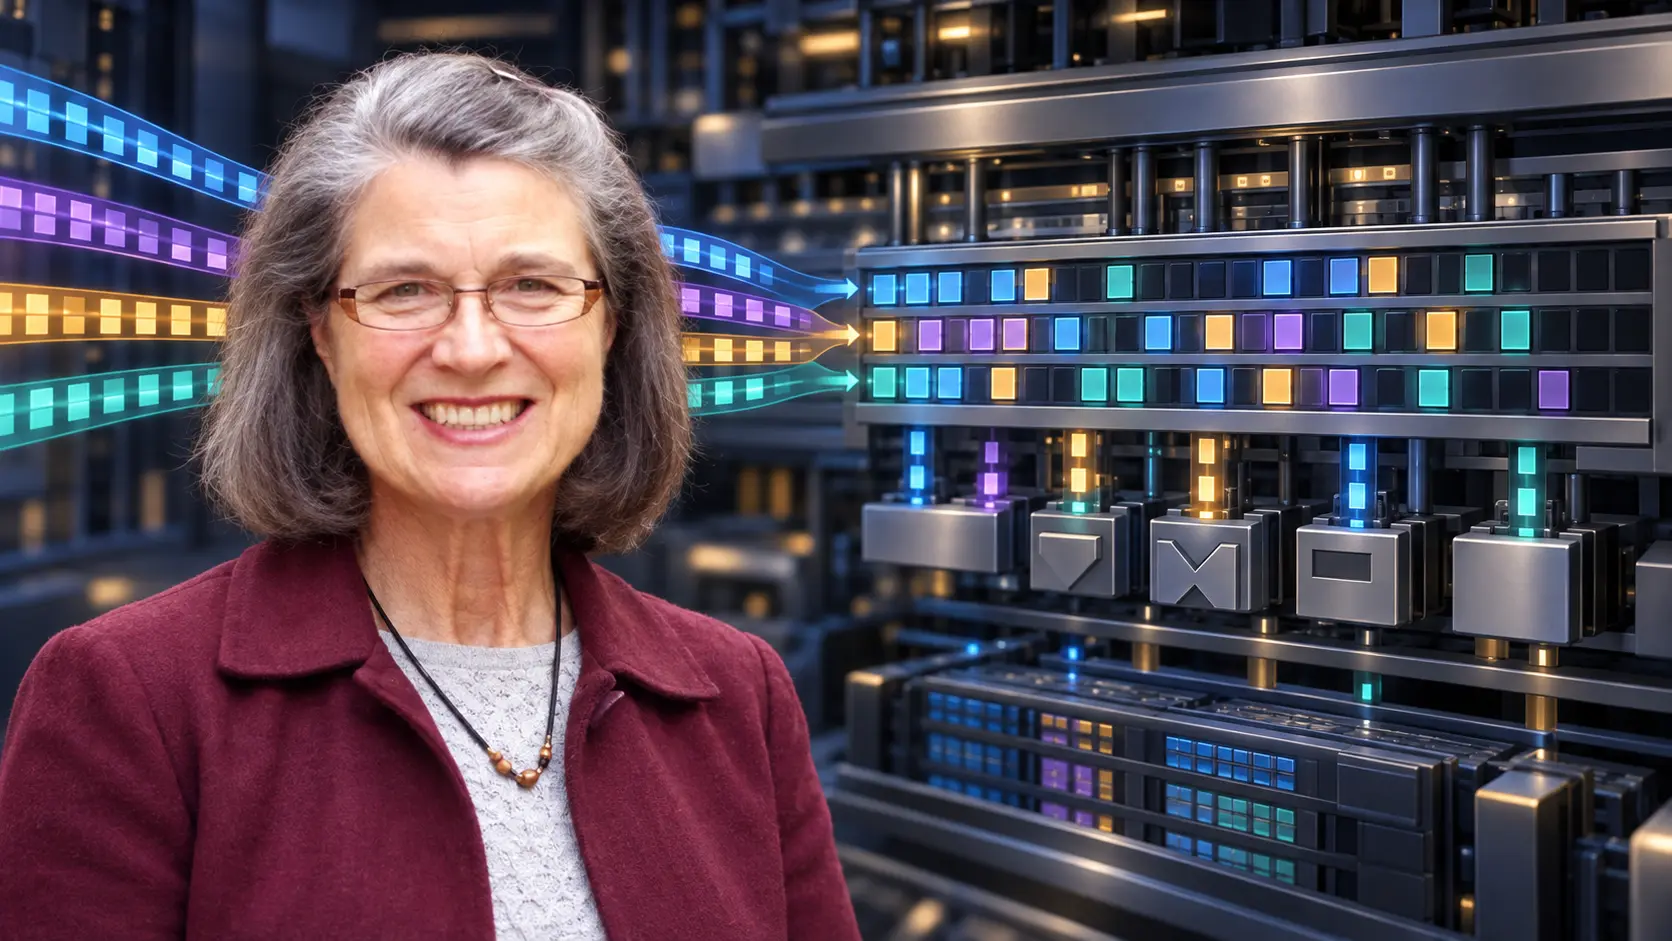
The simplest picture of a superscalar processor is a row of execution slots. A wide machine can issue several instructions per cycle, but only when one program exposes enough independent instructions at once. Branches, cache misses and true data dependencies break that supply. Some functional units work while others wait. Dean Tullsen, Susan Eggers and Henry Levy called the unused capacity horizontal waste when not all issue slots were filled in a cycle, and vertical waste when no instruction issued.
Their 1995 ISCA paper proposed a different allocation rule. Keep several hardware contexts ready and allow instructions from more than one independent thread to issue in the same cycle. The processor still has one shared set of execution resources. What changes is the pool of eligible work. One stalled thread need not dictate an empty slot if another has a ready instruction of the right kind.
That distinction separates three ideas often blurred in later product language. Instruction-level parallelism finds independent operations inside one thread. Thread-level parallelism supplies independent streams. Hardware contexts preserve the architectural state needed to keep those streams available. SMT combines them dynamically on one core; a chip multiprocessor instead gives different threads statically partitioned cores and resources.
What the 1995 experiment actually measured
The first study was a simulation, not a shipping processor. Its model began with a 300 MHz Alpha 21164-style design and widened it. A typical configuration had ten functional units and could issue as many as eight instructions per cycle, while maintaining as many as eight thread contexts. The authors used distinct SPEC92 programs in a multiprogrammed workload specifically to measure raw throughput without attributing gains to synchronization or application parallelization.
They also compiled the programs to maximize single-thread performance. That choice matters: a weak baseline would have exaggerated the apparent gain from SMT. Across the modeled configurations, the paper reported speedups of 3.2 to 4.2 over the wide superscalar baseline and reached 6.3 instructions per cycle in the best case. Its conclusion was carefully comparative: under the studied model, SMT could deliver roughly four times the throughput of the wide superscalar and twice that of fine-grained multithreading.
Those numbers do not promise four times the speed for one job. They describe completed work across a mix of programs. Nor do they prove a universal advantage over every multicore design, whose core count, memory hierarchy, frequency, power envelope and workload mix can differ radically.
Sharing creates a scheduler, not free capacity
Once several threads seek the same issue slots, the allocation policy becomes part of the machine's behavior. The 1995 paper compared strict-priority and fairer schemes. Aggregate throughput could remain similar while the relative speed of individual programs changed markedly. With eight threads, the lowest-priority program ran at only 55% of the speed of the highest-priority one in one experiment. Even the favored thread slowed by about 35% because caches, translation lookaside buffers and branch predictors were shared.
The result exposes SMT's control surface. Fetch policy decides which threads place instructions into the pipeline. Queue space, registers, execution units and memory bandwidth decide which instructions can progress. Shared caches and predictors introduce interactions that do not appear in a sum of isolated benchmarks. Throughput can rise while a particular request waits longer or makes less predictable progress.
From a powerful idea to an implementable machine
The 1996 follow-up widened the author circle to Tullsen, Eggers, Joel Emer, Levy, Jack Lo and Rebecca Stamm. It replaced part of the idealized model with mechanisms that could plausibly extend a conventional wide superscalar. One important contribution was instruction-count-based fetch selection: favor threads with fewer instructions already in the machine, rather than letting one context flood the shared window.
That design achieved 5.4 instructions per cycle and 2.5 times the throughput of a comparable superscalar with eight threads in the reported model, while adding less than 2% slowdown for single-thread execution. These remain simulated results, but they moved the question from “can shared issue work?” toward “which queues, fetch rules and register resources make it buildable?”
A 1997 University of Washington report then examined SPEC95 multiprogramming and SPLASH-2 parallel workloads. It reported about 6.2 instructions per cycle for multiprogramming and 6.1 for parallel programs at eight threads, while again documenting interference in shared caches, TLBs and predictors. The comparison with a modeled chip multiprocessor was not simply a victory lap: dynamic sharing could use otherwise stranded resources, while static partitioning offered a different isolation boundary.
Credit, commercialization and the limit of the label
The University of Washington project record names Eggers and Levy as faculty, Tullsen and Lo as students, and Emer and Stamm as Digital Equipment Corporation collaborators. That collective record matters. Eggers helped shape and test the architecture, but SMT was not the work of a solitary inventor. The sequence of papers also shows how the claim matured: first the opportunity, then an implementable organization, then broader workload analysis.
Intel's later Hyper-Threading brought the underlying principle into commercial processors. In 2010 the original ISCA paper received the conference's Test of Time recognition, and Eggers received the 2018 Eckert-Mauchly Award for outstanding contributions to simultaneous multithreaded processor architectures and multiprocessor sharing and coherency. Those honors establish influence, not a guarantee that enabling SMT improves every modern workload.
The disciplined conclusion is narrower and more durable. SMT changes the allocation boundary inside a core. It turns idle execution opportunity into contested shared capacity. Whether that is valuable depends on the machine, the workload mix and the metric that the operator is actually trying to improve.
Sources
- Simultaneous Multithreading: Maximizing On-Chip Parallelism (ISCA 1995)
- Exploiting Choice: Instruction Fetch and Issue on an Implementable SMT Processor (ISCA 1996)
- Simultaneous Multithreading: A Platform for Next-Generation Processors
- Converting Thread-Level Parallelism to Instruction-Level Parallelism
- University of Washington SMT project
- Susan Eggers faculty page
- UW announcement of the 2010 ISCA Test of Time Award
- 2018 ISCA Eckert-Mauchly Award announcement
- ACM Eckert-Mauchly Award record
- DOI record for the 1995 paper
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance