
Summary
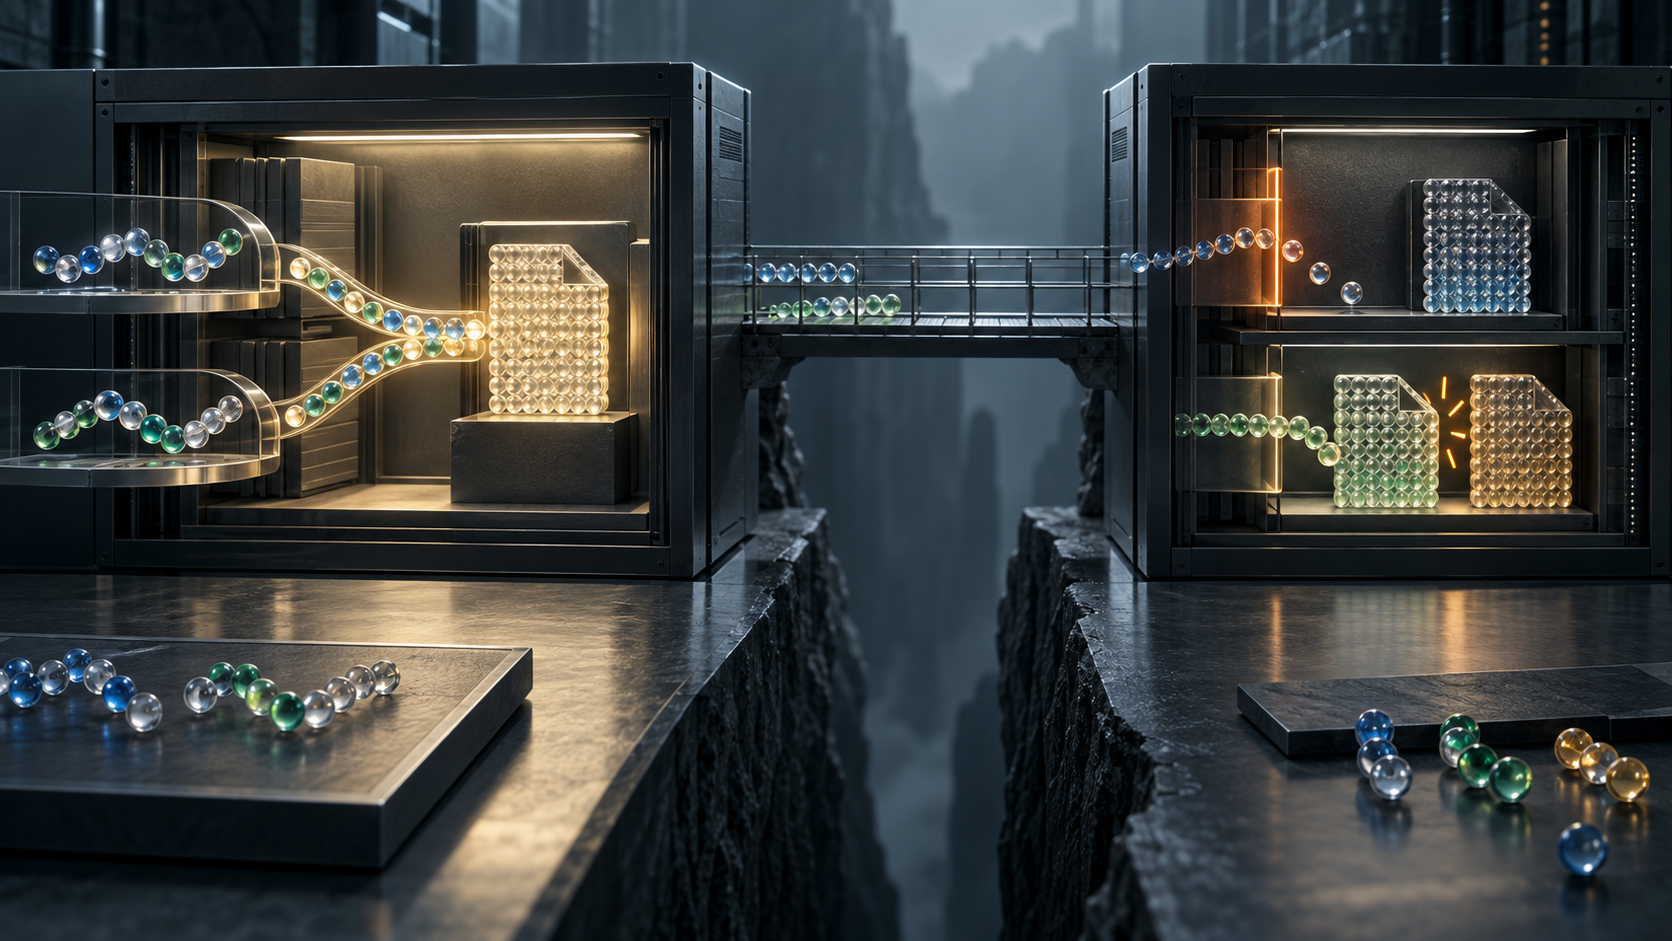
draft-ietf-nfsv4-internationalization-17documents several lawful ways an NFSv4 server can handle internationalized names, including opaque octet comparison and Unicode-aware equivalence. A client generally cannot infer the full rule, Unicode version or case policy from one successful lookup.- Before backup, replication, failover or migration, operators should capture a namespace-equivalence receipt: the bytes submitted, names returned, server and filesystem policy, capability evidence, collision tests and the unresolved limits of what was observed.
The success that hides the rule
Suppose a client asks an NFS server for a filename displayed as “café”. The server returns the intended file. Operationally, that is a success. Semantically, it is an incomplete experiment.
The visible word can be encoded with different Unicode sequences. One server might require the exact octets that created the directory entry. Another might consider canonically equivalent sequences to name the same object. A third might apply case-insensitive comparison, perhaps through an underlying filesystem rather than the NFS implementation itself. All three can return the same successful result for the test that happened to be run. They need not agree on the next spelling, on a directory enumeration, or after the data is copied elsewhere.
Revision 17 of the NFSv4 internationalization draft is unusually candid about this gap. Its recommendations are based largely on deployed behaviour rather than on older normative language having directed implementations. The document is an active Standards Track Internet-Draft, submitted to the IESG, with revision 17 posted on 11 September 2026 after IETF Last Call comments. It is not an RFC and does not prove deployment.
Its shepherd report says the internationalization text written for NFSv4.1 was not implemented as designed; major implementations instead converged on the NFSv4.0-style, UTF-8-unaware approach, while aware features have been limited and experimental. That history matters because interoperability rests on what systems actually compare, not on what an architecture once hoped they would compare.
Two legitimate namespaces can disagree
The draft separates UTF-8-unaware and UTF-8-aware behaviour. On an unaware filesystem, names are accepted as opaque byte strings. Component names must be compared octet by octet. Such a filesystem can carry names created in legacy encodings, and it cannot promise Unicode canonical equivalence because it does not interpret the bytes as Unicode characters.
An aware server has more choices. It may map a submitted name to a normalization form before storage. It may preserve the original name yet treat canonically equivalent forms as identical during lookup. It may also map case variants or compare them as equivalent. These choices can be influenced by the server, the backing filesystem and configuration; the draft treats materially different configurations separately for good reason.
Neither family is inherently evidence of a broken server. Exact-byte behaviour preserves a namespace that may contain arbitrary historical names. Unicode-aware behaviour can make names more intuitive to users who reasonably expect equivalent character sequences to resolve together. The governance problem begins when an operator treats the successful behaviour of one family as evidence that another family will reproduce it.
This is not a cosmetic problem. A filename is often a key shared among applications, backup catalogues, access-control rules, build systems and human procedures. If the key's equality relation changes, “the same file” can become two directory entries, two entries can collapse into one, or a name that was retrievable can become unreachable through the spelling stored by a client. The bytes still exist. The organisation has lost agreement about what they identify.
Capabilities reveal less than policy
NFSv4 exposes the fs_charset_cap attribute, but its useful signal is narrow. The current draft uses it to indicate a server that accepts only UTF-8 filenames. Historical use of FSCHARSET_CAP4_CONTAINS_NON_UTF8 was unclear; the draft says servers should complement that flag and clients should ignore it. If the attribute is unsupported, a client can probe with a non-UTF-8 name to learn something about acceptance.
That still does not reveal the full equivalence policy. The client cannot generally determine whether normalization is active, which Unicode version informs it, or precisely which case variants compare equal. Internationalized case mapping can depend on language and user preference, and the draft concludes that a general mechanism to communicate all of those choices is not ready for standardisation.
The resulting asymmetry is important. A client can observe outcomes but cannot necessarily discover the function that produced them. Ten successful lookups are ten samples, not a specification. A capability bit is not a namespace contract. Even a vendor document may describe the intended layer while the backing filesystem or mount configuration supplies the effective comparison.
Enumeration is not a substitute for lookup
A client might try to learn the namespace by reading the directory. That does not close the gap. A server may preserve one spelling in the directory while accepting an equivalent spelling during lookup. READDIR shows a returned name; it does not enumerate every query the server would treat as equivalent to that name.
The distinction also reaches caching. A client that caches a negative lookup under its own idea of name equality can retain “not found” after the server would have accepted an equivalent form. A client that skips a lookup because a READDIR result appears not to match can miss an object the server would return. The draft therefore asks clients to be prepared for normalization while warning them not to assume that it occurs. The careful position is operationally awkward because the missing rule is exactly what an aggressive cache would like to know.
Unicode evolution adds time to the problem. Canonical equivalence classes can gain members when new characters are encoded. The draft favours form-insensitive comparison over imposing one normalization form partly because filenames are long-lived. A namespace copied unchanged can therefore meet a different interpretation on a newer platform. Byte preservation alone is necessary for forensic fidelity, but it cannot guarantee behavioural fidelity.
Migration is a change of judge
Storage migrations are usually described as movement of data: copy blocks, preserve metadata, switch clients, verify counts. Names make the operation a transfer between judges. The source stack decided whether two requests were the same name. The destination stack will make that decision again, perhaps under a different Unicode library, filesystem, export option or case policy.
The dangerous test is merely to reopen a sample of familiar files. It preferentially exercises names that current users already know how to type and applications already know how to produce. It may not expose canonically equivalent pairs, invalid UTF-8 retained as legacy bytes, case collisions, characters added in later Unicode versions, or differences between stored names and accepted lookup forms.
A backup has the same exposure. A catalogue can record every byte and still restore into a namespace that refuses some names or merges distinctions the source retained. Replication can be worse because a silent collision may look like successful convergence. Failover can turn the policy shift into an outage: the standby contains the content, yet a workload cannot address it in the same way.
The namespace-equivalence receipt
For consequential moves, operators need a small, reviewable artefact that records the name semantics observed at the boundary. Call it a namespace-equivalence receipt. This is an editorial proposal, not a requirement of the Internet-Draft.
The receipt should identify the NFS protocol version, server implementation and version, backing filesystem where known, export and mount configuration, operating-system and Unicode library versions, and the time of the test. It should preserve submitted component names as exact bytes alongside a safe rendered view. The rendered form is for humans; the byte sequence is the evidence.
It should then record paired observations. Did canonically equivalent composed and decomposed sequences reach the same filehandle? Did case variants collide or remain distinct? What did LOOKUP return for each form, and what spelling did READDIR expose? Were non-UTF-8 octets accepted? What value, if any, did fs_charset_cap provide? Negative results need the same care as positive ones, including whether client caches were cleared or bypassed.
Collision testing must be non-destructive and performed in a controlled namespace. The aim is not to throw arbitrary names at production data. It is to build a corpus from names actually present, Unicode edge cases relevant to the organisation and destination-specific risks, then test source and destination under comparable conditions. The receipt should distinguish observed behaviour from vendor claims and from assumptions that could not be tested.
Finally, the receipt needs an acceptance decision. List collisions, rejected names and ambiguous cases; assign an owner; state whether names will be renamed, escaped, isolated or left under a compatibility layer; and preserve a reversible mapping. A migration approved with known exceptions is governable. A migration approved because a few lookups succeeded is merely optimistic.
The receipt does not promise universal portability. Symlink contents, for example, are opaque in a different way, and domain-name fields follow their own rules. Different NFS string types do not share one treatment. The value of the receipt is narrower and more useful: it tells the next operator exactly which equality claims were tested, which environment supplied them and where uncertainty remains.
Evidence boundary
The security concern is not confined to inconvenience. RFC 6943 explains how inconsistent identifier comparison can produce false positives, false negatives, denial of service and, in some systems, elevation of privilege. That does not mean the NFS draft documents an incident, and this article makes no such claim. It means name equivalence belongs in a security and continuity review when filenames participate in authorisation, policy or executable paths.
The practical boundary is simple. A successful lookup proves that a particular server-side namespace resolved a supplied byte string under the behaviour operating at that time. It does not establish a universal character identity, a portable equality relation or a guarantee that another system will make the same decision. The filename may look like a label. In a distributed filesystem, it is also a policy result.
Sources
- NFSv4 internationalization draft — current Datatracker record
- Draft history
- Revision 17 text
- Revision 16 text
- Official revision 16–17 diff
- NFSv4 Working Group
- RFC 7530 — NFS version 4 protocol
- RFC 8881 — NFS version 4 minor version 1
- RFC 3629 — UTF-8
- RFC 5890 — IDNA definitions
- RFC 5891 — IDNA protocol
- RFC 6943 — Identifier comparison security
- Unicode Standard Annex #15 — normalization forms
- Unicode 17.0 case-folding data
- Heng Lu — The Policy Mirror
- Heng Lu — Minimum initial specification, localized future decision
- Heng Lu — Why reality, not advocacy, is the product
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance