
Summary
Retry-Afterexpresses when a user agent ought to make a follow-up request, not when recovery is guaranteed.- The field can be an absolute HTTP date or a delay in seconds, so clocks and parsing are part of the evidence.
- A
503or429describes the triggering response; it does not reveal future capacity or every dependency’s state. - Operators need a retry-admission receipt that joins the instruction to fresh health evidence and the actual follow-up outcome.
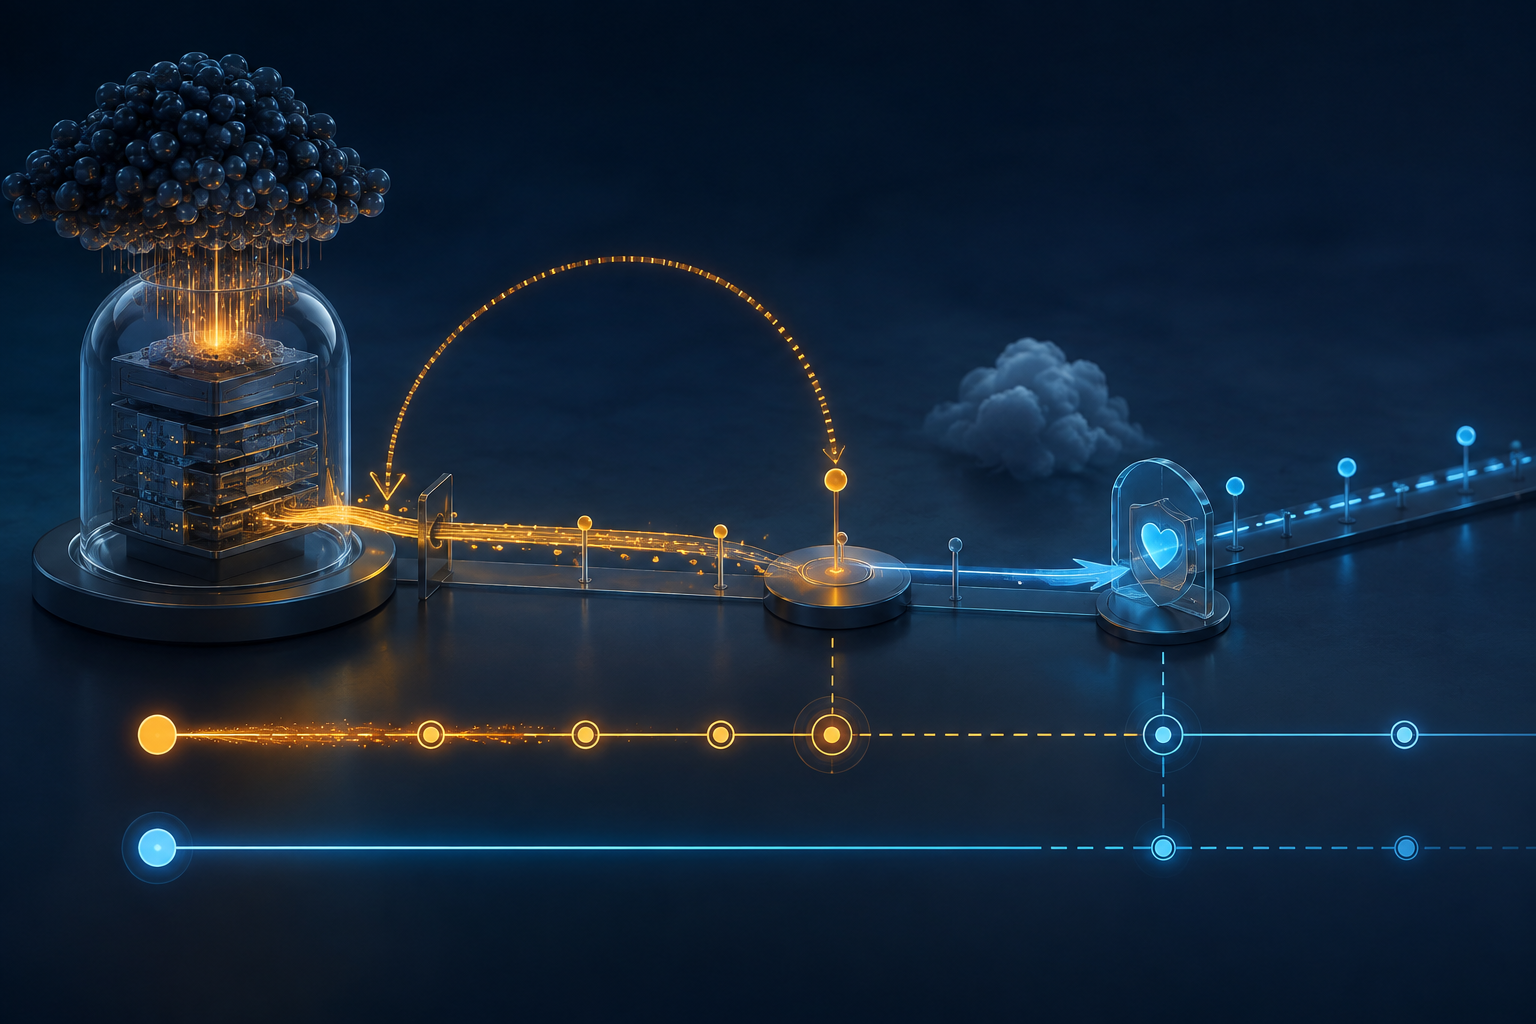
Imagine a recovery controller receiving 503 Service Unavailable with Retry-After: 120. It holds every request, draws a green line two minutes ahead, and schedules the entire queue for that second. The incident is marked resolved before a new request has succeeded. Two minutes later the origin is still constrained, an upstream dependency is unavailable, and the synchronized retry wave extends the overload.
The header was valid. The recovery conclusion was invented.
RFC 9110 defines Retry-After narrowly: it indicates how long a user agent ought to wait before making a follow-up request. A server can send it with 503 to suggest when retrying would be appropriate. In a redirect response, it can indicate how long the user agent ought to wait before following the Location value. Neither use turns the stated time into a forecast of service health.
The field has two forms. An HTTP date names a point in time; a delay value names a non-negative number of seconds after receipt. That difference matters. A date depends on clock interpretation. A delay depends on when the response was received and how intermediaries, queues, retries, and local timers treat elapsed time. Preserving only the rendered deadline discards the original instruction and makes later audit ambiguous.
The status code also has a boundary. RFC 9110 describes 503 Service Unavailable as a temporary inability caused by overload or scheduled maintenance. The server may suggest a retry time, but the specification does not require every overloaded server to use 503, nor does it state that the limiting condition will end at the suggested moment. Recovery can be earlier, later, partial, regional, identity-dependent, or blocked by a different component.
RFC 6585 gives 429 Too Many Requests a related but distinct role. A response may carry Retry-After to tell the client how long to wait. Yet the RFC deliberately leaves the way requests are counted and users are identified to the server. One token, account, address, route, tenant, or edge may have a different limit from another. A timer detached from that scope cannot establish that the next request will be admitted.
Intermediaries add another boundary. The response might come from an origin, gateway, reverse proxy, CDN, API manager, or local client component. The observation proves that this actor returned this instruction for this request at this time. It does not automatically prove which underlying resource was saturated or whether another path will receive the same advice.
Client behaviour is part of the outcome. If thousands of workers receive the same delay and all retry at the boundary, an instruction intended to reduce pressure can coordinate a new spike. Jitter, exponential backoff, concurrency limits, cancellation, and retry budgets are client-side controls. They should not be confused with the server’s recovery state, but they must be preserved when judging whether the exchange was handled safely.
The useful evidence object is a retry-admission receipt. It records the triggering request and response, observation point, status, raw Retry-After value, whether it was a date or delay, receipt time, parsed not-before time, clock source and any age introduced by an intermediary. It binds the instruction to the applicable account, token, route, tenant or other rate-limit scope without storing secrets.
The receipt then records the client decision: backoff algorithm, jitter, retry budget, concurrency cap, cancellation state and actual dispatch time. Immediately before admission it adds fresh service evidence: health checks relevant to the requested operation, available capacity, dependency state, authorization context and the component making the admission decision. Finally it stores the follow-up status, representation or transaction result and timing.
That separation permits honest dashboards. “Retry permitted after 120 seconds” is a scheduling state. “Health probe passed” is an observation. “Request admitted” is a control decision. “Transaction completed” is an outcome. They may appear together, but one must not manufacture the next.
Sources
RFC 9110 — HTTP Semantics; RFC 6585 — Additional HTTP Status Codes.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance