
Summary
Meta published the original V-JEPA video representation research and checkpoints on 15 February 2024. The training task predicted masked target features from visible video context without text, human labels, a pretrained image encoder, negative examples or pixel reconstruction. That isolation made the experiment informative, but did not make the resulting representation self-validating or universally meaningful.
Reported downstream results kept the backbone frozen while training lightweight task-specific probes. Every score therefore remained attached to an exact checkpoint, dataset, resolution, sampling recipe, probe and metric. The release was a non-commercial research artefact, not a captioner, video generator, autonomous planner, product or retroactive container for later V-JEPA 2 capabilities.
The event is the original February 2024 release
Meta published the original V-JEPA research and checkpoint collection on 15 February 2024. That date is the first operational control because the same family name later appeared beside materially different research. This article concerns the first video representation release only. It does not include later language alignment, action-conditioned prediction, robot planning, later checkpoints, later products or later commercial terms.
The narrow boundary protects the meaning of every statement that follows. A research family can change its objective, data, interfaces, evaluation and licence over time. If those revisions are treated as one continuous object, a later demonstration can be misreported as a capability of an earlier checkpoint. A correct receipt identifies the release before it discusses the method.
The original artefact was a collection of encoders and associated research configurations. It was not a hosted assistant, an application programming interface or a finished operational service. A user could not hand it an ordinary business question and receive an accountable answer. Researchers had to choose a checkpoint, prepare video clips, construct an evaluation path and interpret representations through another component.
That distinction is not a semantic technicality. Products normally include authentication, data handling, user interfaces, monitoring, support and defined decision rights. A research checkpoint supplies none of those controls by itself. Describing a checkpoint as a product skips the systems that determine whether video is lawful to process, whether an output is reliable and who may act on it.
The safest headline is therefore modest. V-JEPA offered evidence that masked feature prediction could produce useful video representations. The release did not prove that one model understood every physical event, could explain its representations or could plan actions. Preserving that modest claim makes the research more useful because it separates what was tested from what remained future work.
Masked feature prediction defined the task
V-JEPA divided a video into visible context and masked target regions. A context path represented the visible portion, while a predictor estimated a representation for the hidden target. Training compared features in a latent space. It did not require the model to draw the missing frames or reproduce every pixel that a viewer would expect to see.
This objective changes the error surface. Pixel reconstruction can reward exact colour, texture, lighting or camera noise even when those details do not help a downstream task. Feature prediction asks whether the visible context supports a useful abstract target. The choice may encourage stable representations, but it also means the prediction cannot be judged simply by looking at a generated image.
A latent target is not a sentence, label or visible forecast. It is a numerical representation shaped by the encoders, masks, predictor and training data. Two models can encode similar clips differently while supporting comparable probe results. The absence of a human-readable output makes careful evaluation more important, not less, because intuition cannot directly inspect what every coordinate means.
The masking policy is part of the artefact. Which regions are visible, which are hidden and how those choices vary across space and time influence what the predictor must learn. A deployment team cannot replace those choices casually and still claim equivalence with the published evidence. Masking, clip preparation and preprocessing belong in the reproducibility receipt.
The method also does not certify that the representation captures causal structure. Predicting a target feature may exploit motion regularities, object appearance, camera patterns or dataset shortcuts. Useful performance on selected tasks is evidence about those tasks. It is not proof that the model has a complete, faithful or human-like account of the physical scene.
Feature prediction is not video generation
The release is sometimes described with language that sounds visual, such as predicting hidden parts of a video. The actual training comparison occurred in representation space. V-JEPA did not need to generate a photorealistic missing frame for the objective to succeed. A statement that it predicted features must not be shortened into a claim that it generated future video.
That difference matters when evaluating quality. A video generator can be reviewed for visible continuity, artifacts and prompt adherence. A representation encoder needs tests that connect embeddings to defined downstream tasks. The two systems may share video inputs, but their outputs, risks and validation methods differ. A strong encoder result is not evidence of a strong generative model.
A visualisation built around representations would add another model or rendering procedure. That auxiliary component can help people explore what information may be present, but its images would not be the raw V-JEPA output. The renderer would bring its own training data, errors and choices. Any illustration must clearly separate the encoder from the device used to make latent information visible.
The same rule applies to future prediction. A representation inferred from context may support a task concerned with motion, yet it does not automatically specify a calibrated probability for the next event. A task head, labelled evaluation and decision policy are still required. Without them, the embedding remains evidence to be interpreted rather than a forecast ready for action.
Operational documents should therefore use precise verbs. The model encoded visible clips and predicted masked target representations. Probes assessed selected information in the frozen representation. It did not caption, narrate, simulate, reconstruct, plan or execute. Those verbs keep the article aligned with the artefact rather than with a broader story about world models.
The training isolation was informative but bounded
Meta reported that the original pretraining did not use text, human labels, a pretrained image encoder, negative examples or pixel-level reconstruction. That isolation helped test whether video feature prediction alone could produce reusable representations. It reduced several obvious channels through which semantic supervision might enter the system, making the training objective easier to study.
The result does not mean humans disappeared from the process. Researchers selected the public datasets, architecture, masks, clip sampling, optimisation, compute and evaluation tasks. They decided which checkpoints to save and which results to report. Self-supervised describes how training targets were derived; it does not mean the model established the validity of its own data or conclusions.
Excluding negative examples also has a specific meaning within the training design. It should not be expanded into a general claim that the system never encounters a negative case or cannot learn contrasts. The published objective and representation geometry determine what information appears. A concise receipt records the exclusion without turning it into an unsupported theory of everything the model learned.
Likewise, the absence of a pretrained image encoder concerns the reported starting point. It does not erase the influence of video selection, augmentation or architecture. Nor does it establish that the resulting representations are unbiased. A model can learn stable shortcuts from unlabelled data, and a downstream probe can amplify those shortcuts when trained on labelled examples.
The most useful interpretation is experimental. The researchers isolated a training recipe and showed that it supported selected frozen-backbone evaluations. That finding can guide further work. It does not transfer automatically to a private video archive, a different clip sampler, a different checkpoint size or a consequential application with a different definition of error.
About two million videos still require provenance controls
The research used about two million videos assembled from public datasets. Scale can broaden the range of visual patterns available during training, but the word public is not a universal licence. Each contributing dataset can have its own collection context, permissions, subjects, geography and representation gaps. The mixture therefore needs an inventory rather than a single blanket label.
A publicly downloadable clip can still show identifiable people, private places or activity captured under expectations that differ from model training. Legal permission and ethical suitability are separate questions. An organisation reusing a checkpoint should not assume that a source dataset’s availability answers consent, retention or downstream-purpose questions for its own operational videos.
Representation also matters. A large corpus can remain concentrated in common camera styles, popular activities, particular regions or well-lit scenes. Rare events, low-quality footage and culturally specific actions may be underrepresented. Aggregate probe accuracy can hide these gaps. A local test needs samples from the conditions and populations that will actually bear the consequences.
Data lineage is important even when a team never retrains the encoder. A checkpoint carries patterns learned from its mixture. If a probe appears to work unusually well or poorly in one environment, dataset overlap or mismatch may be part of the explanation. A governance record should preserve the checkpoint’s data statement alongside local evaluation results.
Private-video use adds another layer. The organisation must define who may submit clips, how long they are retained, whether faces or locations need minimisation, who can inspect derived embeddings and whether those embeddings can be linked back to individuals. The research release does not answer these policy choices; they belong to the deploying institution.
A frozen backbone still has a trained probe
Meta evaluated the learned representations by keeping the backbone frozen and training lightweight task-specific probes. Freezing is useful because it asks whether information can be extracted without changing the representation encoder. It also reduces one source of variation. But it does not mean the entire evaluation involved no training, labels or task-specific adaptation.
The probe converts a representation into outputs defined by an evaluation task. Its architecture, training split, optimiser, seed and stopping rule can affect the result. Labels enter through that probe training even when they did not enter representation pretraining. A claim about frozen features must therefore name both the frozen checkpoint and the trained probe.
This separation is operationally valuable. A team can test one encoder with several probes to see which information is readily accessible. Yet each probe creates a new acceptance surface. A probe trained for one action vocabulary cannot be assumed to identify another vocabulary, and a probe trained on curated clips may fail on continuous operational footage.
The word lightweight describes relative complexity, not automatic safety. A small classifier can still be overconfident, unstable under distribution shift or unfair across groups. Its errors can trigger serious outcomes if the system grants it authority. The appropriate control is a local error analysis and escalation policy, not confidence derived from the probe’s size.
A complete receipt therefore rejects the phrase “no adaptation” when it hides probe training. A more accurate statement says that the representation backbone stayed frozen while a task-specific probe was trained. This wording preserves the research result and prevents a reader from believing that raw embeddings directly emitted human-readable labels without additional supervision.
Headline scores belong to exact configurations
The reported results were tied to specific checkpoints, datasets, input resolutions, clip samplers, probes and evaluation procedures. Any one of those dimensions can change a score. Naming only the family as V-JEPA removes the information required to reproduce the result. A benchmark statement is complete only when its configuration and denominator travel with it.
Resolution affects visible detail and compute. Clip sampling determines which moments are available to the encoder. Preprocessing can alter motion and appearance. The probe architecture and labelled split determine how representations become categories. Evaluation views and aggregation can change the final metric. These are not minor implementation details; they are parts of the measured system.
A vendor research score is evidence, but its scope is narrow. It can support a claim that a named configuration performed a named evaluation under a stated protocol. It cannot establish reliable detection of every event, safe behaviour in every camera environment or superiority under an organisation’s own latency and cost constraints.
Comparisons need equal treatment. If two encoders use different input sizes, sampling budgets or probes, the headline numbers may combine representation quality with evaluation resources. A responsible comparison either normalises those choices or explains the difference. It also reports uncertainty and per-class failures rather than relying only on one aggregate.
Local acceptance should start from the published setup and then test deliberate deviations. If a team changes the checkpoint, sampler or probe, it creates a new configuration that needs its own result. The published score remains a reference point, not a guarantee. This discipline prevents benchmark reputation from substituting for operational evidence.
Embeddings are evidence, not explanations
V-JEPA produced representations that could support downstream tasks. An embedding can encode patterns useful for distinguishing actions or appearances, but it does not explain in ordinary language why a probe chose a class. The numerical vector is not a rationale, a confidence statement or a record of causal reasoning.
A probe can discover a shortcut that correlates with labels in its training data. Background, camera motion or framing may become predictive without matching the intended concept. Frozen features do not prevent this. Teams need controlled tests that vary suspected shortcuts while holding the target event constant, then inspect whether decisions remain stable.
Nearest-neighbour examples or visualisations may help analysts explore a representation, but they remain diagnostic tools. They depend on distance metrics, selected reference items and auxiliary rendering choices. They should not be presented as a faithful internal explanation. A user needs a calibrated account of what was tested and what remains unknown.
Uncertainty is also layered. The encoder may react to an unfamiliar clip, the probe may assign a class, and a downstream policy may convert that class into an action. Each step needs its own confidence and abstention rule. A single probe probability cannot capture uncertainty in data rights, distribution shift or operational consequences.
The right editorial conclusion is not that representations are opaque and therefore useless. It is that their value comes through bounded tests. An embedding can reduce labelled-data needs or improve a defined task while still requiring explicit evidence. Utility and accountability are compatible when the receipt names the exact path from clip to decision.
The encoder was not a language interface
The original release did not accept natural-language questions and did not return captions. It learned visual representations from video. A language interface would require additional models, paired data, vocabulary choices and evaluation. Adding those components later would create a different system and a different evidence record.
This boundary matters because words such as understanding can invite conversational interpretations. A strong representation may preserve information about motion or appearance without providing names, explanations or dialogue. A downstream probe can map features to a fixed label set, but that is not the same as open-ended language grounding.
If an organisation connects an encoder to a language model, the combined system inherits risks from both sides. The connector may misalign features with words, the language model may invent detail, and the user may assume the prose came directly from the video. The original V-JEPA research cannot validate that composite pipeline.
A clean system diagram should show video ingestion, preprocessing, the exact encoder, the downstream probe or adapter, any language component and the final policy. Logs should preserve versions and inputs at each boundary. Without that structure, an error can be attributed vaguely to “the model” even though several independent components contributed.
The article therefore avoids claims that V-JEPA described scenes, answered questions or explained actions. It could support research into representations that later systems might use. That future possibility is not evidence that the February 2024 artefact already delivered a multimodal assistant or a reliable account of arbitrary video.
The encoder was not a planner
Meta’s February account discussed physical-world modelling and future planning research. Future direction is not delivered capability. The original checkpoint did not select goals, compare action sequences, control a robot or accept responsibility for an external state. A representation may become an input to planning, but it does not become a planner by association.
Planning requires an action space, objective, transition assumptions, feedback and a policy for uncertainty. It also requires controls for interruption, physical safety and human authority. None of those elements follows automatically from a video embedding. A separate system must define them, test them and document how encoder error affects possible actions.
The distinction is especially important in robotics. A classification probe may recognise a pattern in a recorded clip without predicting how a new action will change the world. Offline benchmark evidence does not establish closed-loop stability. A robot-control claim would need physical experiments, safety constraints, recovery behaviour and a different licence and artefact record.
Later V-JEPA 2 materials explored capabilities outside this boundary. Those demonstrations used later data, objectives, checkpoints and evaluations. Their existence confirms why chronology matters. They cannot be applied backward to make the original release action-conditioned, language-linked or commercially available under later terms.
For the first release, the strongest supported statement is about representation learning. The training objective produced features that supported selected probes. Planning remained future work. This sentence may sound less dramatic than a world-model headline, but it is more useful to an engineer deciding what evidence must be added before any real-world action.
Non-commercial terms define a separate gate
Meta described the original V-JEPA release under non-commercial Creative Commons terms. A research download is not general commercial permission. Teams must inspect the exact repository revision, checkpoint and licence text that govern the files they intend to use. A family name or later announcement cannot replace that review.
Licence scope and technical capability are different questions. A checkpoint may work in a test while remaining unsuitable for a commercial service. Conversely, permission to study an artefact does not certify its accuracy or safety. The acceptance process should keep legal, technical and operational gates separate so that one approval is not mistaken for all three.
Derivative systems can add complexity. A probe, adapter or combined model may carry its own code and data terms. Training on private clips creates another rights surface. Distribution of embeddings may raise questions not answered by the checkpoint licence. A legal receipt should list each artefact rather than assigning one blanket label to the stack.
Later V-JEPA 2 statements about commercial use do not relicense the earlier release. Chronology and file lineage determine which terms apply. A team cannot select a convenient later headline while using an earlier checkpoint. It needs the actual licence attached to the exact bytes and a documented decision about the intended use.
The governance consequence is straightforward. Keep checkpoint SHA, repository revision, licence path and review decision beside the evaluation. Recheck the terms before distribution or a change in purpose. If the evidence cannot identify the exact artefact, the commercial decision should fail closed rather than assume that later openness applies backward.
A private-video workflow adds controls outside the model
A production video pipeline begins before the encoder. It needs a lawful input source, a purpose, access control and retention policy. It should minimise unnecessary frames and identifiers. These controls are not supplied by V-JEPA. They belong to the organisation operating cameras, archives or user uploads.
Preprocessing then determines clip length, frame rate, crop, resolution and normalisation. Those choices affect the representation and may remove context needed for a decision. The system must record them and test whether operational conditions match evaluation conditions. Silent preprocessing changes can invalidate an otherwise reproducible checkpoint result.
After encoding, embeddings need protection. They can preserve information about activities and appearance even when they are not ordinary images. Access should be limited, linkage risks reviewed and retention justified. A claim that the system stores only features is not a privacy guarantee. Threat models should consider reconstruction, matching and secondary use.
The downstream probe needs calibrated thresholds and an abstention path. Rare or unfamiliar clips should not be forced into a familiar class. A queue for human review should preserve enough context for a person to assess the case without exposing unrelated footage. Reviewers need authority to reject the automated suggestion and correct the record.
Finally, the policy that consumes a probe output must be explicit. A label may support search or prioritisation without authorising a consequential action. The receipt should state what the model can suggest, what it cannot decide and who owns the final decision. This separation prevents a research representation from acquiring authority through an undocumented integration.
Distribution shift is a system-level test
Video conditions vary by camera, compression, lighting, viewpoint, motion and social context. A representation trained on public datasets can face an operational distribution that is materially different. Teams should test ordinary cases, rare cases and known edge conditions from the intended environment before relying on a probe.
Shift can enter through time as well as place. Cameras change, workflows change and users adapt. A model that performed well during initial evaluation may drift as inputs evolve. Monitoring should track data characteristics, abstentions, per-class errors and human overrides, not just aggregate throughput.
Ground truth for video can be disputed. An action may begin before a clip, continue after it or be ambiguous from one viewpoint. Labels need definitions and adjudication. A high score against weak labels does not establish reliable understanding. The evaluation receipt should document how disagreements were resolved and which cases were excluded.
Subgroup analysis must be tied to the application rather than borrowed from a generic benchmark. If people can be affected, the team should identify relevant groups and conditions, assess uneven errors and define mitigations. Public training data does not guarantee balanced coverage, and a frozen backbone does not freeze away representational harm.
A fail-safe system treats unexpected shift as a reason to abstain or reduce authority. It does not use a vendor research result as permission to continue. Monitoring must connect to an operational response: pause, route to review, roll back a probe or restrict the use. Metrics without decision rights are only observation.
Human review needs real authority
Human review is meaningful only when the reviewer can see relevant evidence, understand the model’s limited role and reject its suggestion. A rubber-stamp step after an automated decision does not create accountability. The workflow should give the reviewer time, context and a clear route to request more information.
The reviewer should know which checkpoint and probe produced the suggestion, what the label means and how the local test performed. They do not need to inspect every internal vector. They do need the limits that affect the decision, including known blind spots, confidence calibration and whether the clip is outside the tested distribution.
Consequential use also needs an appeal or correction route. If a probe label changes access, employment, safety handling or another material outcome, the affected process must allow error to be challenged. Corrected cases should improve monitoring and, where appropriate, future probe training without silently changing the original record.
Authority should be separated from convenience. A search tool may rank clips while leaving final classification to an analyst. A quality system may flag an event while requiring a supervisor to approve action. The receipt should describe these boundaries in operational verbs so that a suggestion cannot be mistaken for an authorised conclusion.
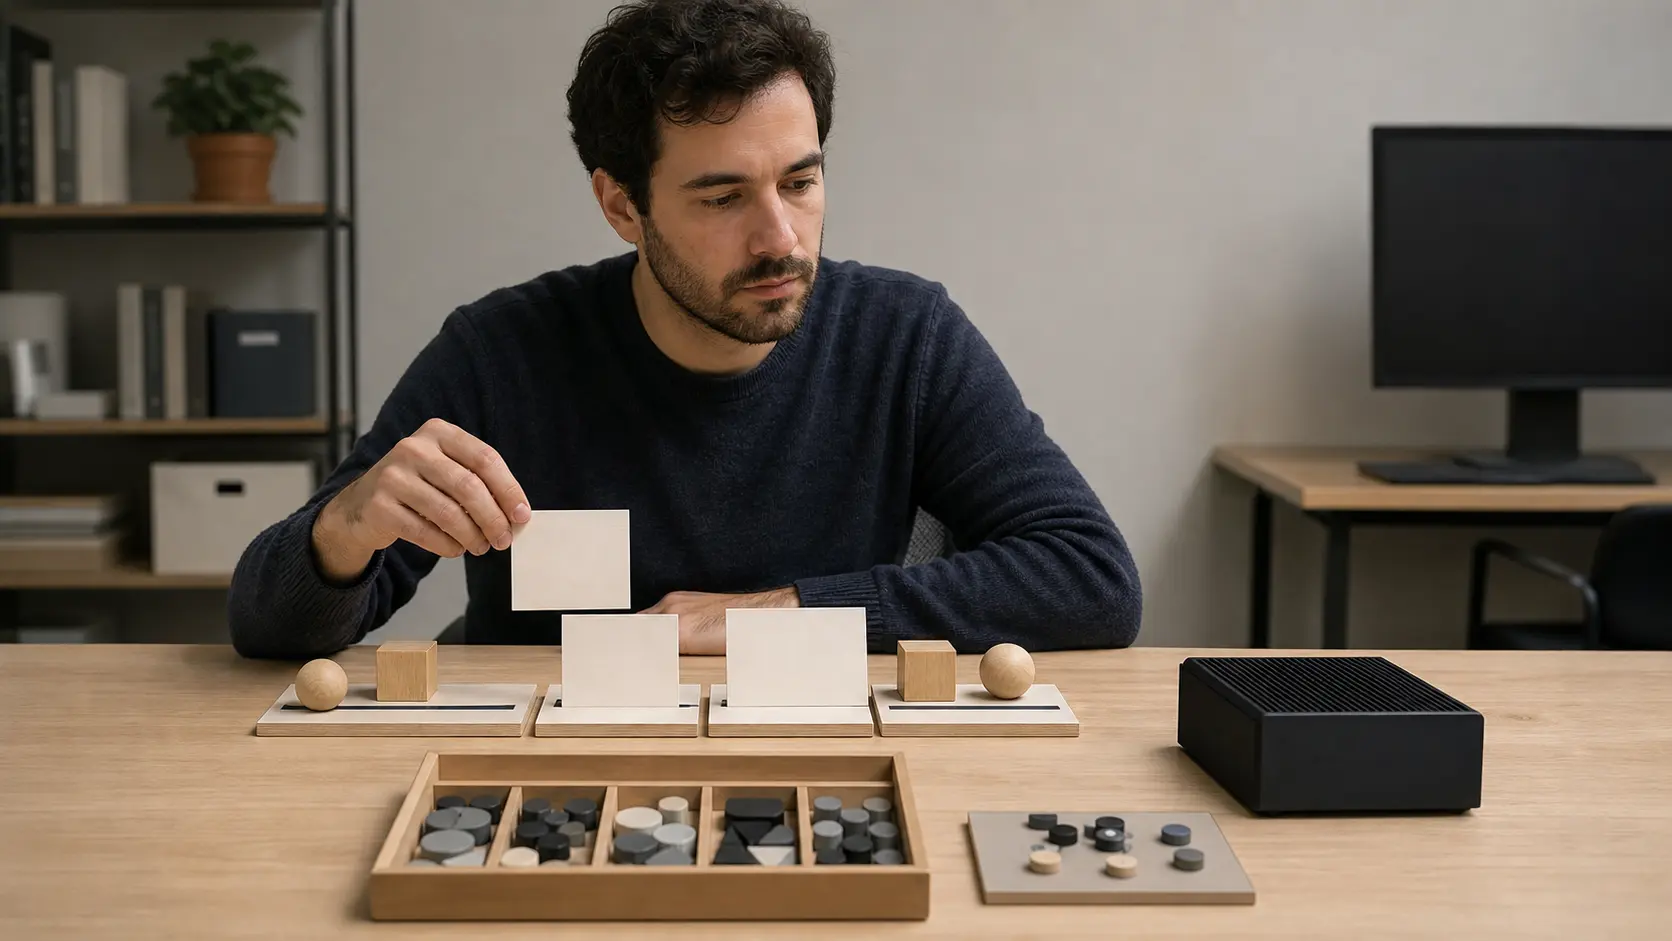
The generated featured image reflects this principle without claiming evidence. It shows a fictional reviewer, covered motion cards, an unchanged module and a separate probe board. Those props communicate review boundaries. They are not Meta staff, a Meta facility, V-JEPA output, a dataset, a benchmark or proof that the system is accurate.
Reproducibility begins with exact artefacts
A reproducible V-JEPA evaluation starts with the checkpoint file hash and repository revision. It records model size, input resolution, clip length, frame sampling, crop and normalisation. These values define the encoder input and prevent a later team from attributing a changed configuration to the published result.
The probe receipt then records architecture, labelled training data, seed, optimiser, stopping rule and evaluation views. It states whether the backbone stayed frozen and confirms which parameters changed. This separates representation evidence from probe performance and makes it possible to reproduce a failure without guessing which component moved.
Metrics need denominators and error slices. Overall accuracy alone cannot show rare-class performance, confusion between similar actions or behaviour under low-quality video. The test should include uncertainty, per-class errors, representative operational clips and cases selected specifically to challenge shortcuts.
Compute and latency should be measured for the full path, not borrowed from a partial component. Video decoding, sampling, encoder inference, probe inference, storage and review queues all contribute. A research score says nothing about service capacity or cost unless those parts were measured under the intended operating conditions.
The receipt also records licence and data decisions. It names the exact non-commercial terms, the purpose of evaluation, the lawful source of local clips, retention, access and deletion. Technical reproducibility without lawful data handling is not operational readiness. Both sets of evidence must remain connected to the same configuration.
Acceptance should test the whole path
The first acceptance question is identity: is this the original February 2024 checkpoint and not a later V-JEPA 2 artefact? The second is permission: do the exact licence and data terms allow the proposed evaluation? The third is configuration: does the local pipeline match the recorded sampler, preprocessing and probe?
The next question is relevance. Does the test data represent the environment, people, activities and camera conditions in scope? A convenient benchmark may not answer the operational question. The team should define unacceptable errors before testing, then include cases that expose those errors rather than optimise only for an average.
Acceptance also needs negative capability statements. The system does not caption, generate video, plan actions or provide a natural-language explanation. It does not inherit later commercial terms. Writing these exclusions into the receipt helps reviewers detect scope creep when another component or marketing phrase is added.
A decision table can connect results to authority. Low-risk retrieval may proceed with monitoring, ambiguous cases may require review, and high-impact outcomes may prohibit automated action entirely. The choice depends on consequence and evidence, not on the prestige of a research release. Human escalation must be tested like any other system component.
If any binding is missing, the package should fail closed. An unknown checkpoint, unpinned licence, unrepresentative dataset, undocumented probe or absent correction route is not a minor paperwork gap. It prevents the team from knowing what was tested and what authority the result should receive.
The practical value is a bounded representation layer
V-JEPA’s contribution does not require an inflated world-model claim. The research showed that latent feature prediction, under a carefully isolated recipe, could produce representations useful to selected frozen-backbone probes. That result offers a method to study and a checkpoint family to evaluate under explicit conditions.
For an engineering team, the representation layer can be treated as one component. It may reduce the labelled data needed for a defined probe or offer a reusable starting point across tasks. The benefit must be measured locally against compute, data, licence and error costs. Reuse is an empirical question, not a property guaranteed by the family name.
For a governance team, the release illustrates why boundaries matter. A model can be technically interesting while lacking product controls, commercial permission and decision authority. Probe-based evidence can be meaningful while remaining configuration-specific. Public data can support research while leaving provenance and representation questions unresolved.
For an editor, precise language is the control. Say predicted features, not generated video. Say frozen backbone plus trained probe, not no adaptation. Say original non-commercial research release, not a commercially unrestricted product. Say later V-JEPA 2 capabilities are excluded, not implied by the family name.
These distinctions lead to a durable conclusion. The original V-JEPA release supplied evidence about a representation-learning objective. It did not remove the need to identify artefacts, validate probes, govern video, respect licences or assign human authority. That bounded account is strong enough to support responsible evaluation without pretending the research had already become a finished system.
Change control must keep the evidence local
A later improvement does not silently upgrade an accepted configuration. Changing the encoder, probe, clip sampler, resolution or preprocessing creates a new system version. The owner should record the change, explain why existing evidence still applies and rerun the tests touched by it. Version control prevents an operational label from surviving after the measured path has changed.
The same principle applies to data. A new camera, geography, activity class or retention purpose can alter both performance and governance. The team should assess whether the prior validation remains representative. If it does not, authority should remain restricted while a fresh dataset and human review establish the new boundary.
Monitoring must retain the original denominator. An increase in correct alerts can look positive while false alarms grow faster because traffic changed. Reviews should compare rates, volumes, abstentions and overrides. They should also preserve examples of consequential errors so that an average cannot hide a failure with an unacceptable human impact.
Retirement is part of control. If a checkpoint licence becomes unsuitable, an unsupported probe drifts or a safer process replaces the model, the organisation needs a way to stop new use and delete unneeded derived data. A research artefact should not persist indefinitely merely because its integration once passed a test.
Finally, communications must follow the receipt. Product descriptions, dashboards and operator training should use the same bounded claims as the evaluation. If a screen calls an embedding a verified event, the interface has exceeded the evidence even if the underlying model file is unchanged. Governance includes the words and actions placed around the representation.
Sources
- Meta AI Research, original V-JEPA research publication, 15 February 2024: https://ai.meta.com/research/publications/revisiting-feature-prediction-for-learning-visual-representations-from-video/
- Meta FAIR, official JEPA repository and original V-JEPA checkpoint context: https://github.com/facebookresearch/jepa
- Bardes and co-authors, original V-JEPA paper: https://arxiv.org/abs/2404.08471
- Meta, contemporaneous February 2024 company account and future-work boundary: https://ai.meta.com/blog/v-jepa-yann-lecun-ai-model-video-joint-embedding-predictive-architecture/
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance