
Summary
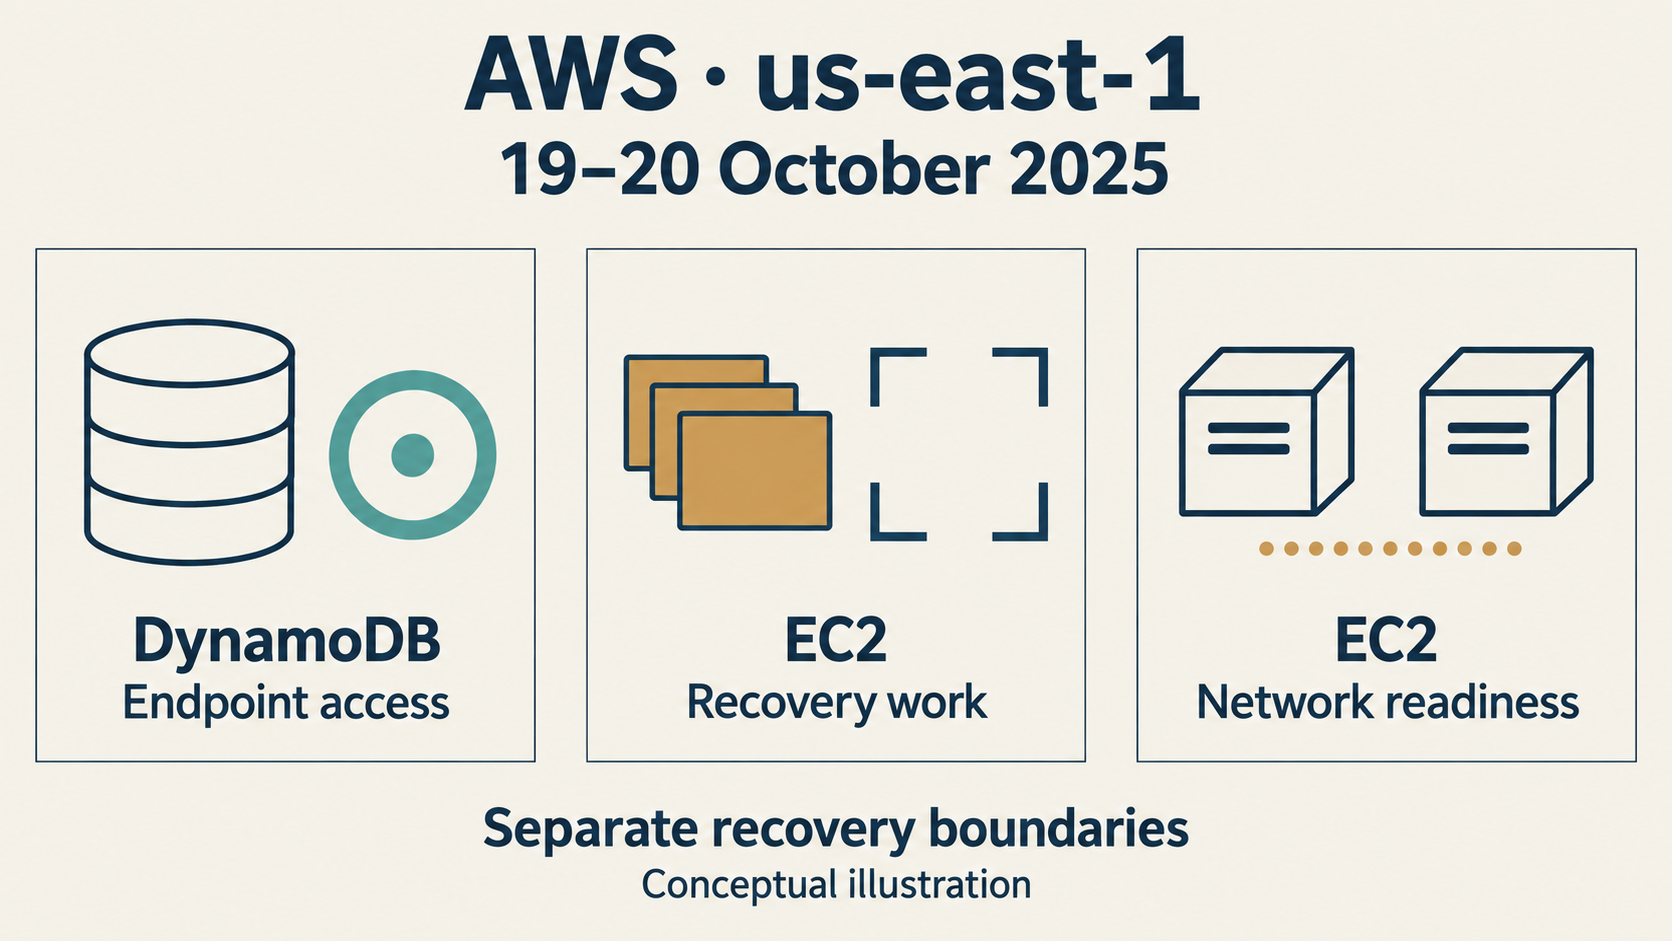
- ThousandEyes places DynamoDB DNS restoration at 09:25 UTC on October 20, 2025, but reports new EC2 launch failures or connectivity problems until 20:50 UTC. Those are different recovery milestones, not a uniform outage lasting between them. ThousandEyes analysis
- Dipak Kr das’s technical account describes accumulated lease-recovery work and a separate network-update backlog. Restoring access to the initiating dependency therefore did not finish the downstream recovery. Technical account on Medium
A system can become reachable again while the systems depending on it still have unfinished work. That is the important mechanism in the October 19–20, 2025 Northern Virginia incident involving Amazon Web Services. In Dipak Kr das’s account, DynamoDB’s return allowed EC2’s management machinery to resume work, but the volume of that work became another obstacle to recovery. The problem was no longer only whether a dependency could answer; it was whether downstream systems could make progress. Incident explanation
A DNS milestone, not an application all-clear
Dipak Kr das attributes the initiating DynamoDB endpoint-resolution failure to a latent race condition in automated DNS management. This is his explanation of the incident, not an independently established reconstruction presented here. The narrower chronology used below comes from ThousandEyes, which distinguishes restoration of DNS information from the subsequent return of successful connections. DNS explanation
ThousandEyes reports these milestones for October 20, 2025, all in UTC:
| Time | Reported state | What it does not establish |
|---|---|---|
| 09:25 | DynamoDB DNS information restored | Every client could immediately reconnect |
| 09:25–09:40 | Successful endpoint resolution and connections returned as cached records expired | Downstream provisioning had completed its recovery |
| Until 20:50 | New EC2 launches failed or experienced connectivity issues | Every launch failed continuously until that time |
The distinction is material: the final entry combines launch and connectivity impairment rather than identifying one uninterrupted failure affecting every request. ThousandEyes chronology
Subtracting 09:25 from 20:50 produces an interval of 11 hours 25 minutes. That measures the distance between the selected DNS-restoration milestone and the reported end of launch-or-connectivity impairment. It is not a customer outage duration, an application recovery measurement or an estimate of lost work. A single duration would conceal precisely the changing conditions that engineers needed to distinguish.
Recovery itself had work to complete
EC2’s Droplet Workflow Manager, or DWFM, is part of the management machinery for the physical servers hosting instances. ThousandEyes reports that DynamoDB unavailability prevented it from completing required state checks, disrupting lease management. Here, a lease means an internal, time-bounded management relationship—not the customer’s commercial rental agreement for a virtual machine. State-check dependency
Dipak Kr das’s account explains the next constraint. After DynamoDB returned, a surge of lease re-establishment work overwhelmed DWFM and prevented forward progress. Engineers responded by throttling incoming work and selectively restarting DWFM hosts. That describes a recovery problem caused by accumulated work, not merely a dependency that remained unreachable. Lease-recovery explanation
This distinction changes how to read the interventions. Limiting incoming work can help a congested system complete what is already pending. Selectively restarting an internal manager is also different from restarting customers’ virtual machines. The account concerns AWS’s internal management systems; it should not be turned into an instruction for customers to reproduce those actions on their own instances.
A second boundary remained after launch capability began to return. The same account describes a Network Manager backlog in propagating network state to newly launched instances. Some new instances consequently lacked connectivity or failed health checks. A launch could therefore advance further without yet delivering a machine ready to serve an application. This was reported as internal network-state propagation, not an Internet-wide routing failure. Network-update backlog
The sequence has several separate completion conditions: reach the dependency, restore management progress, finish the necessary network setup, and complete a useful application operation. Success at one condition is evidence about that condition. It is not proof that the others have been satisfied.
What surviving instances actually protected
Gremlin’s reliability account distinguishes instances started before the event, which it describes as staying healthy, from customers’ difficulties starting new instances after DynamoDB recovered. That is an important protection, but a limited one: continued instance execution does not establish end-to-end application availability. An application can still require a service or recovery operation outside the surviving machine. Gremlin’s reliability analysis
The evidence therefore supports separating existing execution from replacement or expansion capacity. It does not support saying that every workload failed, or that every surviving instance continued to deliver a healthy customer application. Nor do these accounts identify which particular customer could bypass a failed dependency through another zone or Region.
For a recovery design, the useful question is conditional: does keeping service running require creating something new while provisioning remains impaired? Existing capacity and capacity that must still be created are not interchangeable assurances. That does not make geographical redundancy useless; it makes the operations required to activate it part of the design that needs testing.
The limits of the reconstruction
This retrospective draws on technical analyses by ThousandEyes, Dipak Kr das and Gremlin, not an independent forensic audit. The detailed internal recovery mechanism remains an attributed explanation. These accounts do not establish a common recovery time for every AWS service or customer application, and they do not establish the effectiveness of today’s remediation.
The bounded lesson is nevertheless useful. Repairing the first failed dependency and restoring usable new capacity are different achievements. A recovery declaration should say which one has actually been demonstrated.
Member Briefing
Deeper Profile Context
Sign in with the right membership level to unlock the full briefing and source notes.
Only for Strategic Circle
Strategic Circle
Open to all readers. Unlock profile briefings after joining and signing in.
Join Strategic CircleOnly for Leadership Alliance
Leadership Alliance
For qualified IP-asset owners and management; sign in to unlock alliance briefings.
Join Leadership Alliance